
Running SQL on FlowFiles using QueryRecord Processor (Apache NiFi 1.2+)
Objective
This tutorial walks you through a NiFI flow that utilizes the QueryRecord processor and Record Reader/Writer controller services to convert a CVS file into JSON format and then query the data using SQL.
Note: The record-oriented processors and controller services were introduced in NiFi 1.2.0. As such, the tutorial needs to be done running Version 1.2.0 or later.
Environment
This tutorial was tested using the following environment and components:
- Mac OS X 10.11.6
- Apache NiFi 1.3.0
QueryRecord Flow
Support Files
Here is a template of the flow discussed in this tutorial: queryrecord-csvtojson.xml
Here is the CSV file used in the flow: users.txt (Change the extension from .txt to .csv after downloading)
Note: The CSV data originated from the site, RandomUser. This useful site provides a free API to pull down randomly generated user data. For example: https://randomuser.me/api/0.6/?results=10&format=SQL.
Demo Configuration
Input Directory
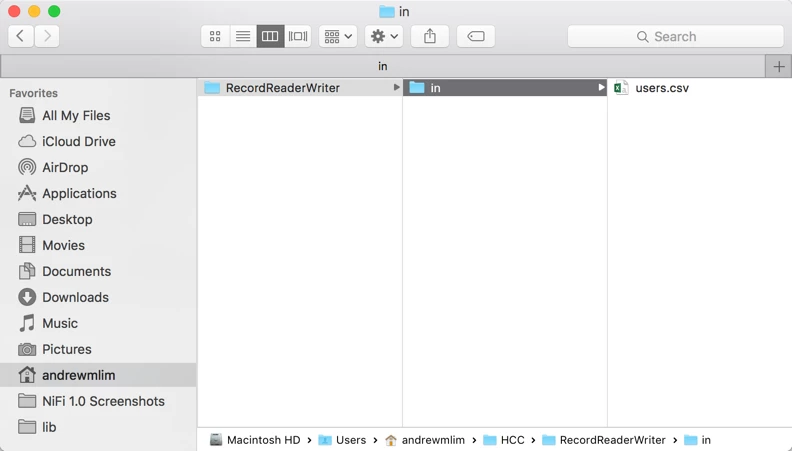
Create a local input directory. Place the "users.csv" file in the input directory.
Import Template
Start NiFi. Import the provided template and add it to the canvas.
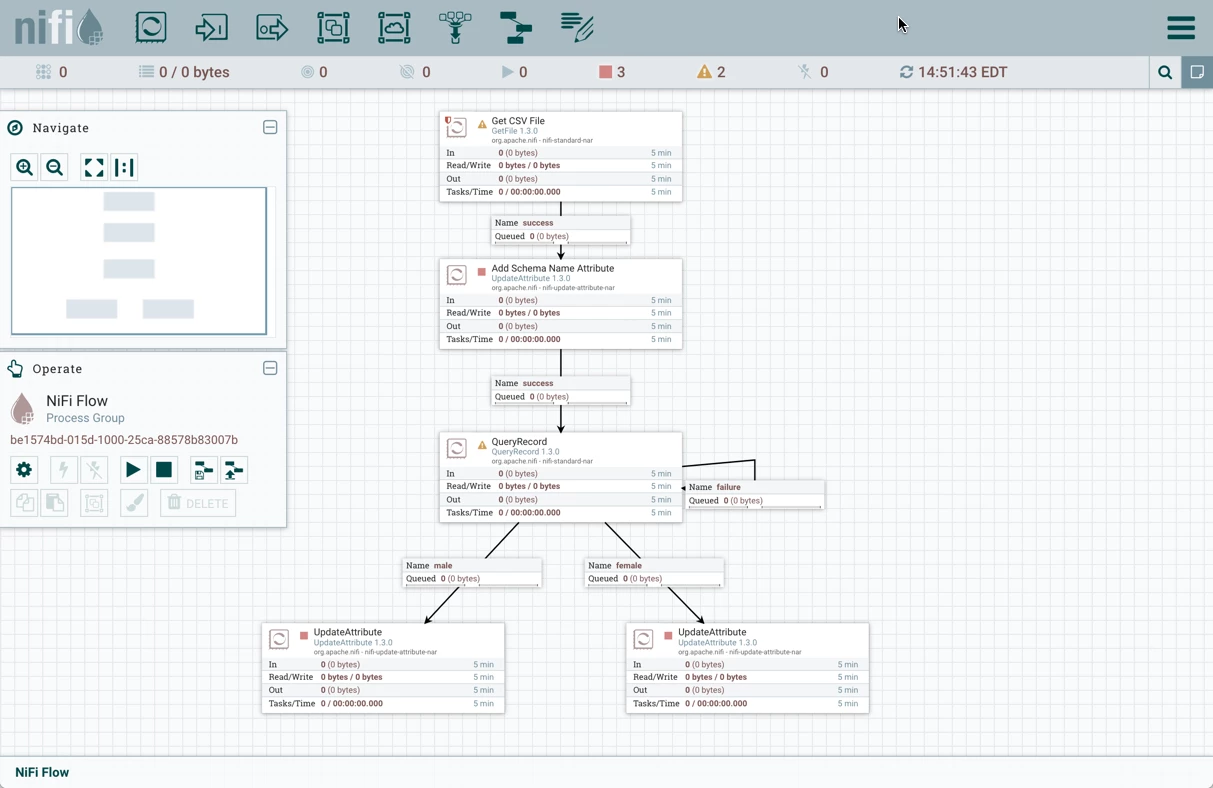
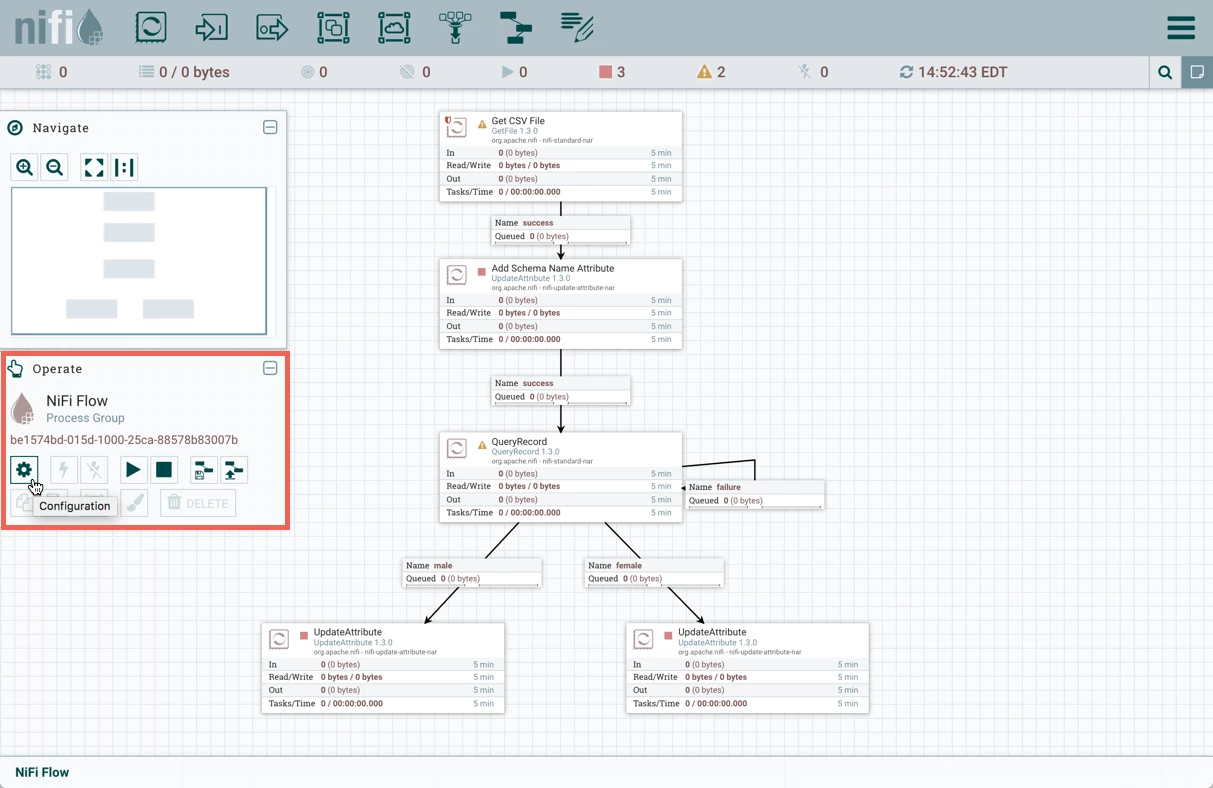
You should see the following flow on your NiFi canvas:
Enable Controller Services
Select the gear icon from the Operate Palette:
This opens the NiFi Flow Configuration window. Select the Controller Services tab:
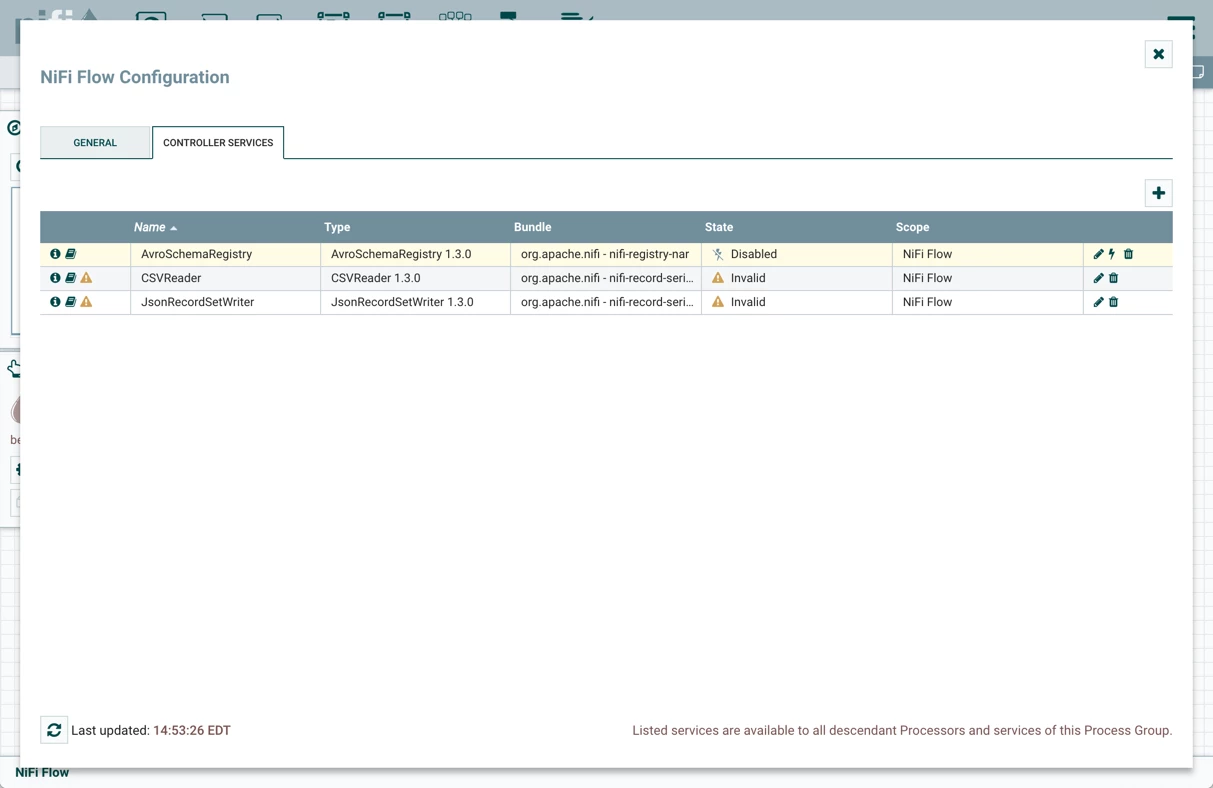
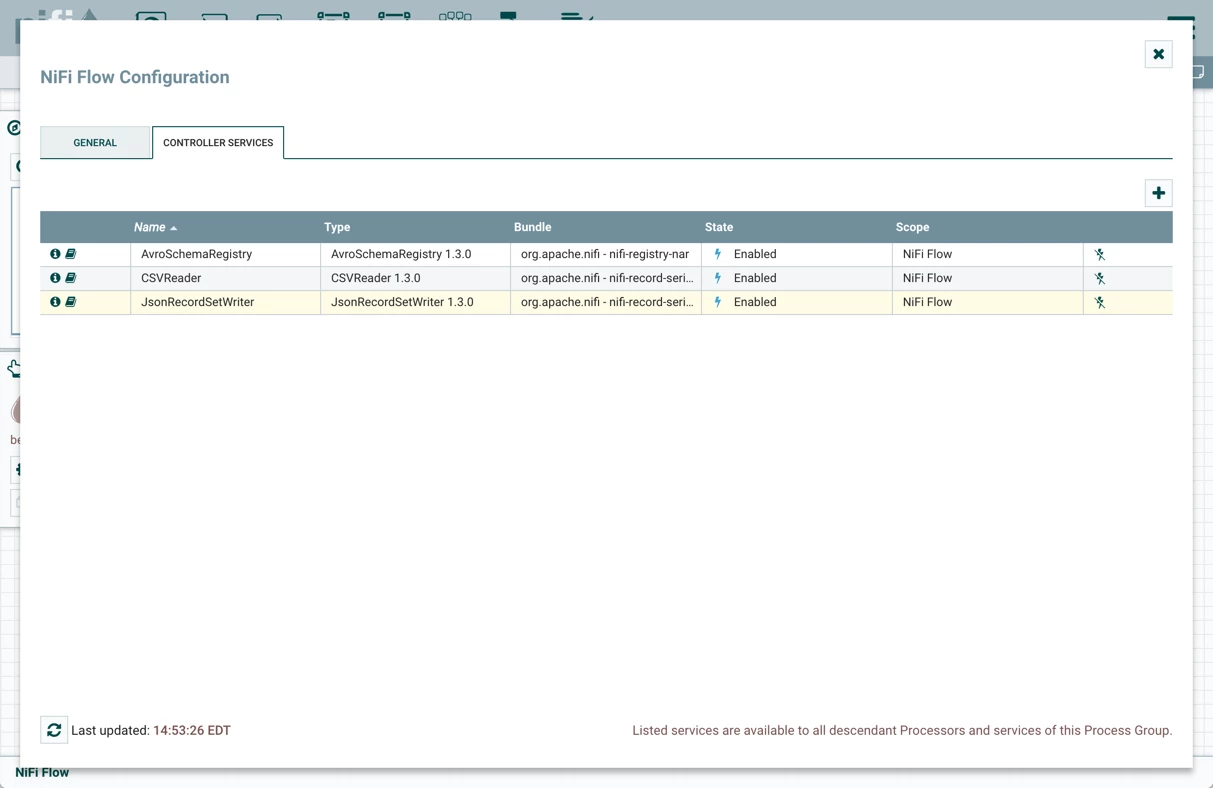
Enable AvroSchemaRegistry by selecting the lightning bolt icon/button. This will then allow you to enable the CSVReader and JSONRecordSetWriter controller services. Select the lightning bolt icons for both of these services. All the controller services should be enabled at this point:
Update Directory Path in GetFile Processor
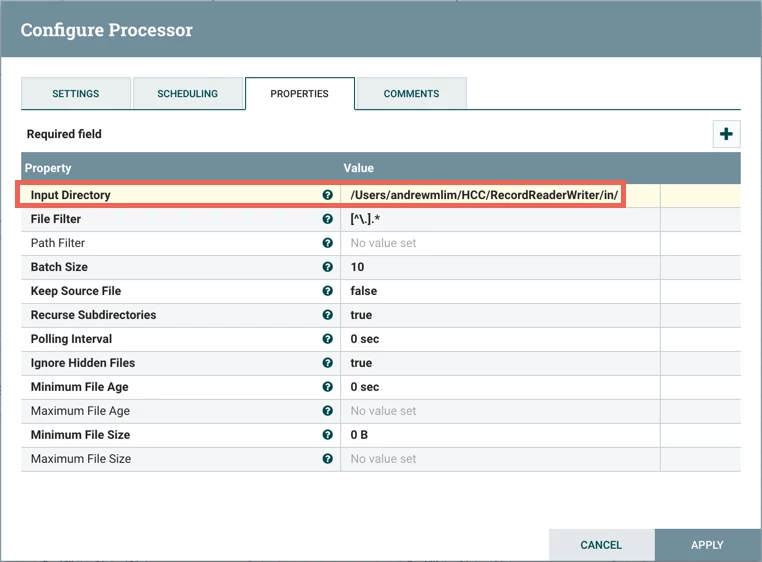
Change the Input Directory path in the GetFile processor to point to your local input directory:
The flow is now ready to run.
Flow Overview
Here is a quick overview of the flow:
1. GetFile ingests a CSV file of user data from a local directory
2. UpdateAttribute adds Schema Name "users" as an attribute to the flowfile
3. QueryRecord converts the flowfile contents from CSV to JSON by:
- Using a CSVReader controller service that references a schema in an AvroSchemaRegistry controller service
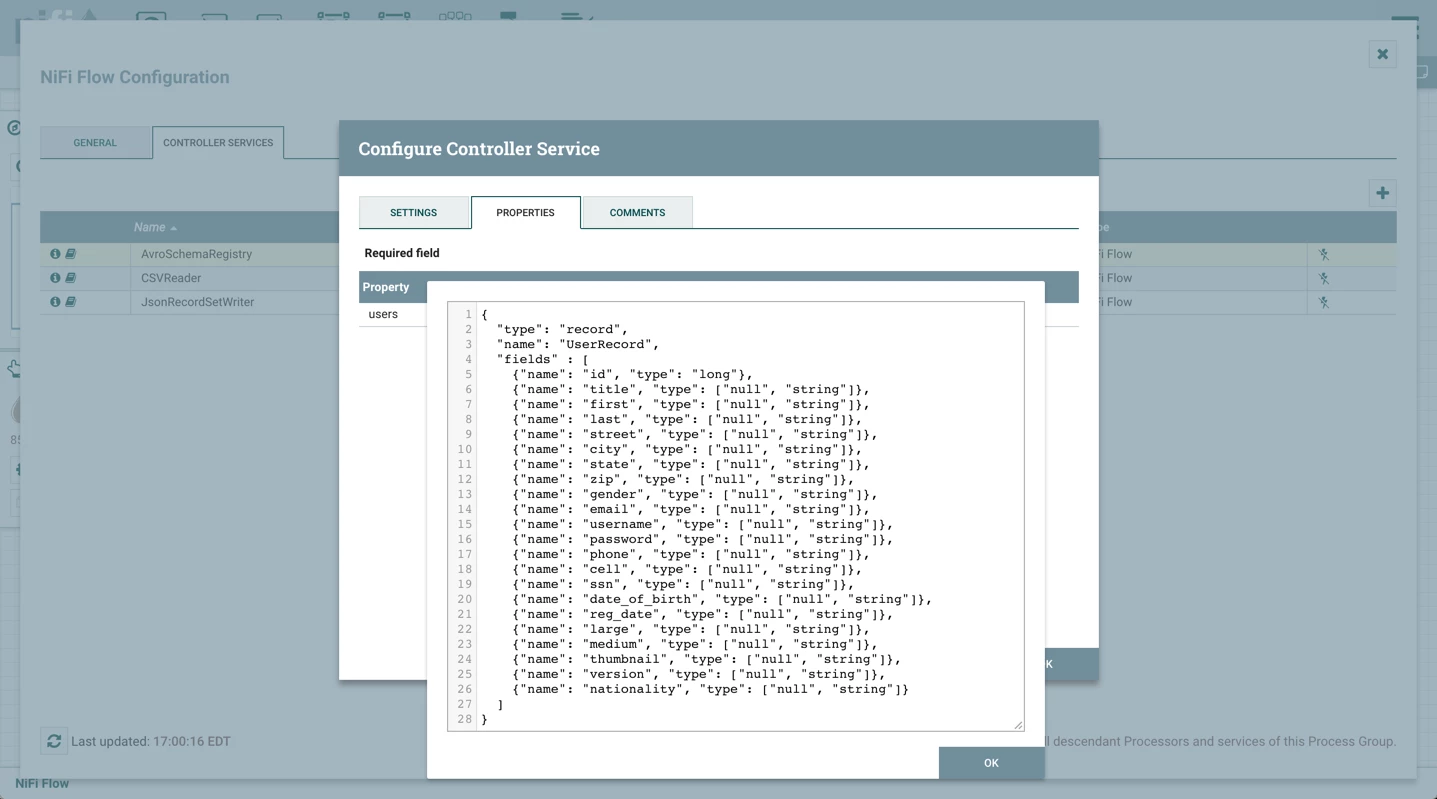
- The AvroSchemaRegistry contains a "users" schema which defines information about each record (field names, field ids, field types)
- Using a JsonRecordSetWriter controller service that references the same AvroSchemaRegistry schema
4. QueryRecord queries the flowfile using SQL:
- The "female" property uses SQL to select rows from the data where gender = 'F'
- The "male" property uses SQL to selects rows from the data where gender = 'M'
5. The female and male user data are sent to UpdateAttribute processors to provide a simple place to hold the data.
Flow Details
Let's look at each of the processors in the flow in detail:
Get CSV File (GetFile Processor)
FlowFiles are generated from the users.csv file in the local directory. Start the processor:
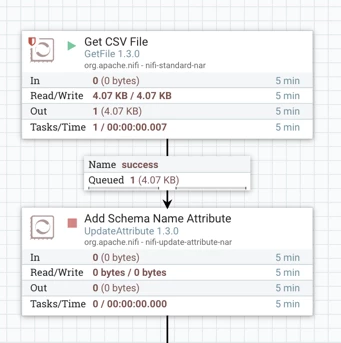
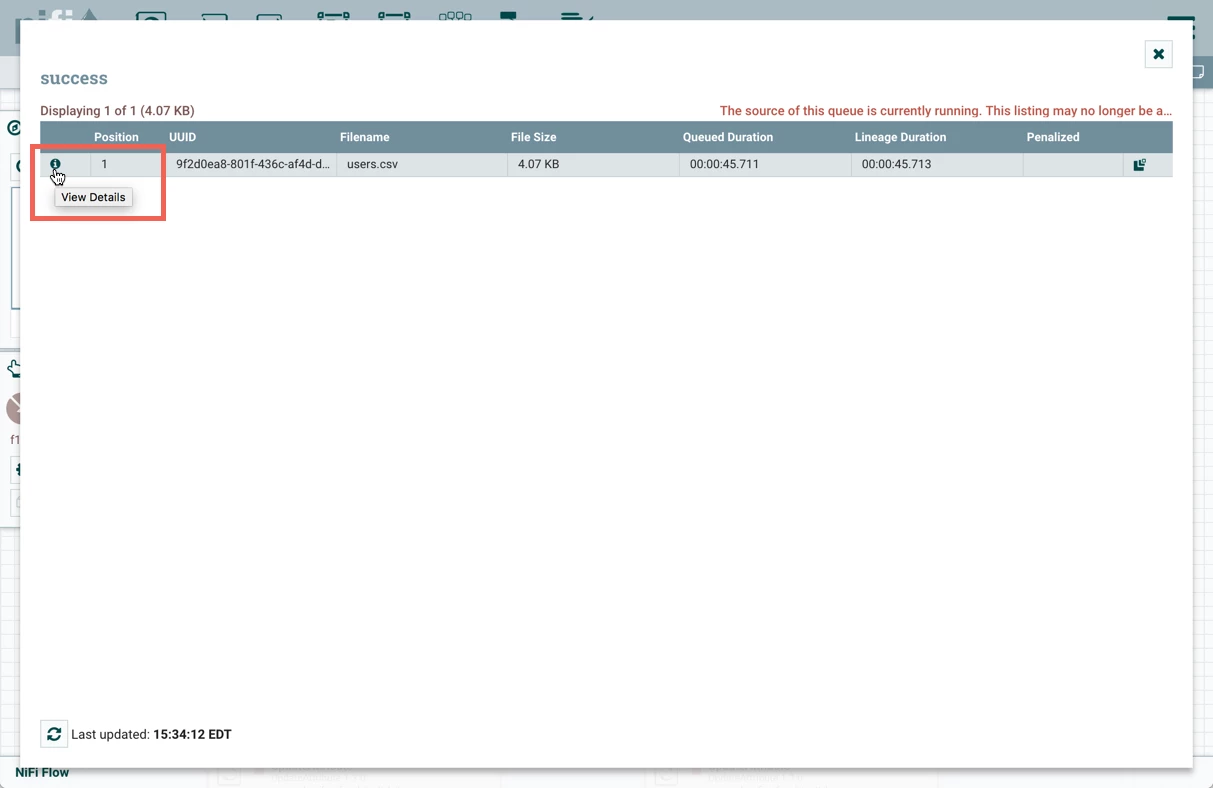
One flowfile is generated with the CSV data as the contents. Right click on the connection between the GetFile Processor and the UpdateAttribute Processor. In the context menu, select "List Queue" and click the View Details button ("i" icon):
From the FlowFile window that opens, select the "View" button from the Details tab:
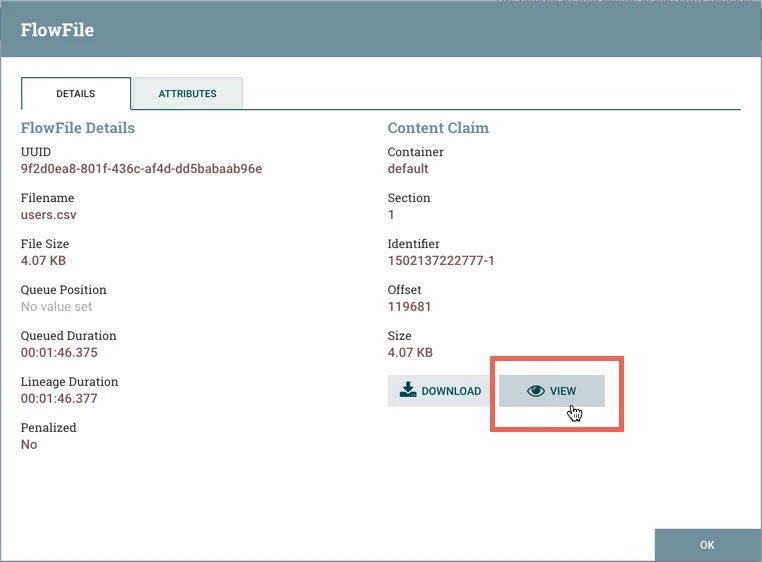
to view the CSV contents of the flowfile:
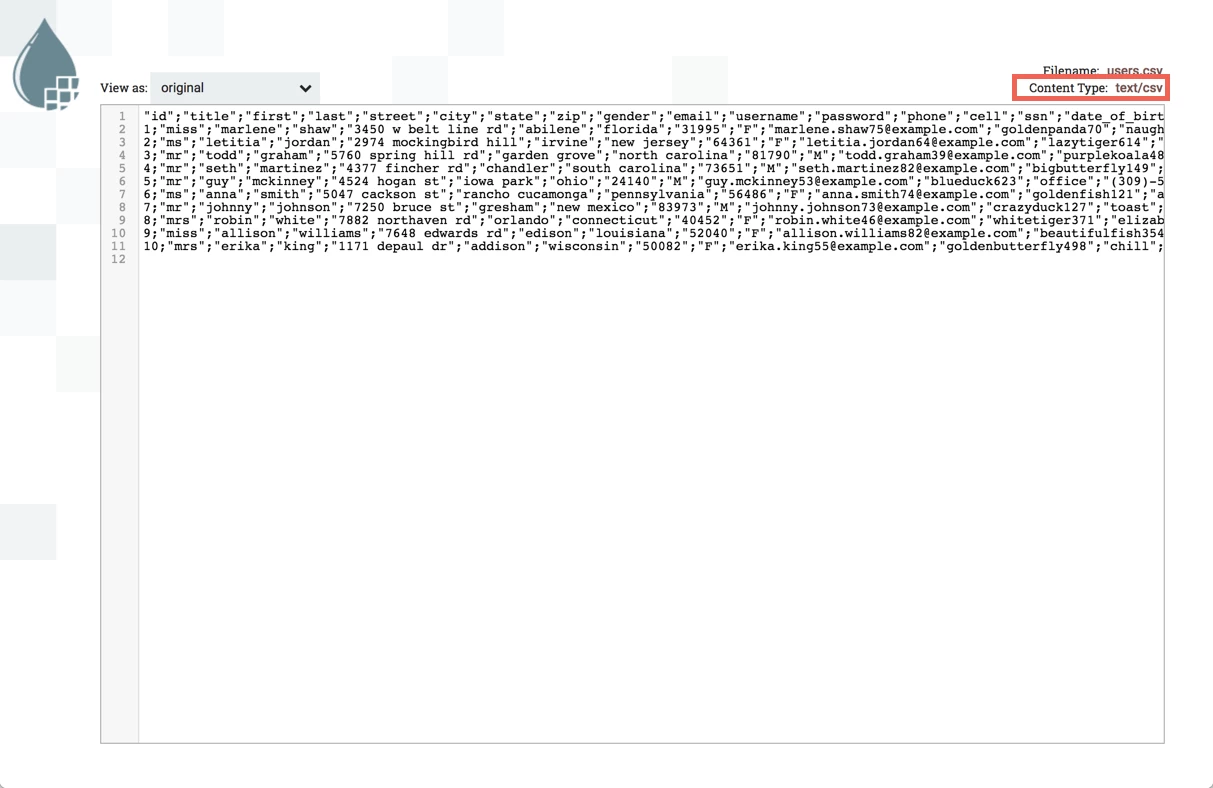
Note that there are 10 total users.
Add Schema Name Attribute (UpdateAttribute Processor)
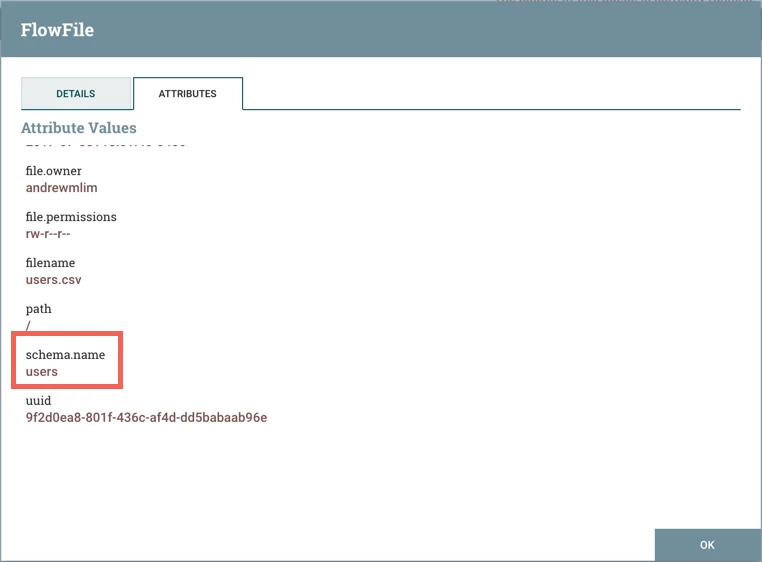
The next step in the flow is an UpdateAttribute processor which adds the schema.name attribute with the value of "users" to the flowfile:
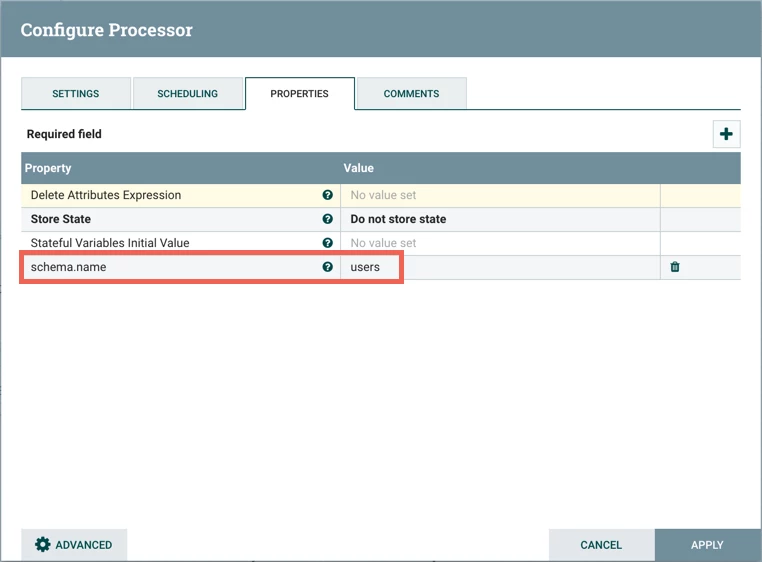
Start the processor, and view the attributes of the flowfile to confirm this:
QueryRecord Processor
The next processor, QueryRecord, allows users to write SQL SELECT statements to run over their data as it streams through the system. Each FlowFile is treated as if it were a database table named FLOWFILE. Multiple SQL queries can be added to the processor. Looking at the configuration:
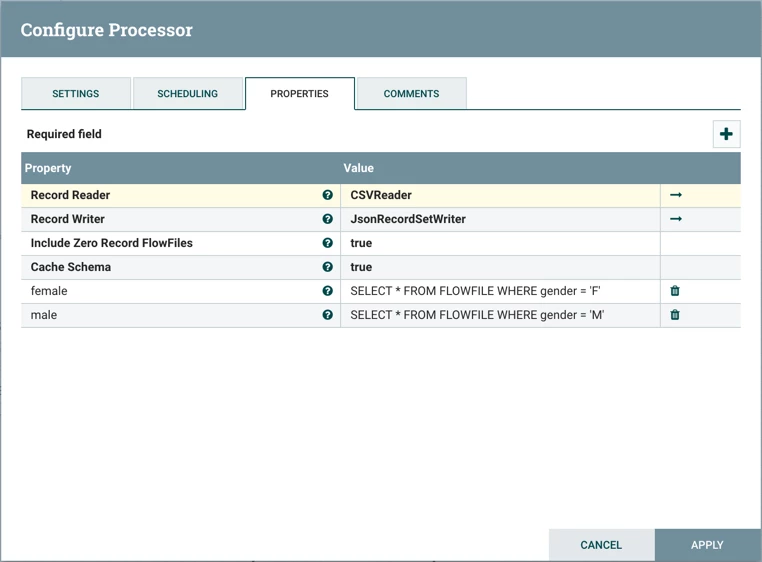
Record Reader is set to "CSVReader" and Record Writer is set to "JsonRecordSetWriter". The "CSVReader" controller service parses the incoming CSV data and determines the data's schema. The "JsonRecordSetWriter" controller service determines the data's schema and writes that data into JSON. More details about these controller services can be found below.
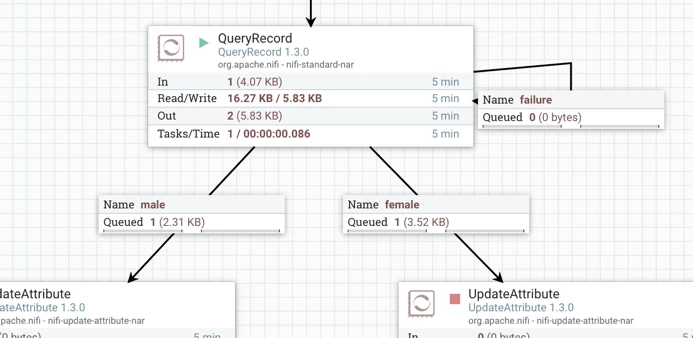
In order to distinguish the results of each query and route the data appropriately, the name of the property is the name of the Relationship that data matching the query should be routed to. The first added property is named "female" and will include user data where the gender of the user is "F":
  SELECT *
  FROM FLOWFILE
  WHERE gender = 'F'
(NOTE: When entering a value for a property in NiFi, you can use Shift + Enter to insert a newline in your value.)
The second property is named "male" and will include user data where the gender of the user is "M":
  SELECT *
  FROM FLOWFILE
  WHERE gender = 'M'
CSVReader Controller Service
Select the arrow icon next to the "CSV Reader" which opens the Controller Services list in the NiFi Flow Configuration. "CSVReader" should be highlighted in the list. Select the View Details button ("i" icon) to see the properties:
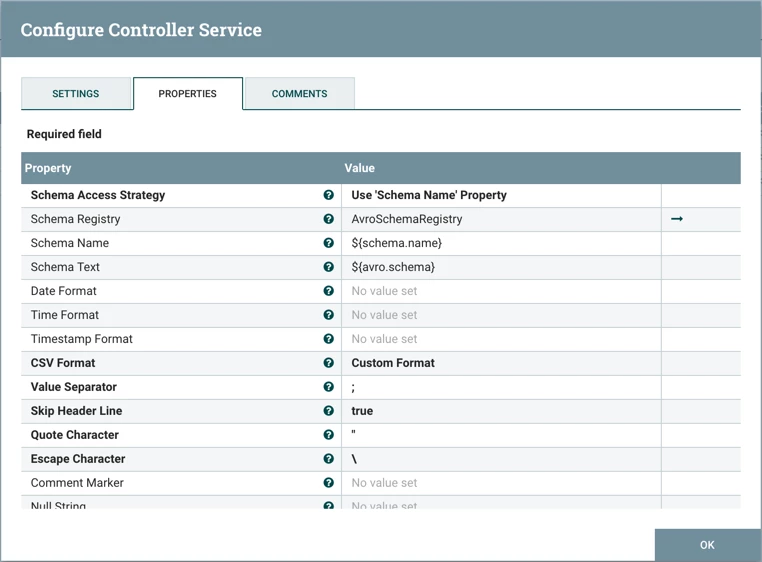
With Schema Access Strategy property set to "Use 'Schema Name' Property", the reader specifies the schema expected in an attribute, which in this flow is schema.name. The Schema Registry property is set to the AvroSchemaRegistry Controller Service which defines the "users" schema. Select the arrow icon next to "AvroSchemaRegistry" and select the View Details button ("i" icon) to see its properties:
JsonRecordSetWriter Controller Service
Close the window for the AvroSchemaRegistry. Select the View Details button ("i" icon) next to the "JsonRecordSetWriter" controller service to see its properties:
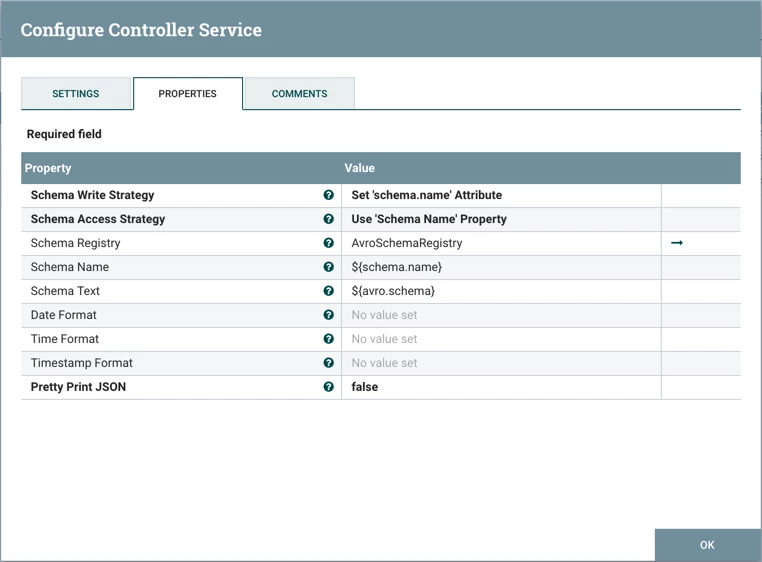
Schema Write Strategy is set to "Set 'schema.name' Attribute", Schema Access Strategy property is set to "Use 'Schema Name' Property" and Schema Registry is set to AvroSchemaRegistry.
Start the QueryRecord processor. The flowfile is now split into two flowfiles:
Looking at the contents of the "female" connection confirms the expected results of 6 female users in JSON format:
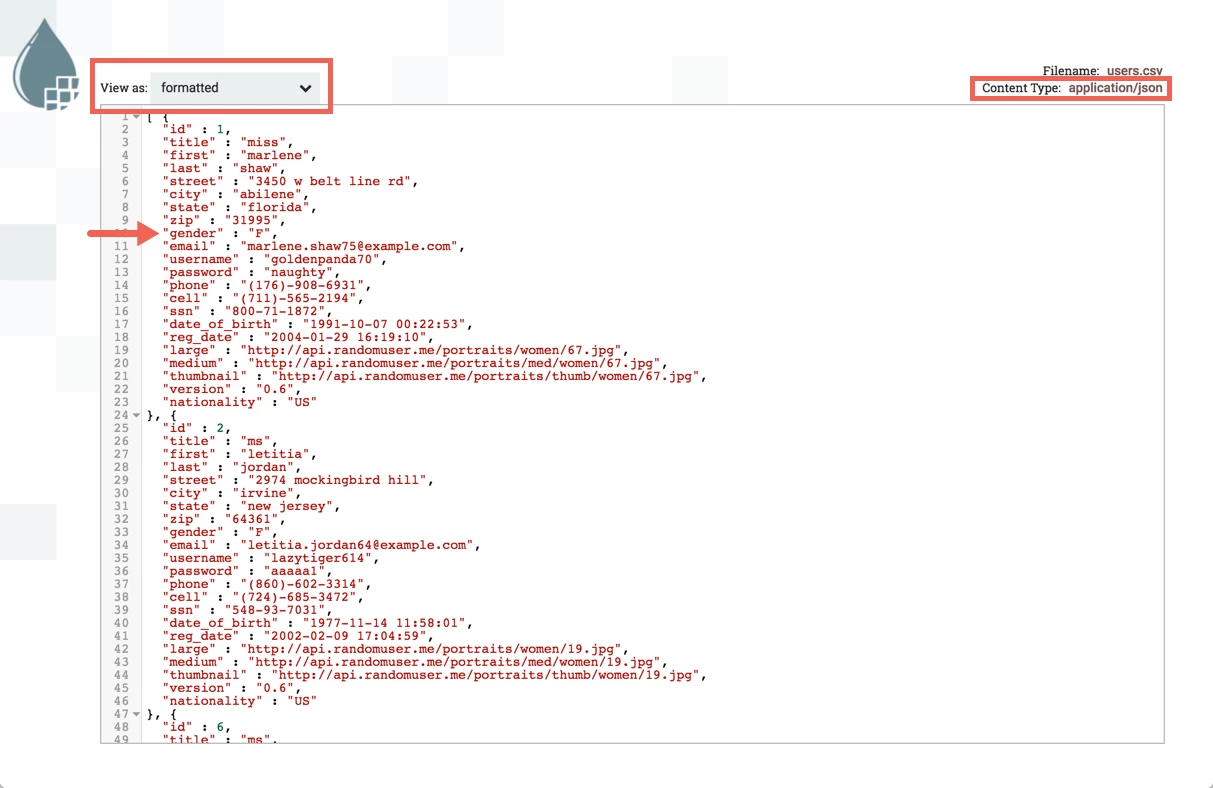
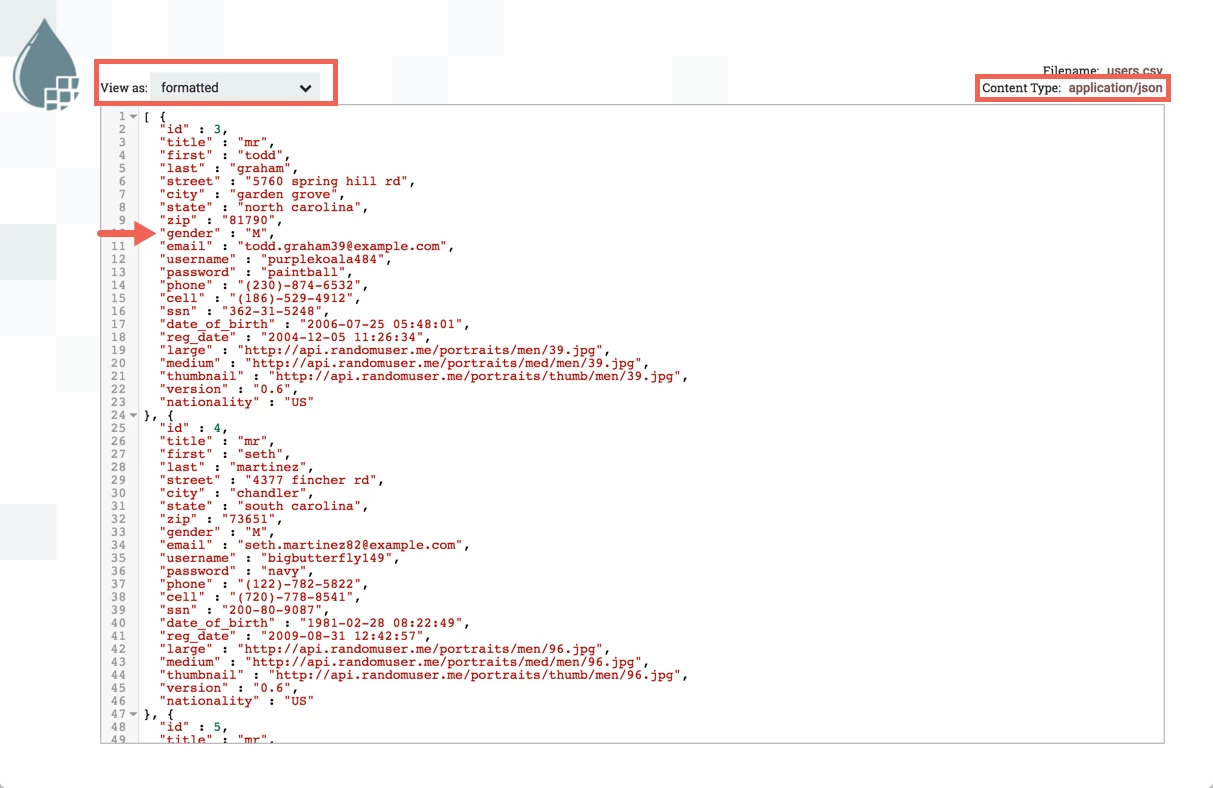
Looking at the contents of the "male" connection confirms the expected results of 4 male users in JSON format:
The SQL queries in the flow are very basic for the purposes of this tutorial. The beauty of the QueryRecord processor is that it supports the SQL for more advanced queries and operations, such as filtering specific columns/rows/fields from your data, renaming those columns/rows/fields, performing calculations and aggregations on the data. Enjoy exploring the capabilities of this new functionality!
Helpful Links
Here are some links to check out if you are interested in more information on the record-oriented processors and controller services in NiFi:

