


Fractional cores in CDE Spark
- October 5, 2026 at 8:52 AM
- 0 replies
- 2923 views
- Translate All
Introduction
When working with CDE in CDP Public Cloud, there may be a need to allocate fractions of CPU to our Spark Jobs, without losing parallelism. Following are some of the real scenarios:
- Spark application that reads from HBase and performs CPU-light processing, causing a significant I/O wait. Reducing the number of executors or cores per executor is not optimal because the parallel reads from HBase scale linearly, increase the job duration.
- Spark application that needs high parallelism for the data processing, but before writing the data to HDFS, the partitions are coalesced to a smaller number to avoid creating many small files. So the single job uses all the assigned cores during processing and less cores during the output, leaving some CPU idle.
Steps
To allocate fractions of CPUs to Spark in CDE, we need to set the 'spark.kubernetes.executor.request.cores' config. This could be set to 0.1, 500m, 1.5, 5, etc. More details on official Spark documentation.
So, let's define a simple job in CDE, specifying 16 executors with each
- 2 CPU
- 6 GB ram
Running this first job, we can see that we used 31 CPUs in total
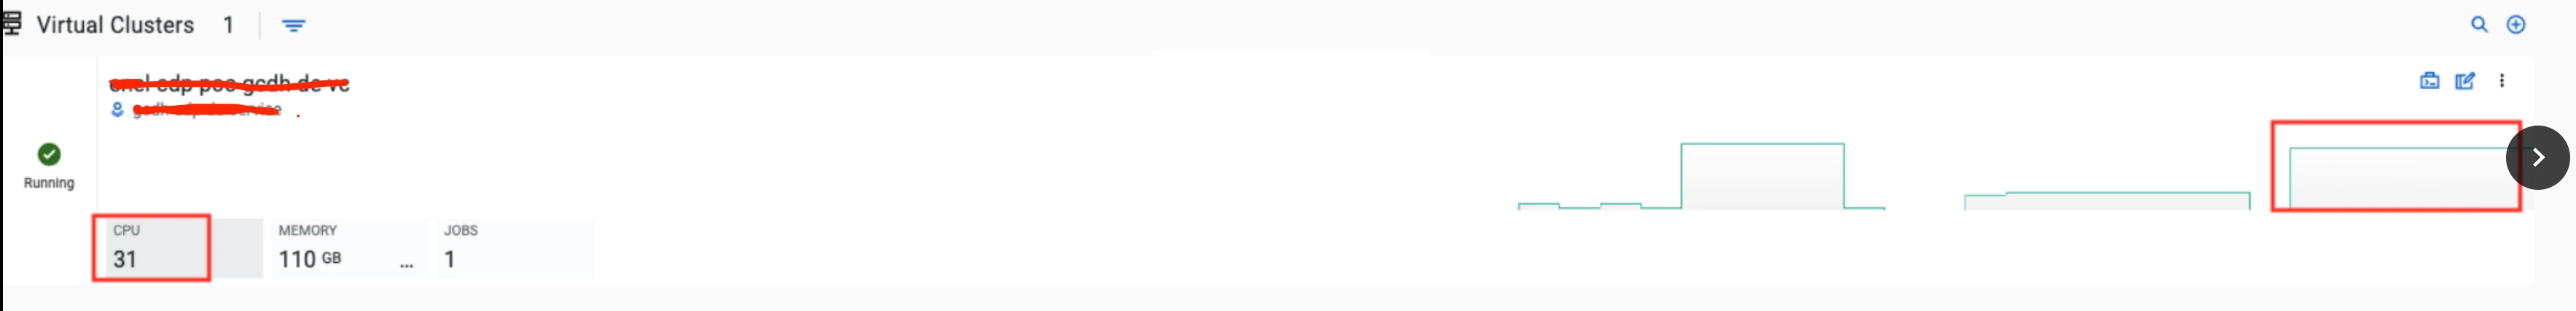 job 1 without fractioned cpus
and looking to the Spark UI, 2 cores and 2 tasks are reported for each executor, as expected:
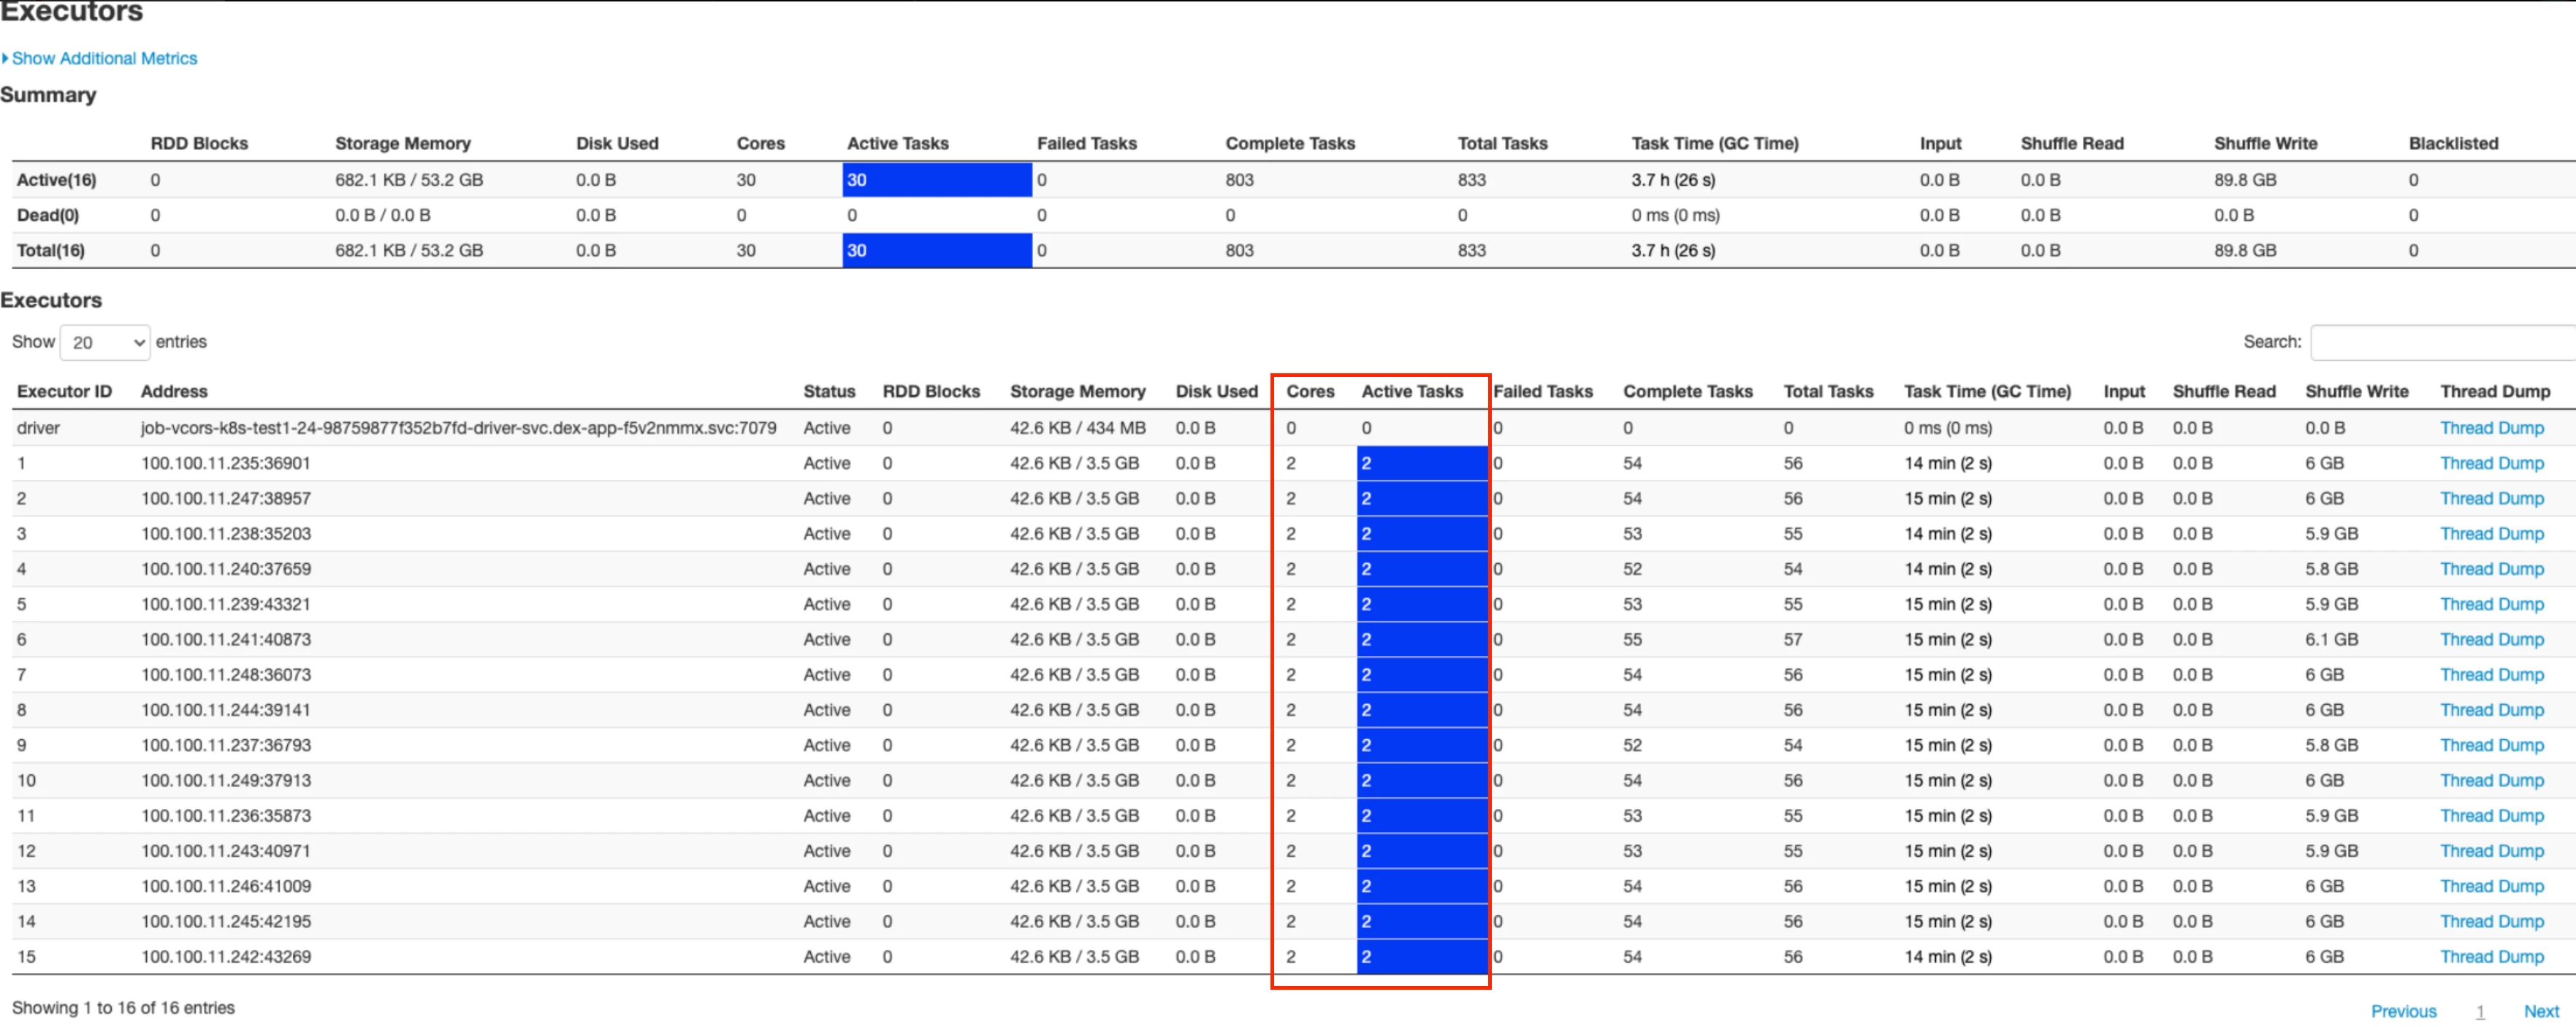 spark ui without fractioned cpus
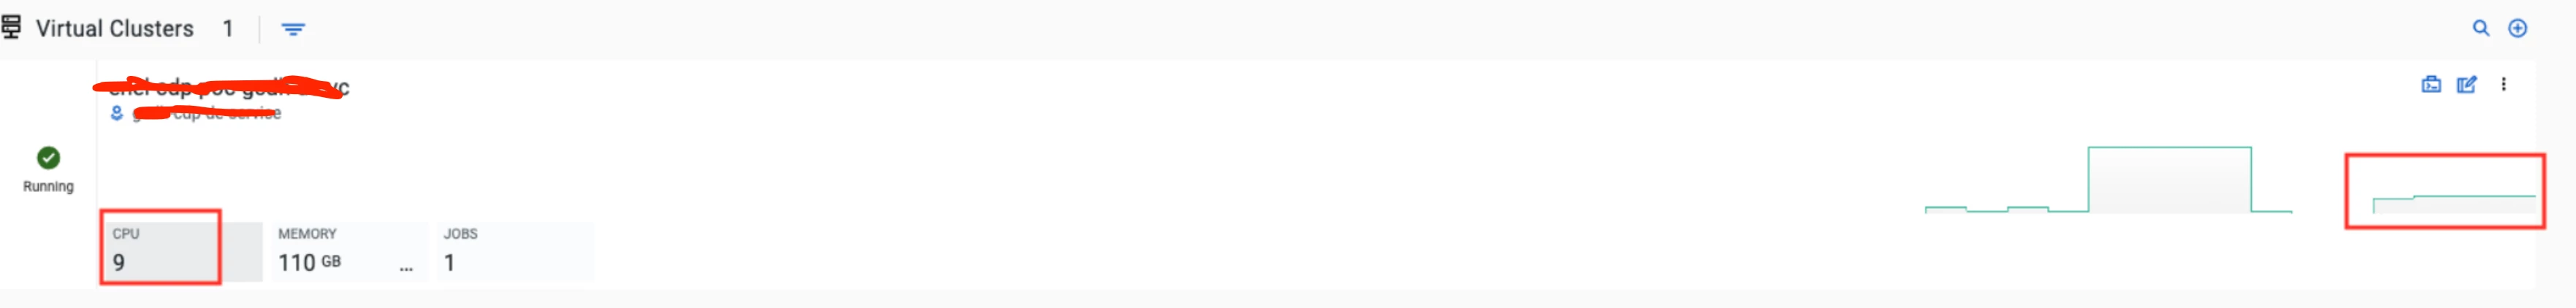 spark job with fractioned cpu option
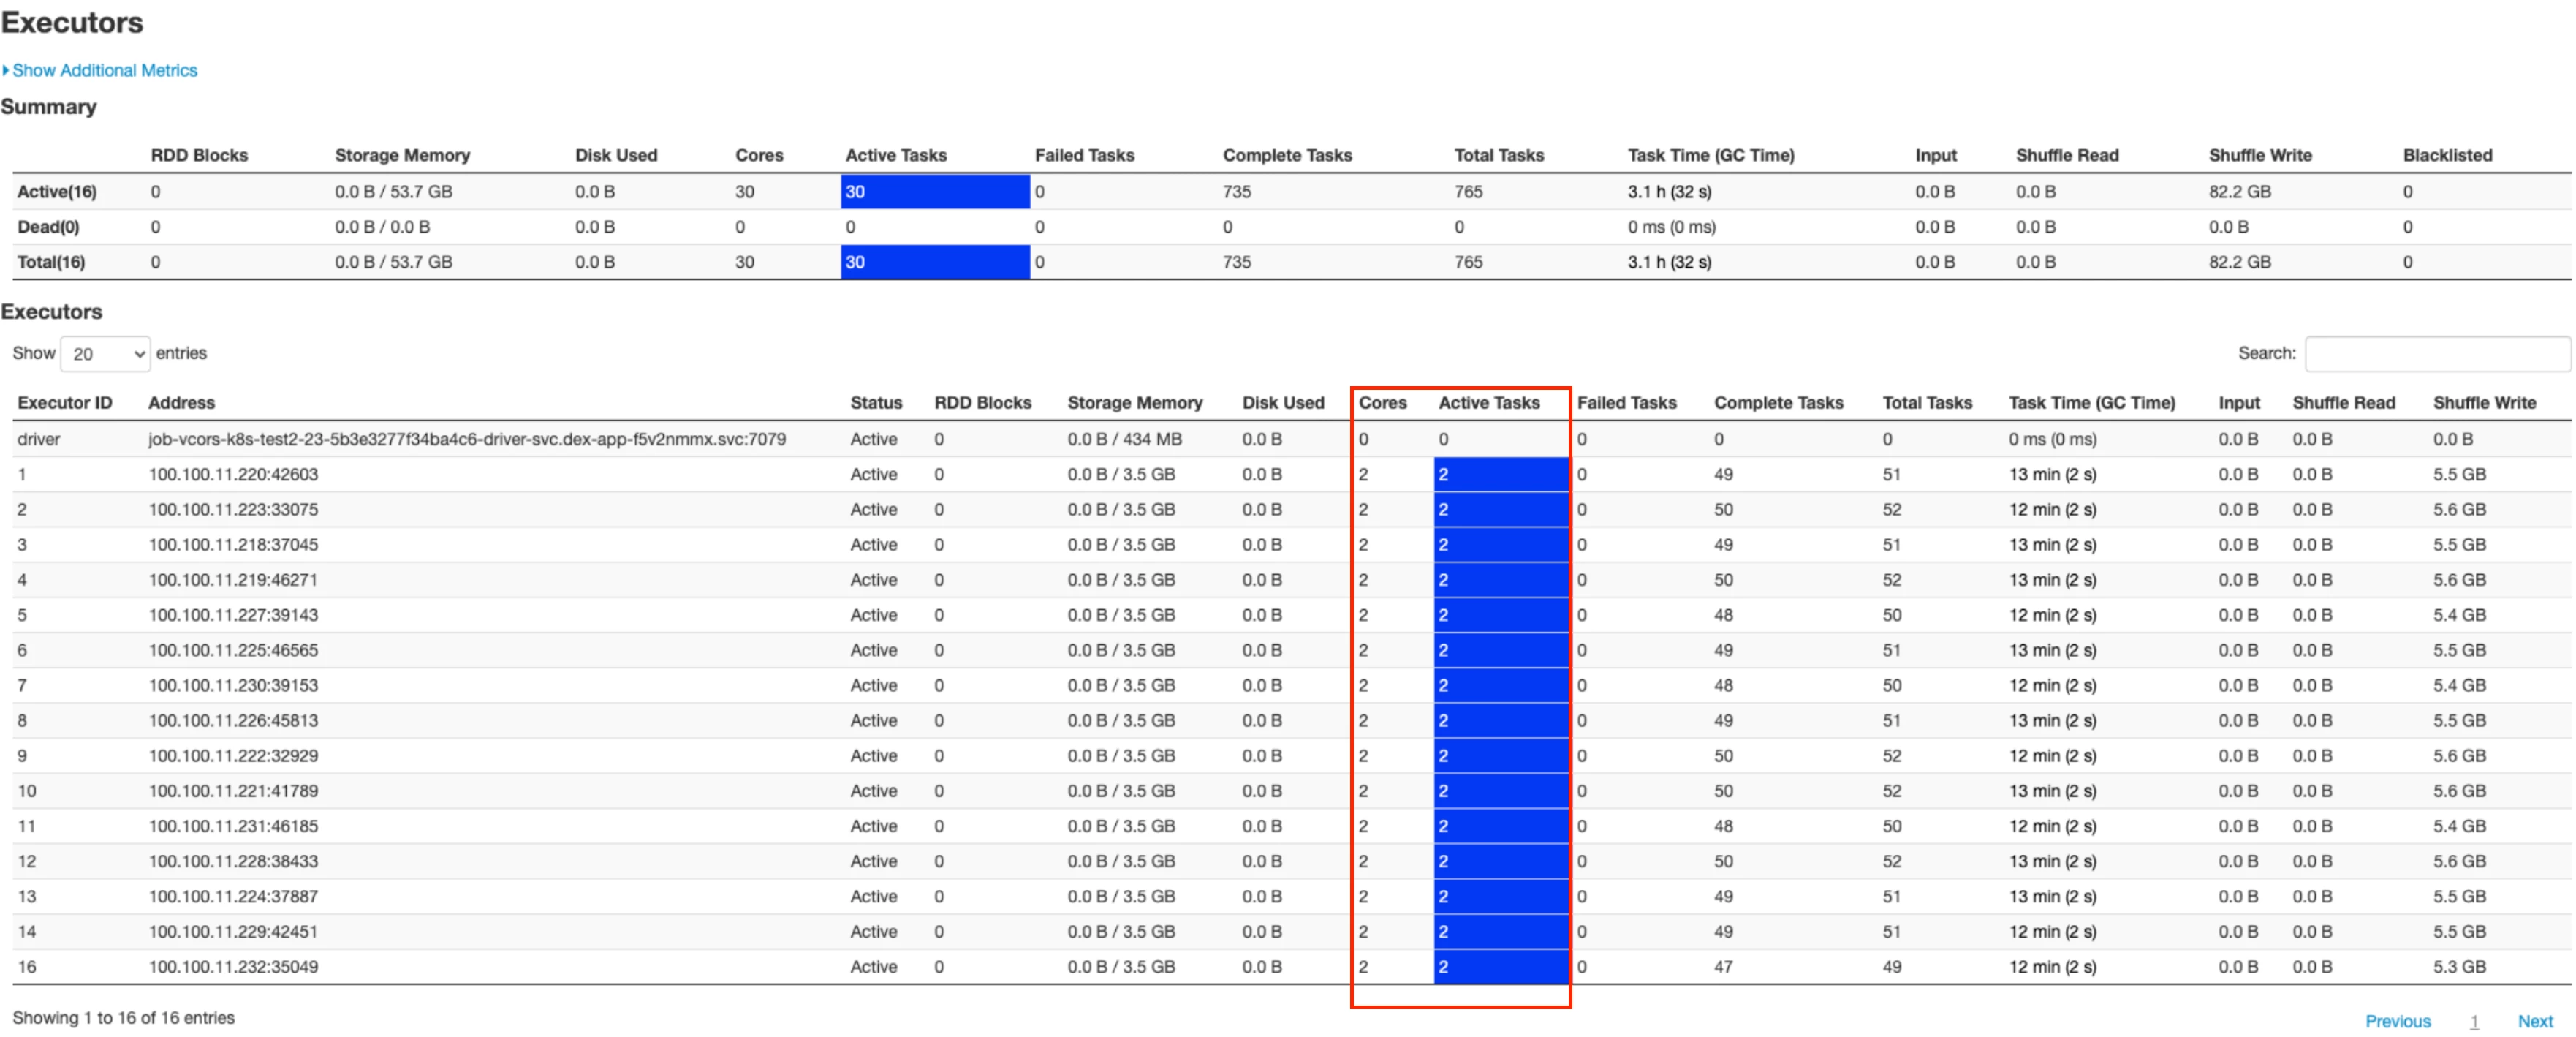 spark ui with fractioned cpus option
Conclusion
This post provided an example to allocate fractions of CPUs to our Spark jobs, without losing parallelism.

