


Nifi and Druid for real time dashboarding for industrial systems (IOT)
This article goes on how Nifi, with the of the OPC UA api along with Druid for dashboarding can help with industrial iot use cases. We have seen a trend where several clients have shown interest in HDP as a platform for storing all of the sensor data and third party data. This allows these companies store their sensor data over a longer period of time, easily corelate them with other data sets and enrich them in a very cost effective manner. Additionally, they can run ML algorithms on this data set to better predict outages, malfunctions or maintenance. Using NiFi,Kafka and Druid, can provide means for a very easy to maintain and superfast ingestion mechanism from the several edge devices be it windmills, substations, meters etc. Druid can then provide a robust platform for real-time querying dashboarding on this sensor data so operations can keep an eagle eye on whats going on at a plant or wind farm.
For the pupose of this article, i will be consuming data from a demo OPC server which is running some simulation , that generates sample data signals, Ramp,Sinusoid, Square etc. The simulation generates a data point for each signal every second.
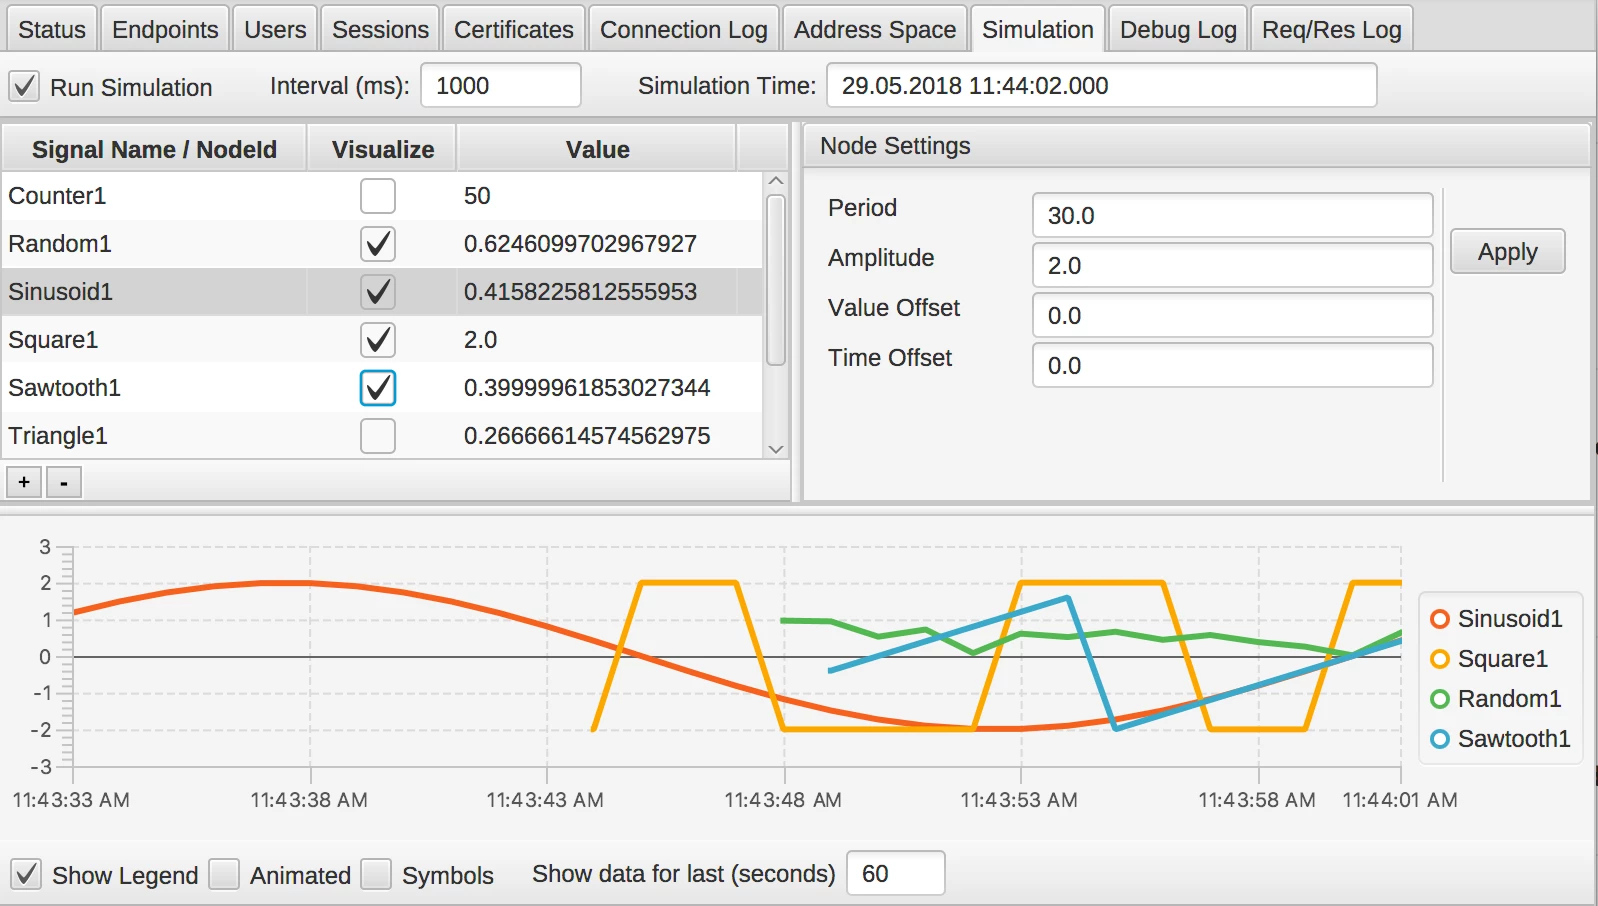
To ingest this data into Druid, i will be using the kafka streaming ingestion option available in druid. But, Kafka by itself can be very complicated for someone in the industrial background to work with, especially since many may not be exposed to this technology. Hence, instead of writing java applications that produce data into Kafka, we need a mechanism that hides these complexiites away and helps the engineers to foucs not on the platform, but more on the use case. NiFi, is an ideal choice for this with its GUI interface and seemless connectivity to kafka.
To allow nifi to connect and consume data from the OPC server, we will be using the eclipse Milo library, which communicates with the server over OPC UA. To make it easy and reproducable, i created a custom processor . The repository is located here. Simply clone the repo. build using mvn clean package -Dskiptests. Once the processor is built just copy the .nar file to nifi/lib folder. Restart Nifi. Developed a nifi flow using the opc processor to extract data from the opc server and publishkafka to push data to a kafka topic.
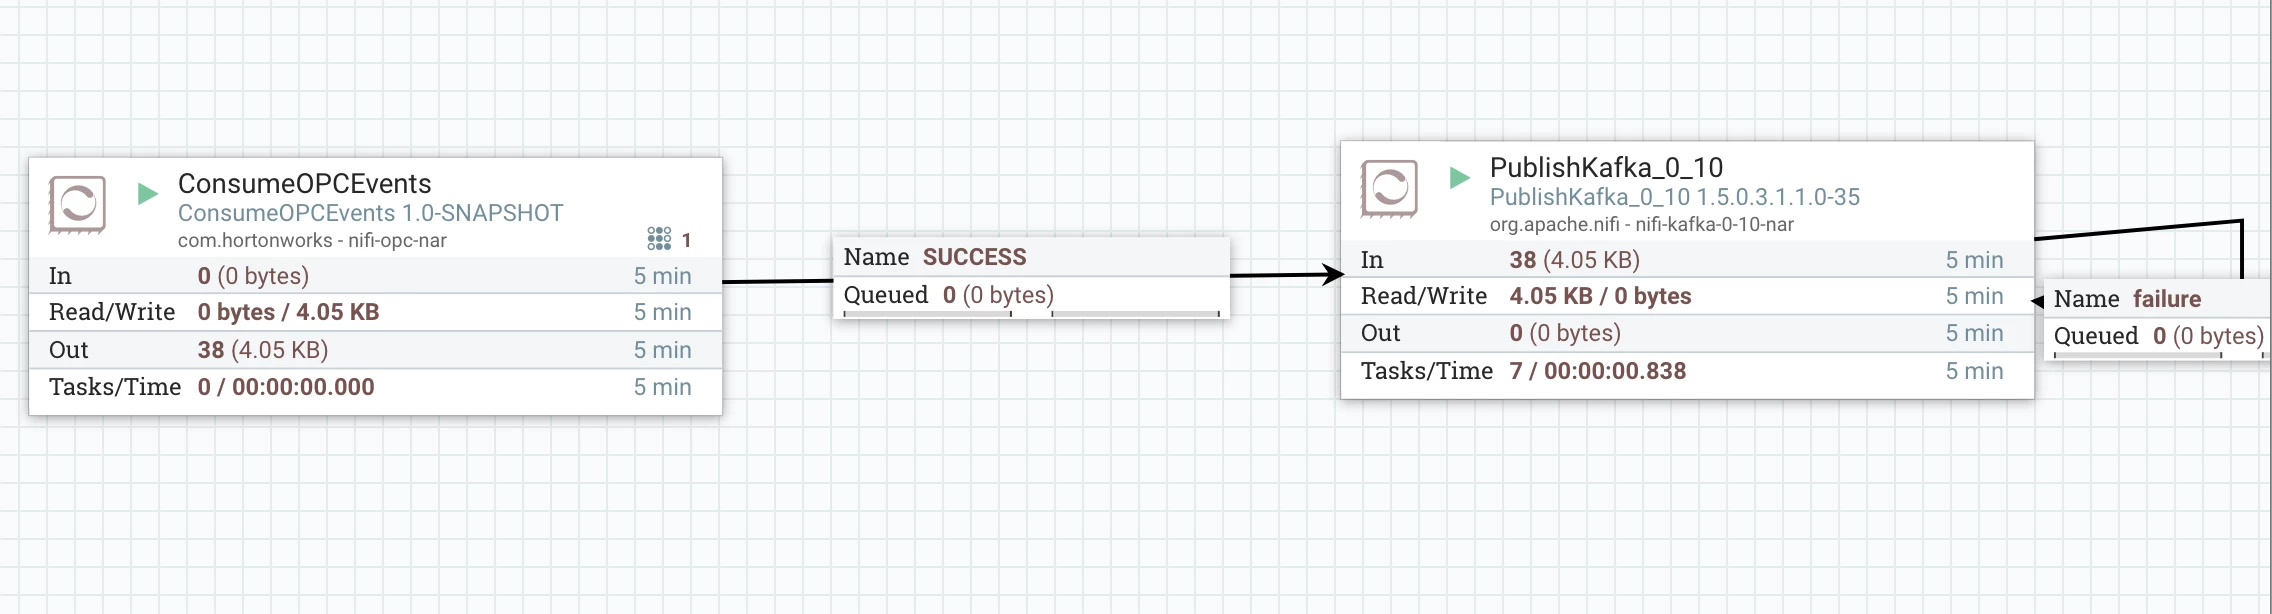
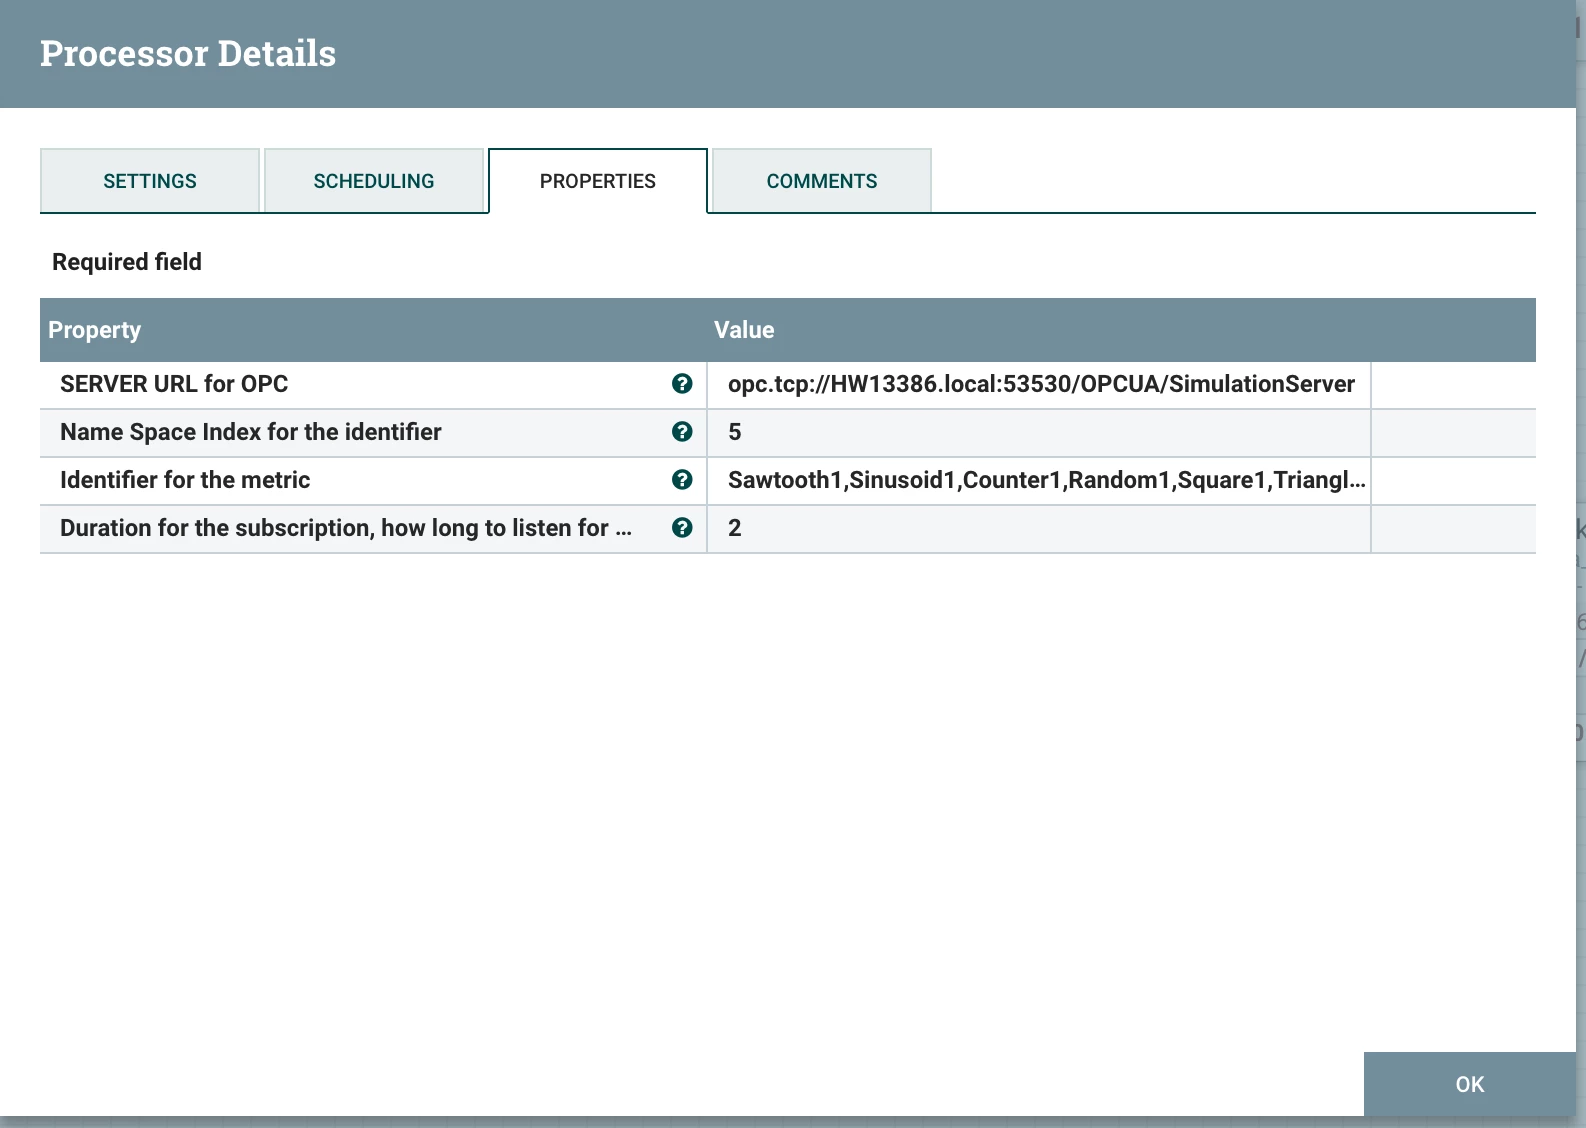
The consumeopc events processor was configured as below.
Once flow is configured and started, you should see data being to the kafka topic. Now we will configure the druid kafka ingestion spec. This let druid run real time jobs that will pull data from kafka topic into druid real time nodes for segmenting.
{
  "type": "kafka",
  "dataSchema": {
    "dataSource": "iot_ds",
    "parser": {
      "type": "string",
      "parseSpec": {
        "format": "json",
        "timestampSpec": {

          "column": "timestamp",
          "format": "yyyy-MM-dd'T'HH:mm:ss.SSS zzz"
        },
        "dimensionsSpec": {
          "dimensions": ["Identifier"]
        }
      }
    },
    "metricsSpec": [
      {
        "name": "count",
        "type": "count"
      },
      {
        "name": "value_sum",
        "fieldName": "value",
        "type": "doubleSum"
      }
    ],
    "granularitySpec": {
      "type": "uniform",
      "segmentGranularity": "NONE",
      "queryGranularity": "NONE"
    }
  },
  "tuningConfig": {
    "type": "kafka",
    "maxRowsPerSegment": 400
  },
  "ioConfig": {
    "topic": "iot_metrics",
    "consumerProperties": {
      "bootstrap.servers": "seregion3.field.hortonworks.com:6667"
    },
    "taskCount": 1,
    "replicas": 1,
    "taskDuration": "PT1H"
  }
}
Create the above spec , make sure to modify the kafka bootstrap.server to your environment. Then post this spec to druid
curl -X POST -H 'Content-Type: application/json' -d @supervisor-spec.json 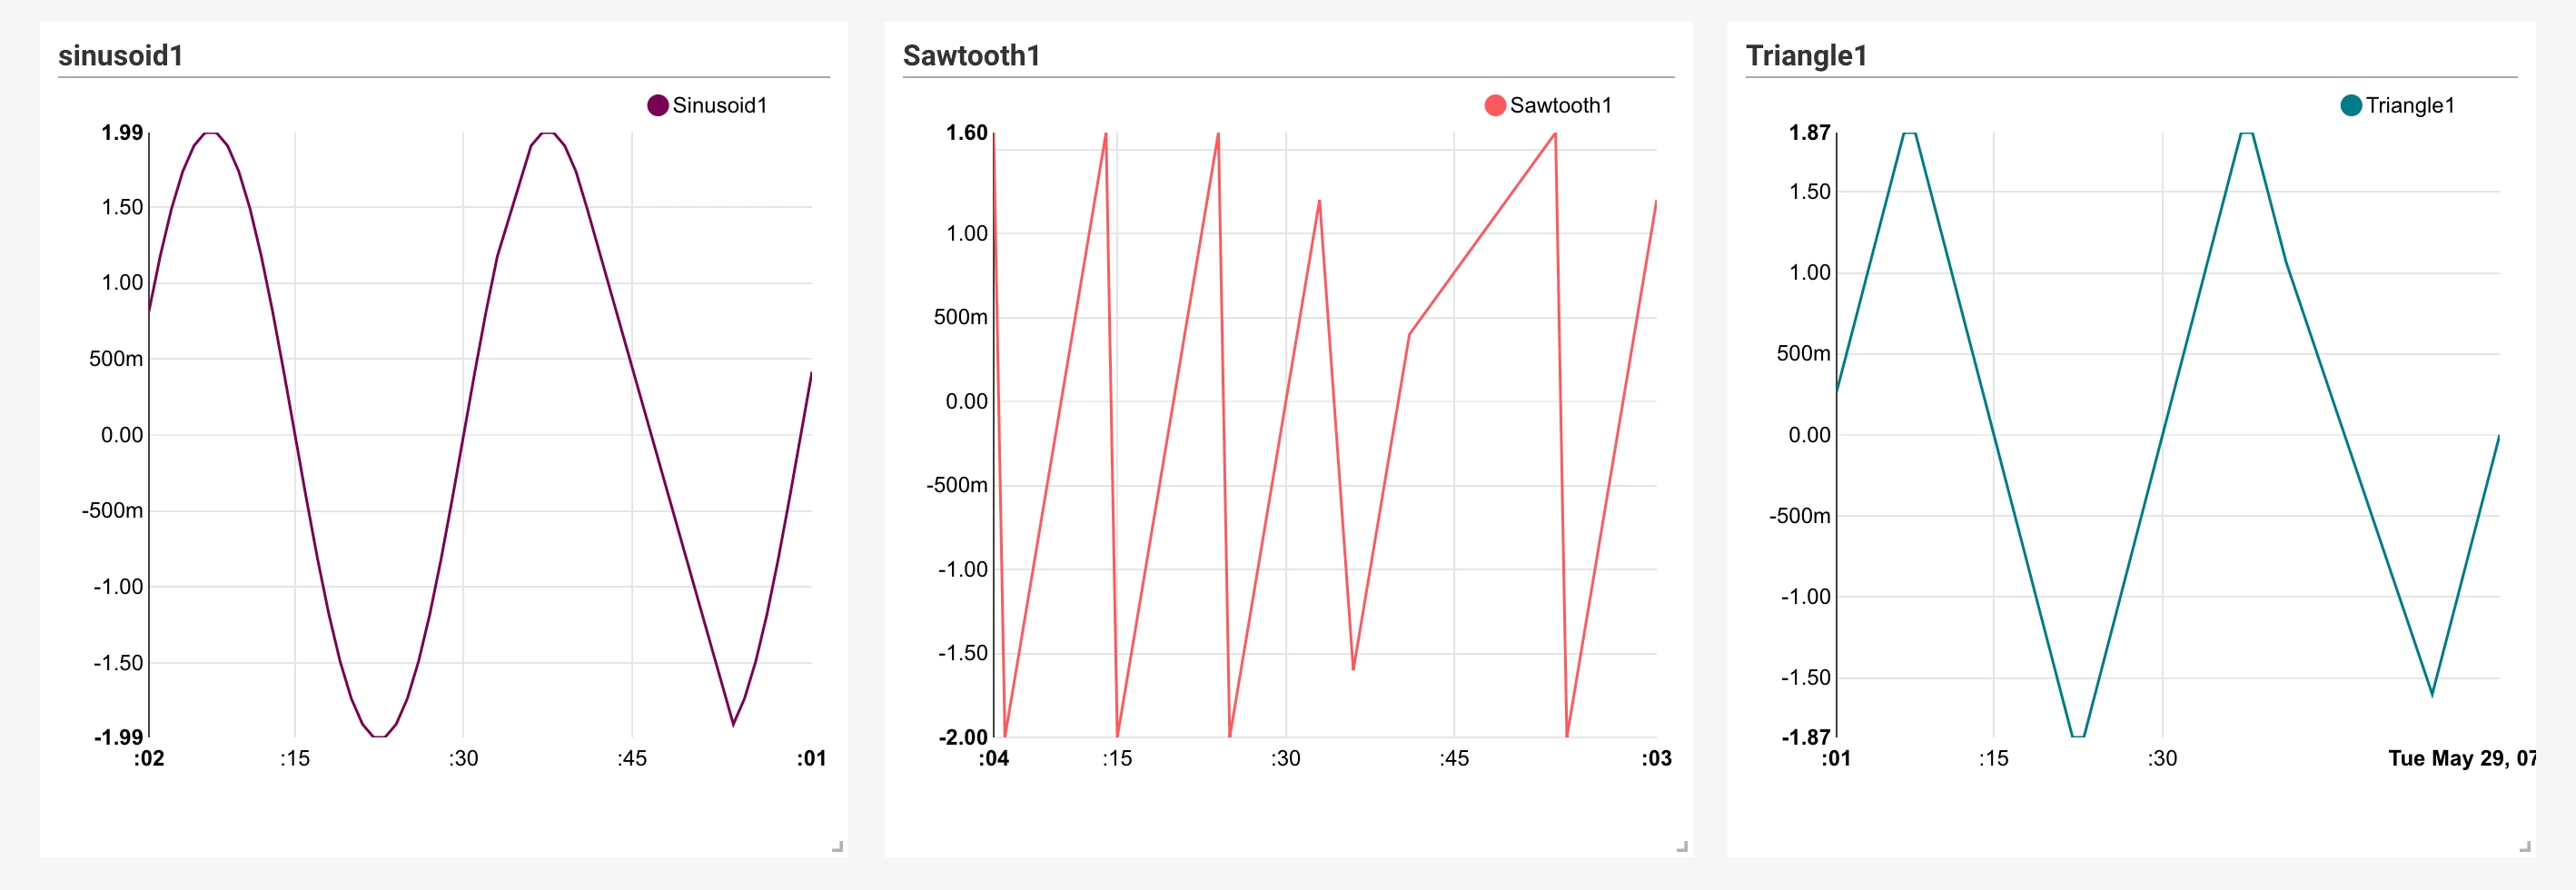
Hopefully you find the article helpful. You could improve accuracy by also copying the data into HDFS / HIve , so you could do some BI kind of reporting and do advance analytics on the data using spark. YOu could also load this data in batches to druid so it can correct any holes or errors from the real time ingest.

