


NiFi ConvertCSVToAvro Processor for clickstream data quality
Background
When we use NiFi flow to load Adobe ClickStream tsv file into hive, we found around 3% rows are in wrong format or missed.
Source Data Quality
$ awk -F "\t" '{print NF}' 01-weblive_20161014-150000.tsv | sort | uniq -c | sort
   1 154
   1 159
   1 162
   1 164
   1 167
   1 198
   1 201
   1 467
   2 446
   2 449
   2 569
   6 13
  10 3
  13 146
  13 185
  15 151
  16 54
  18 433
  21 432
  22 238
  23 102
  26 2
  34 138
 179 1
319412 670
After clean the tsv
$ awk -F "\t" 'NF == 670' 01-weblive_20161014-150000.tsv >> cleaned.tsv
$ awk -F "\t" '{print NF}' cleaned.tsv | sort | uniq -c | sort
319412 670
Still missed a few percent rows.
Root Cause and Solution
We are using ConvertCSVToAvro and ConvertAvroToORC.
The clickstrem tsv files have " in them and the ConvertCSVtoAvro processor uses " as the value for the "CSV quote Character" processor configuration property by default. As a result many tabbed fields end up in the same record. We can get good output by changing this configuration property to another character that is not used in input files anywhere. We used ¥
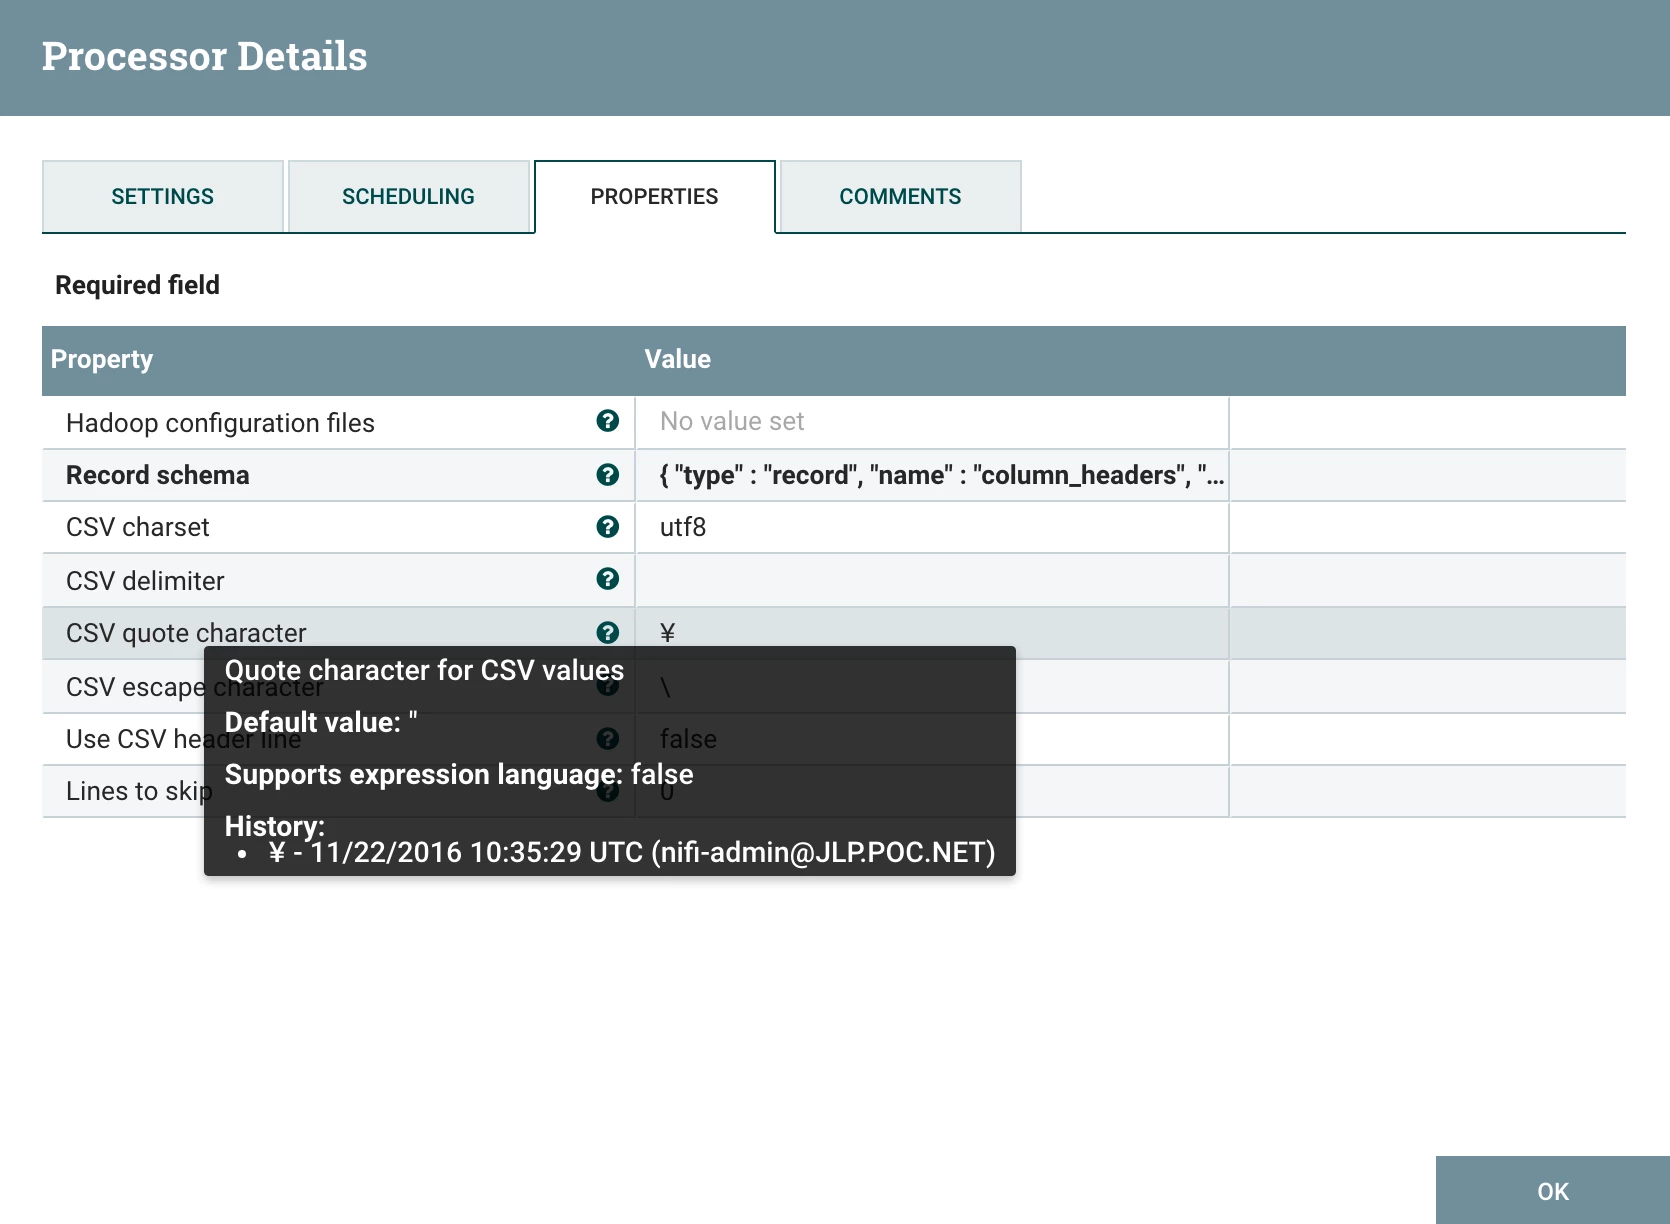
So when use CSV related processor, double check the contents don't have the quote character.

