

Using Apache NiFi to read and write JSONB data to PostgreSQL
Greetings dear Apache NiFi community. I've recently had the opportunity to use NiFi to read and write JSON data to PostgresSQL using its native JSONB data type. While researching how to do this, I found very limited information, mainly just one helpful StackOverflow question and reply by
My use case was fairly simple: I had JSON files that I wanted to store as-is and be able to retrieve them later in the exact same form. This presented three main challenges:
- JSONB is a column, meaning that when writing to it, you need to wrap up your JSON under a new field with a name matching the column.
- PutDatabaseRecord will not work if the data under the new wrapper field is a valid JSON, since it will try to parse it as record values. Therefore, you need to escape your JSON data before writing to the DB.
- When reading the data back, you need to restore the escaped JSONs back to their original form and remove the wrapper field from step 1.
Writing to JSONB column
In my case, the PostgreSQL table had two columns:
- data of type JSONB
- id of type UUID (generated from the contents of data)
The table DDL is as such:
CREATE TABLE IF NOT EXISTS <schema>.<table> (
data JSONB NOT NULL,
id UUID GENERATED ALWAYS AS ((data->>'id')::uuid) STORED,
PRIMARY KEY (id)
)
To wrap my JSONs in the 'data' field and escape them, I used a single ReplaceText processor configured as such:
| Replacement Strategy | Regex Replace |
| Search Value | (?s)(^.*$) |
| Replacement Value | {"data": "${'$1':escapeJson():replace('\\', '\\\\')}"} |
| Character Set | UTF-8 |
| Maximum Buffer Size | 1 MB |
| Evaluation Mode | Entire text |
| Line-by-Line Evaluation Mode | All |
Credit to Mark Payne (
No special configuration is needed in the PutDatabaseRecord processor. This is the overall flow:
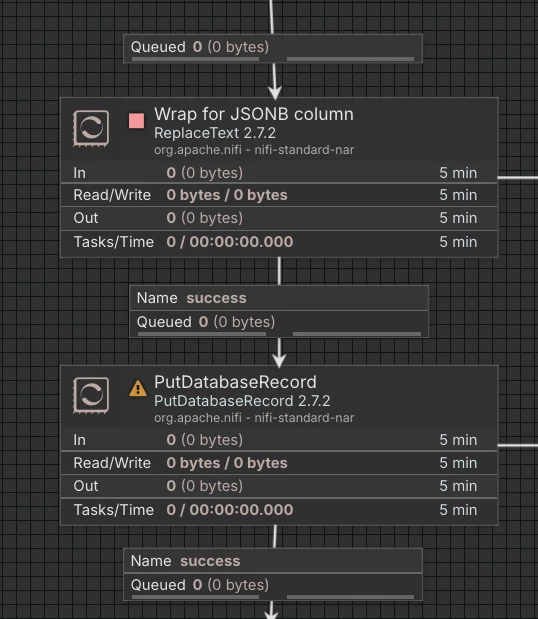
Note that although it appears you insert escaped JSONs to your DB, they are actually stored correctly and can be queried using standard JSONB operators (->, ->>, etc.)
Reading the Data back
To read the data back, I use ExecuteSQLRecord to fetch rows (making sure to specify Array Output in the JSON RecordWriter), followed by another ReplaceText processor to edit the results back to their correct shape.
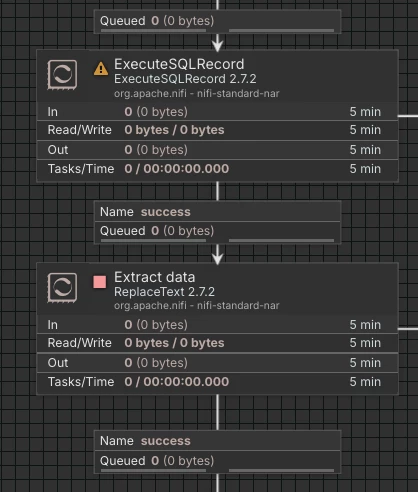
I define a basic SQL query to fetch just the data column:
SELECT data FROM <schema>.<table>The resulting FlowFile content might look something like:
[
  {
    "data": "{\"id\": \"488b5b63-6ccf-4816-9a38-38c3befd248f\", \"myKey\": \"myValue\", \"keyTwo\": \"bababa\"}"
  },
  {
    "data": "{\"id\": \"2fec9cad-5246-4d92-aa41-9a57cfc4e8ab\", \"myKey\": \"myValue23\", \"keyTwo\": \"21312\"}"
  },
  {
    "data": "{\"id\": \"6efbac98-3a10-422d-a2a2-ac6d79ffef6b\", \"myKey\": \"myValue23\", \"keyTwo\": {\"nested\": [\"abc\", \"def\"]}}"
  }
]
As you can see, each row gets read as a flat JSON where the key is 'data' like the column name, and the value is a stringified/escaped version of the original content.
To fix it now, I use this config in the following replace text:
| Replacement Strategy | Regex Replace |
| Search Value | "data"\s*:\s*"\{((?:\\.|[^"\\])*)\}" |
| Replacement Value | ${'$1':unescapeJson()} |
| Character Set | UTF-8 |
| Maximum Buffer Size | 1 MB |
| Evaluation Mode | Line-By-Line |
| Line-by-Line Evaluation Mode | All |
Note that I use Line-By-Line mode this time, since ExecuteSQLRecord seems to fetch rows prettified with newlines separating them (Even if Pretty Print is set to false in the RecordWriter!). Because it scans line-by-line, it ignores the braces/brackets at the top and bottom of the response and in-between the different rows, and you can instead focus on just the content of the rows, which looks like:
"data" : "{\"id\": \"488b5b63-6ccf-4816-9a38-38c3befd248f\", \"myKey\": \"myValue\", \"keyTwo\": \"bababa\"}"Thus, we match everything within the value of data's braces "data" : "{ <this part> }" and once again use ReplaceText's special expression syntax '$1' to refer to our escaped version of the original JSON content and then run :unescapeJson() on it to restore it back to its valid form.
The output will look like
[ {
  "id" : "488b5b63-6ccf-4816-9a38-38c3befd248f",
  "myKey" : "myValue",
  "keyTwo" : "bababa"
}, {
  "id" : "2fec9cad-5246-4d92-aa41-9a57cfc4e8ab",
  "myKey" : "myValue23",
  "keyTwo" : "21312"
}, {
  "id" : "6efbac98-3a10-422d-a2a2-ac6d79ffef6b",
  "myKey" : "myValue23",
  "keyTwo" : {
    "nested" : [ "abc", "def" ]
  }
} ]
And now you have valid JSONs to work with again for the rest of your flows.
DISCLAIMER: An external user contributed to this article. Cloudera may not verify that the steps may be applicable for all use cases and may be very specific to a particular distribution. Please follow with caution and at your own risk. If needed, raise a support case to get confirmation.

