How can I use a Groovy ExecuteScript to split a large PDF into smaller, 2-page PDFs?
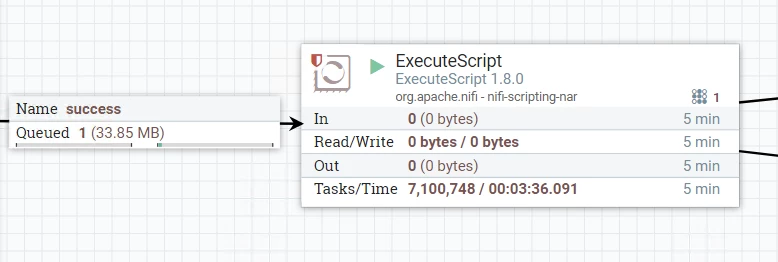
My goal is to take in a large PDF (34MB), split it into smaller, 2-page PDFs, and send each of the new 2-page PDFs out as a new flowfile for further processing. I've provided the code I have so far below, most of which came from the ExecuteScript Cookbook series. It looks as though the upstream flowfile is not even entering the processor (photo attached). Any help would be greatly appreciated!
import org.apache.pdfbox.pdmodel.PDDocument
import org.apache.pdfbox.multipdf.Splitter
import org.apache.commons.StandardCharsets

flowFile = session.get()
if(!flowFile) return

def pdf = ""
session.read(flowFile, {inputStream ->
    pdf = IOUtils.toString(inputStream, StandardCharsets.UTF_8)} as InputStreamCallback)

def document = PDDocument.load(pdf)

def splitter = new Splitter()
splitter.setSplitAtPage(2)

def forms = splitter.split(document)

//Iterator<PDDocument> iterator = forms.listIterator();

for(form in forms)
{
    form.close()
    newFlowFile = session.create()
    newFlowFile = session.write(newFlowFile, {outputStream ->
        outputStream.write(form.getBytes(StandardCharsets.UTF_8)) as OutputStreamCallback
        })
    session.transfer(newFlowFile, REL_SUCCESS)
}