Solved
How is the memory allocated in CDP Machine Learning session for Spark?
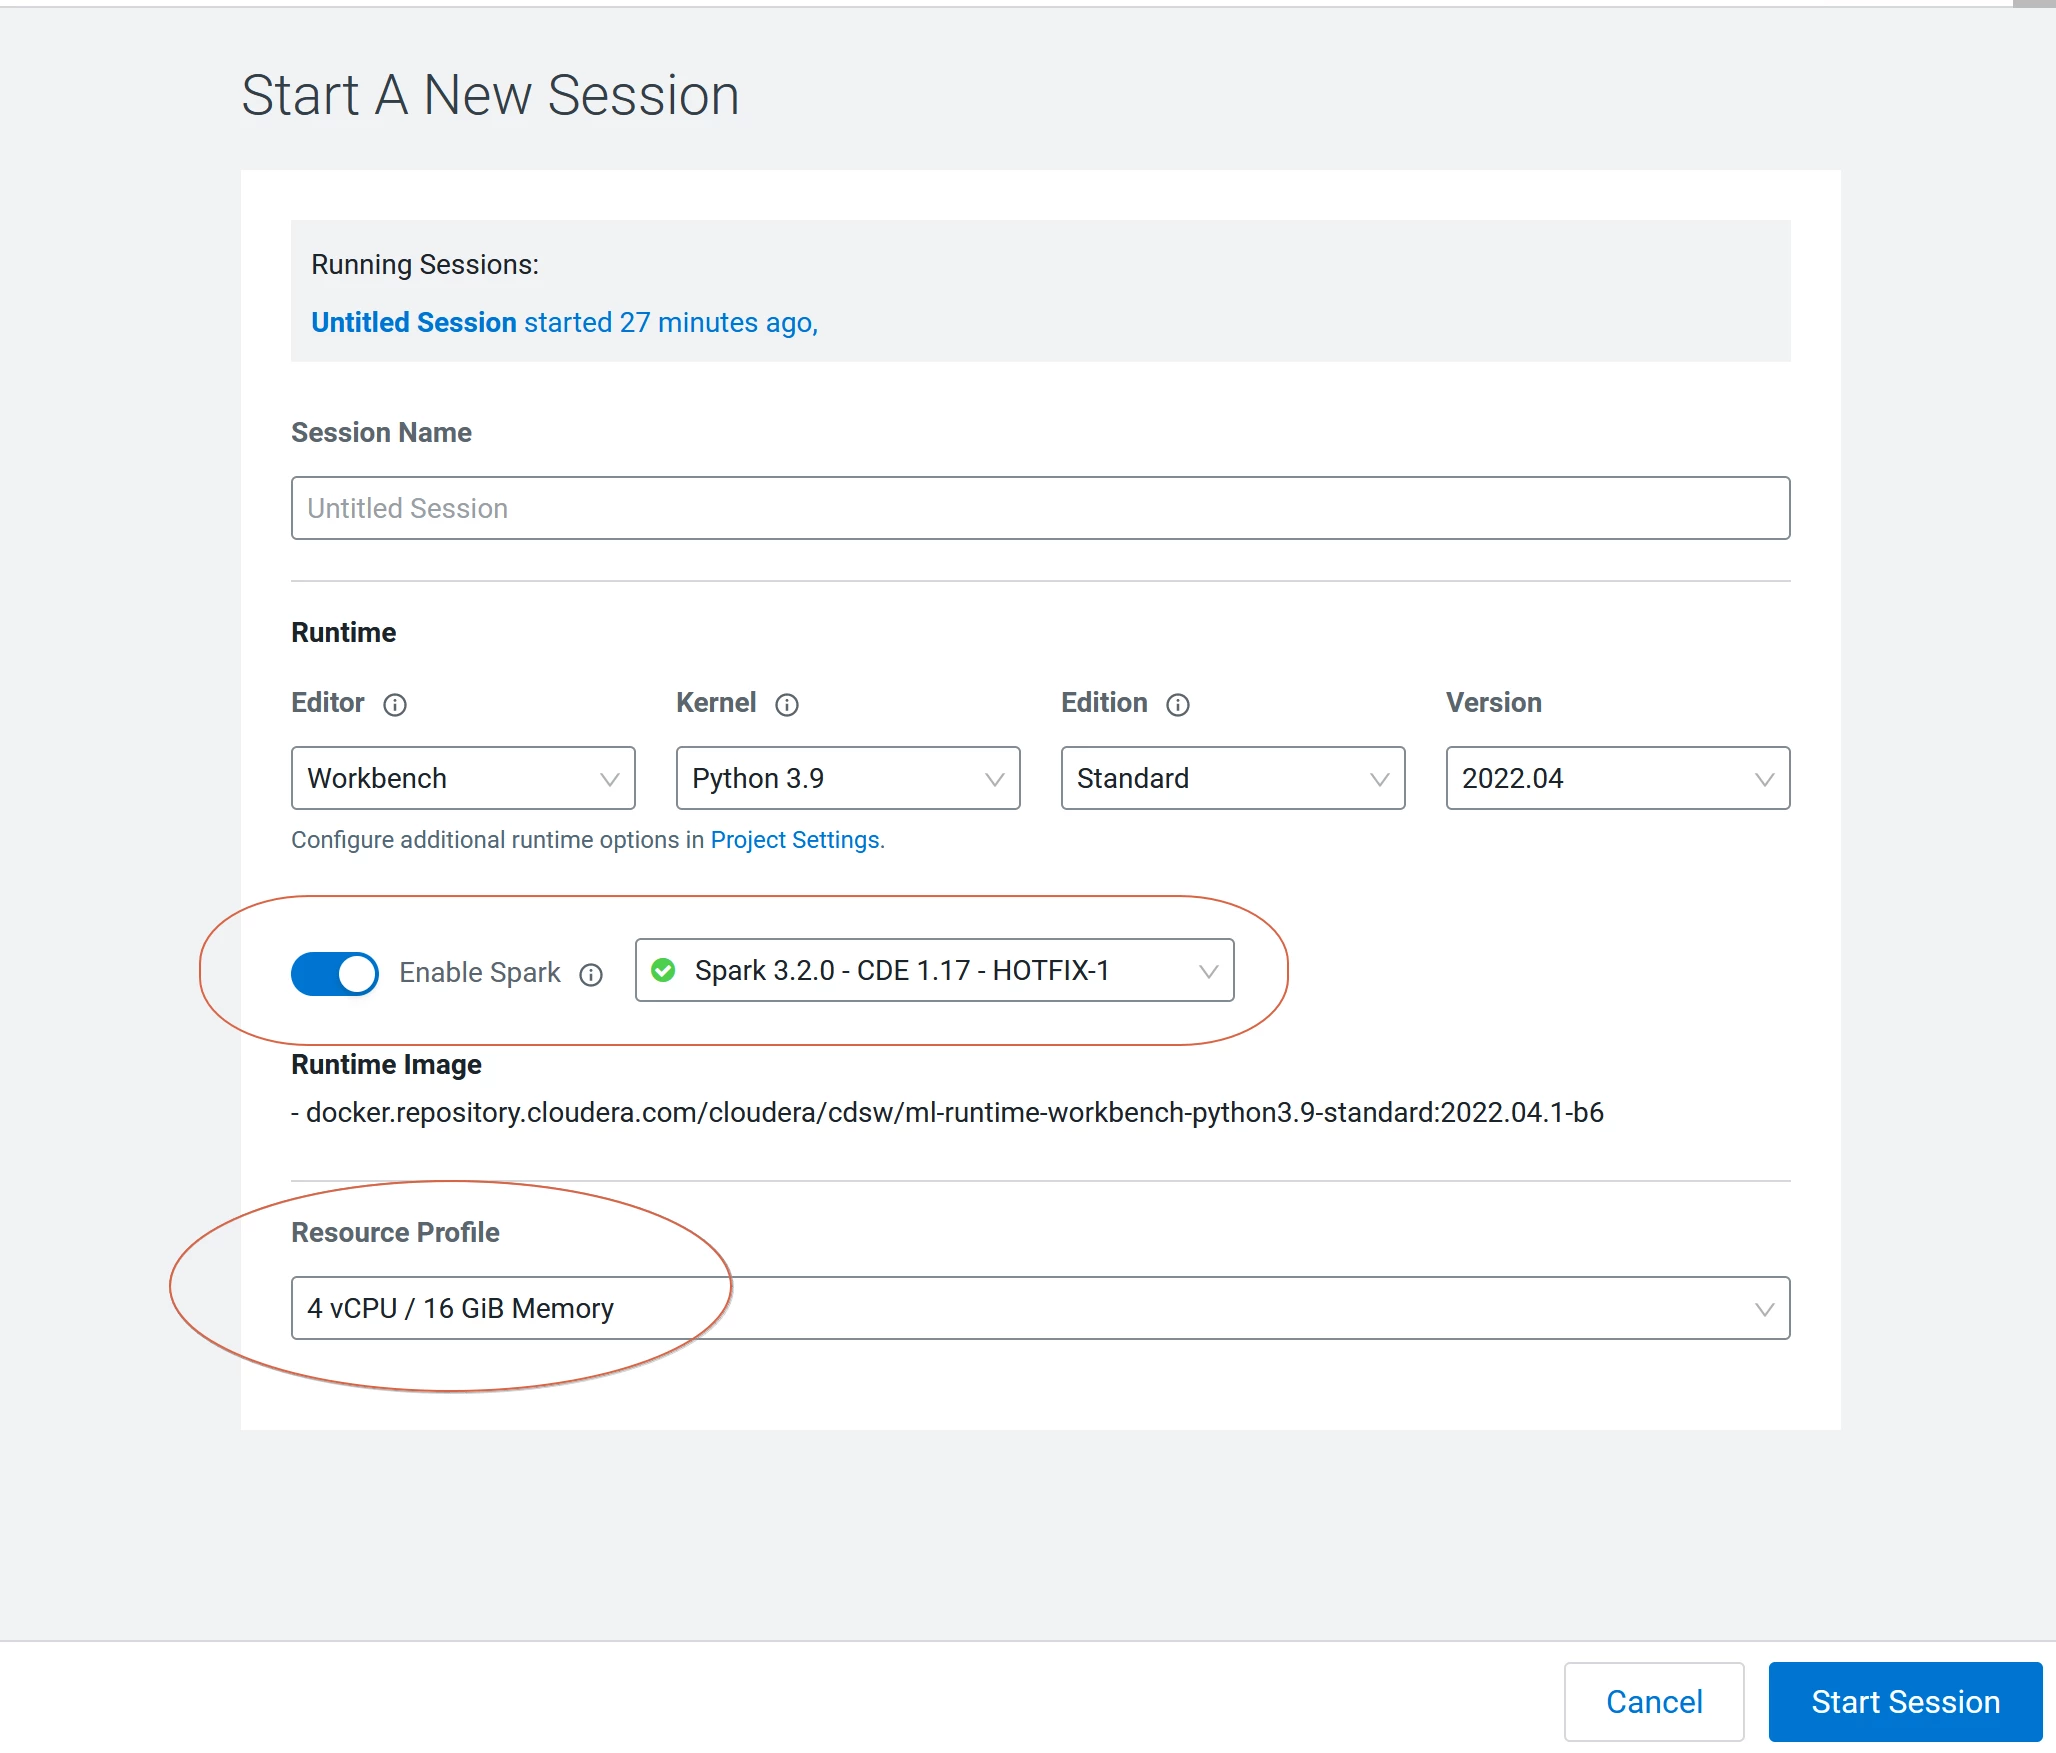
In CDP Public Cloud Machine Learning, we can create a new session with reserved resource, for example 4vCPU and 16 GiB Memory.
We can also create spark session inside the machine learning workbench with some memory configuration. For example:
spark = (SparkSession.builder.appName(appName).config("spark.driver.memory", "16G").config("spark.executor.instances", "10").config("spark.executor.cores", "4").config("spark.executor.memory", "20G").getOrCreate())
My question is, how will the memory be allocated to Spark session now? Is the reserved resource (4vCPU and 16 GiB Memory) in machine learning session the maximal limitation for total spark memory usage? How many work nodes and executors can I configure for the spark session?