

HadoopHero
Silver ⭐️⭐️⭐️
November 7, 2023
Question

Possibility Split Parquet file

Hello everyone,

my team using TEZ, in particular Hive, has noticed that during an insert with a very simple select a single parquet file of 1.5 gb per partition is generated in the output table.

To try to remedy the problem, a number of settings were used at the session level but had no effect.
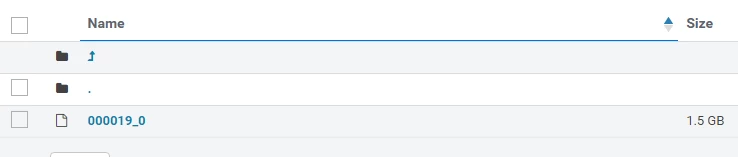
HadoopHero_0-1699388299635.png

Below are the sets used at the session level:

SET hive.execution.engine=tez;
SET hive.exec.dynamic.partition=true;
SET hive.exec.dynamic.partition.mode=nonstrict;
SET hive.optimise.sort.dynamic.partition.threshold=0;
--SET tez.grouping.max-size=268435456;
--SET hive.exec.reducers.bytes.per.reducer=536870912;
--SET tez.grouping.split-count=18;
SET hive.vectorized.execution.reduce.enabled = true;
SET hive.vectorized.execution.reduce.groupby.enabled = true;
--SET hive.tez.auto.reducer.parallelism=false;
--SET mapred.reduce.tasks=12;
--SET hive.tez.partition.size=104857600;
--SET hive.tez.partition.num=10;
SET hive.parquet.output.block.size=104857600;

I would like to ask if there is a way to always have parquet type files but broken up into smaller files as shown in the image below
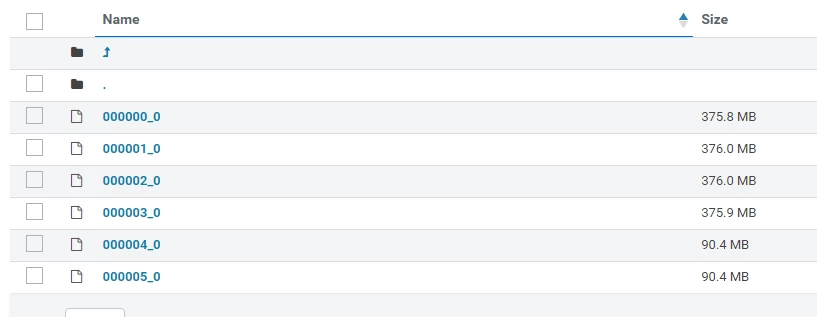
HadoopHero_1-1699388442024.png

We cannot understand what the cause might be.
Files structured in this way do not guarantee sufficient parallelism for other jobs present (such as sqoop)


8 replies

mszurap
Platinum ⭐️
Platinum ⭐️
November 8, 2023

Hi @HadoopHero ,

For Hive, if there is a single reduce task to write the output data it will not break it up the output file into smaller files, that's expected and cannot be configured to behave in a different way.

With DISTRIBUTE BY you should be able to achieve to have multiple reducers (if you have a column by which you can "split" your data reasonably into smaller subsets), see

https://cwiki.apache.org/confluence/display/Hive/LanguageManual+SortBy

Best regards

 Miklos

Translate
HadoopHero
Silver ⭐️⭐️⭐️
November 9, 2023

Hello Miklos,

unfortunately, what you suggested had no effect. We continue to have the same problem, with creating a single parquet file.

Translate
ggangadharan
Gold ⭐️
Gold ⭐️
November 9, 2023

Hi @HadoopHero ,

If the query involves dynamic partitioning, one potential issue is that 'hive.optimize.sort.dynamic.partition.threshold' may limit the number of open record writers to just one per partition value, resulting in the creation of only one file. To investigate this, could you attempt disabling 'hive.optimize.sort.dynamic.partition.threshold' entirely?


SET hive.optimize.sort.dynamic.partition.threshold=-1;


Note : The problem statement contains a typo in the config name

Translate
DianaTorres
Community Manager
Community Manager
November 13, 2023

@HadoopHero Has the reply helped resolve your issue? If so, please mark the appropriate reply as the solution, as it will make it easier for others to find the answer in the future.  Thanks.

Translate
Regards, Diana Torres, Senior Community Moderator
HadoopHero
Silver ⭐️⭐️⭐️
November 13, 2023

@DianaTorres I'm sorry but unfortunately the problem still persists even after trying the suggestions in the previous posts

Translate
DianaTorres
Community Manager
Community Manager
November 13, 2023

@Shmoo @cravani Do you have any insights here? Thanks!

Translate
Regards, Diana Torres, Senior Community Moderator
cravani
Gold ⭐️
Gold ⭐️
November 21, 2023

@HadoopHero Answer would vary based on query that you are running, assuming you have simple "Insert select */cols from Table" it is likely mapper only job and you may want to try tuning below.

set tez.grouping.min-size=134217728; -- 128 MB min split
set tez.grouping.max-size=1073741824; -- 1 GB max split

Try setting min-size and max-size to same value. I would not go below 128M.

Translate
DianaTorres
Community Manager
Community Manager
November 24, 2023

@HadoopHero Has the reply helped resolve your issue? Thanks.

Translate
Regards, Diana Torres, Senior Community Moderator