@Faizan123
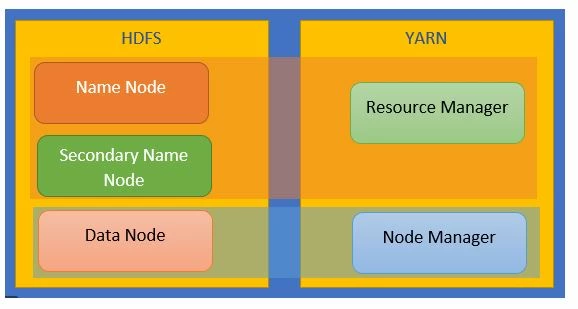
Namenode [Master] and Datanode [Slave] are part of HDFS, which is the storage layer, and ResourceManager[Master] and NodeManager [Slave] are part of YARN, which is a Resource Negotiator. So HDFS and YARN work together usually but are quite independent at design and architecture but their slave processes run together on the compute nodes i.e DataNode and a NodeManager process.
This a high-level architecture of RM and NM the 2 master processes and the latter being the brain of Hadoop
Below is a standard layout of a Hadoop cluster though we could have easily added a second RM for HA
On the 12 compute nodes the NM and DN and co-located for the localized processing
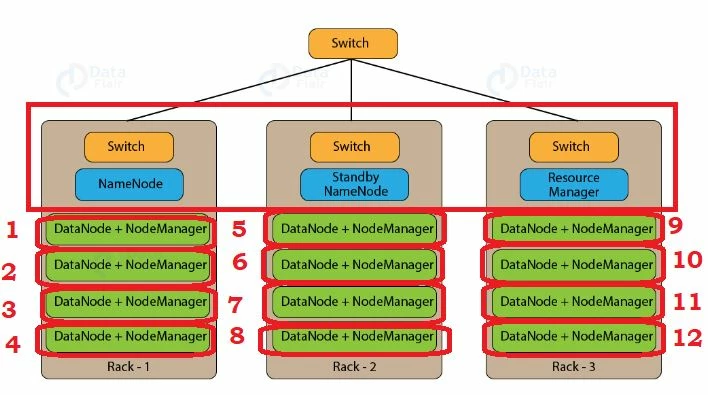
It's illogical to separate the DN and NM on different nodes. The NodeManager is YARN’s per-node agent and takes care of the individual compute nodes in a Hadoop cluster. Updating the ResourceManager (RM) with the status of running jobs on the DN, overseeing containers’ life-cycle management; monitoring resource usage (memory, CPU) of individual containers, tracking node-health, log’s management, and auxiliary services which may be exploited by different YARN applications.
DataNodes store data in a Hadoop cluster and is the name of the daemon that manages the data. File data is replicated on multiple DataNodes for reliability and so that localized computation can be executed near the data. That's the reason DN and NM are co-located on the same VM/host.
It could be very interesting to see a screenshot of the roles co-located with your data nodes.
Hope that gives you a clearer picture




