
Ingesting a Big CSV file into Kafka using a multi-stages SplitText NiFi Processor
Introduction
The purpose of this article is to use Apache NiFi to ingest a huge csv file (few million rows) into a Kafka topic.
The tricky point when dealing with big file (millions of rows) is that processing the file by NiFi on row-level will generate flow files for every row, this can produce java memory error. As a work around, we need to limit the generated number of rows by splitting the rows on multiple stages. In this article, the file was around 7 million rows, and 6 dividing stages (100K, 10K, 1K, 100, 10 then 1) were used to limit number of generated flow files.
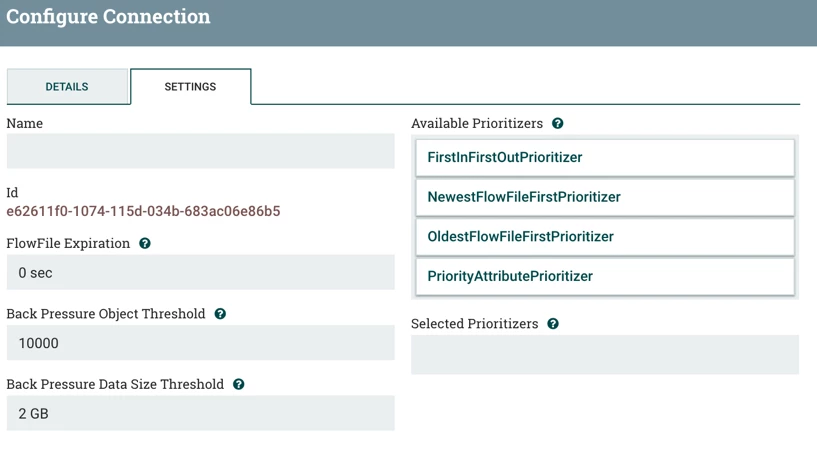
The other trick is to increase the “Splits” queue’s “Back Pressure Data Size Threshold” to an adequate size for handling file size, by default it’s 1GB. In this article, 2GB is used.
Assumptions & Design
A standalone NiFi and Kafka instance is to be used for this exercise.
The following NiFi flow will be used to split the workload of the multi-million row csv file to be ingested by dividing the ingestion into multi-stages.
Figure 1: the NiFi flow
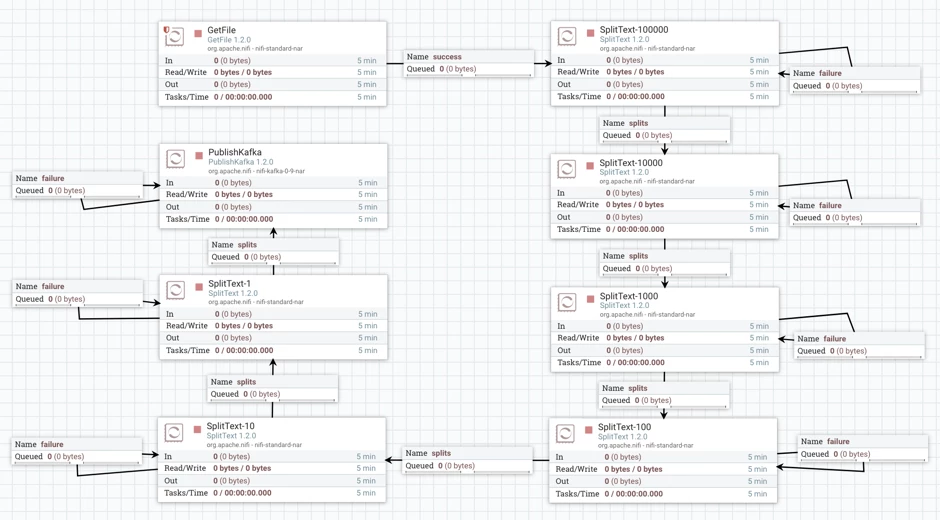
Figure 2: Properties for “SplitText-100000”
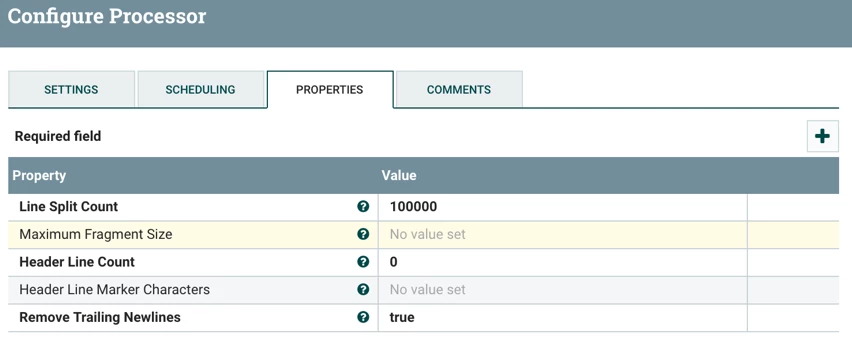
Figure 3: Properties for “SplitText-10000”
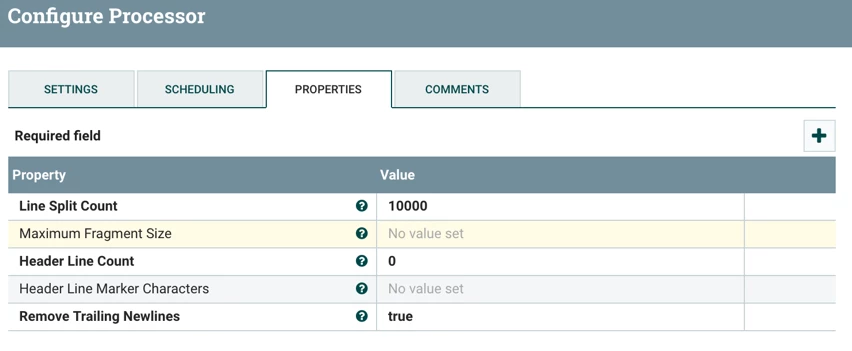
Figure 4: Properties for “SplitText-1000”
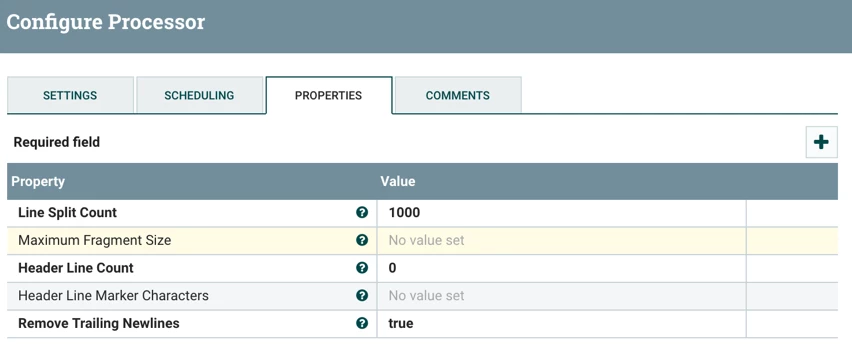
Figure 5: Properties for “SplitText-100”
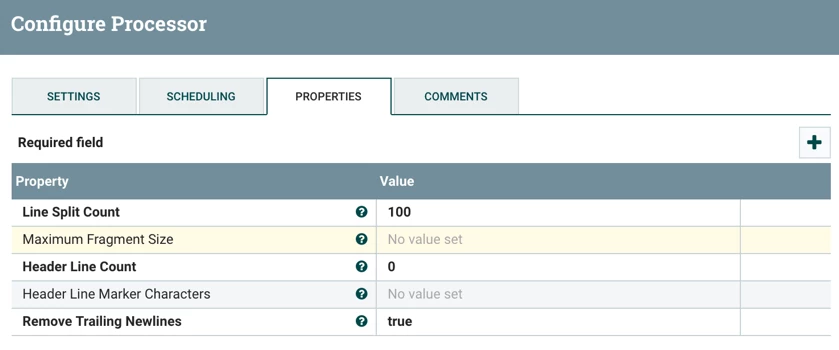
Figure 6: Properties for “SplitText-10”
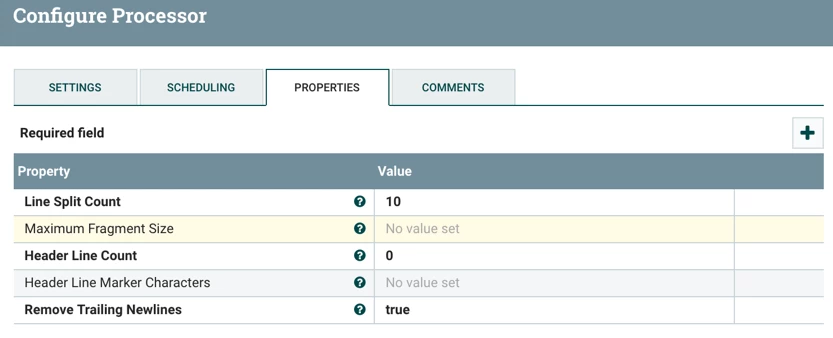
Figure 7: Properties for “SplitText-1”
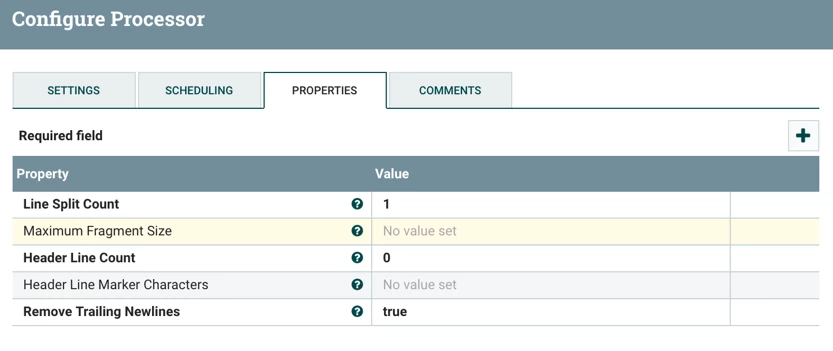
Figure 8: Properties for the six “splits” queues
Results
The csv rows were ingested properly to the Kafka topic. The only drawback for this flow is that it took almost 30 minutes for ingesting a csv of around 7 million rows. This can be enhanced by using multi NiFi instances and a clustered Kafka, which should be tested in the future.
Future Work
I’ll try doing the same exercise using bigger file size using bigger NiFi and Kafka clusters with higher hardware specs to validate the same conclusion.
References:
https://community.hortonworks.com/questions/122858/nifi-splittext-big-file.html

