adhishankarit
Gold ⭐️
December 27, 2020
Solved

Nifi Processors status merge attributes into single flowfile content

Hi All,


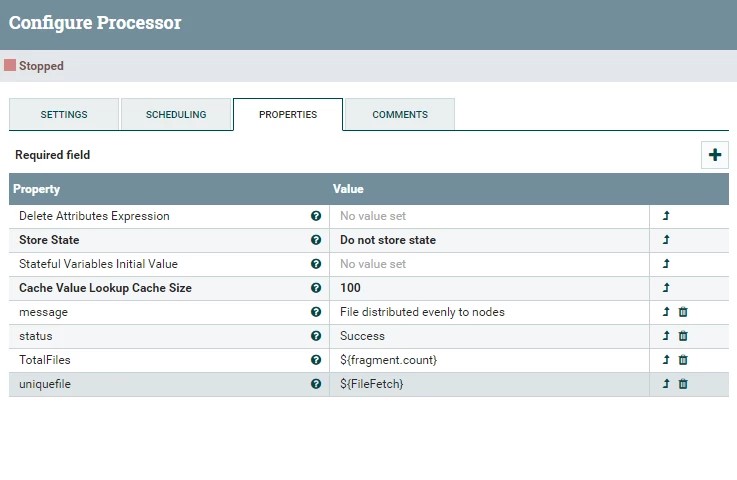
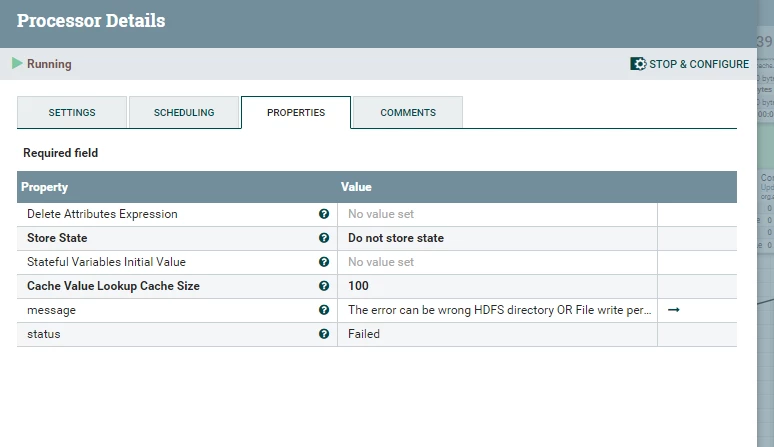
I am building Nifi flow which fetch the filename.zip from shared server and unpack the .zip file then distributes the files across nifi cluster and finally put the files in HDFS. By doing Nifi status.PNGupdateattribute_1.PNGupdateattribute_2.PNGthis process , i am collecting success or failure status of each processors using custom message in
Updateattribute processor . Refer the sample attached screen-print for updateattribute processor .


Next i am planning to update overall status(success or error) of .zip file along with each file processed status ,like combining all information into one file and push the file to shared server to know about the status. I tried to use Mergecontent processor but i am unable to update the .zip file status and also noticed that if there is a delay in processing  

How to build the flowfile like below 


Filename.zip:staus:error_message
Filename1.status:sucess_message

Filename2:status:success_message

Filename3:status:error_message


Going forward i may also update the status message in JSON 

@Nifi  @NifiDev 

MattWho
MattWhoAnswer
Titanium ⭐️⭐️⭐️
December 28, 2020

@adhishankarit 


You dataflow screenshot does not reflect the entire dataflow you are then trying to describe making this use case hard to follow.

1. Your flow starts with a single zip file?
2. You unzip that file to produce numerous output FlowFiles?
3. You use load balanced connections to distribute all the produced FlowFiles across all nodes in your cluster?
4. Then you modify content of FlowFile using convertAttribitesToJson processor (Destination=flowfile-content)?  Looks like you route the "success" relationship twice from this processor which means you have cloned your FlowFiles.  Why?
5. One of these connection looks like it uses a Load Balance connection (how is it configured?) to feed a MergeContent.  MergeContent can not merge across multiple nodes (can only merge FlowFiles on same node. How is MergeContent configured?  Your desire output does not look like Json, but you are using AttributesToJson processor?
6. Where do the "failure" FlowFiles get introduced in to this dataflow?


When you unpack your original FlowFile each produced FlowFile will have new attributes set on it to include segment.original.filename, fragment.identifier, fragment.count, and fragment.index.  These attributes can be used with the "defragment" merge strategy in MergeContent.  So I would avoid cloning FlowFiles post unpack.  Process each FlowFile in-line. When you encounter a "failure", set an attribute on these FlowFiles only that states a failure occurred (successfully processed FlowFiles should not have this unique attribute). Then use MergeContent and set keep all Unique Attributes.  This will allow the unique attribute if exists on any one FlowFile to show up on the output merged FlowFile will not work if same attribute exists on multiple FlowFiles with different values).  Now after merge you can modify the content again using ReplaceText processor configured with Append to add the first line with overall status of this file from that unique attribute you preserved through the merge.

Also not following statement:
"also noticed that if there is a delay in processing "

Hope this helps,
Matt

6 replies

MattWho
Titanium ⭐️⭐️⭐️
MattWhoAnswer
Titanium ⭐️⭐️⭐️
December 28, 2020

@adhishankarit 


You dataflow screenshot does not reflect the entire dataflow you are then trying to describe making this use case hard to follow.

1. Your flow starts with a single zip file?
2. You unzip that file to produce numerous output FlowFiles?
3. You use load balanced connections to distribute all the produced FlowFiles across all nodes in your cluster?
4. Then you modify content of FlowFile using convertAttribitesToJson processor (Destination=flowfile-content)?  Looks like you route the "success" relationship twice from this processor which means you have cloned your FlowFiles.  Why?
5. One of these connection looks like it uses a Load Balance connection (how is it configured?) to feed a MergeContent.  MergeContent can not merge across multiple nodes (can only merge FlowFiles on same node. How is MergeContent configured?  Your desire output does not look like Json, but you are using AttributesToJson processor?
6. Where do the "failure" FlowFiles get introduced in to this dataflow?


When you unpack your original FlowFile each produced FlowFile will have new attributes set on it to include segment.original.filename, fragment.identifier, fragment.count, and fragment.index.  These attributes can be used with the "defragment" merge strategy in MergeContent.  So I would avoid cloning FlowFiles post unpack.  Process each FlowFile in-line. When you encounter a "failure", set an attribute on these FlowFiles only that states a failure occurred (successfully processed FlowFiles should not have this unique attribute). Then use MergeContent and set keep all Unique Attributes.  This will allow the unique attribute if exists on any one FlowFile to show up on the output merged FlowFile will not work if same attribute exists on multiple FlowFiles with different values).  Now after merge you can modify the content again using ReplaceText processor configured with Append to add the first line with overall status of this file from that unique attribute you preserved through the merge.

Also not following statement:
"also noticed that if there is a delay in processing "

Hope this helps,
Matt

Translate
adhishankarit
Gold ⭐️
January 4, 2021
Hi ,
@MattWho
Thanks a lot for clarifying and provide solution for Merging contents . I have implemented as per your guidelines and the merge content working fine But i am unable to update overall status of file if it is error and message as well. Please find my status flow in detail. 
 
1.Your flow starts with a single zip file? --- I get meta file which contains .zip file to be fetched . for exmaple whosale.meta file which contain .zip file having 3 or 4 csv files . 
2. You unzip that file to produce numerous output FlowFiles? --- Yes , I unzip the file .
3. You use load balanced connections to distribute all the produced FlowFiles across all nodes in your cluster? --- Yes , i do enable round robin load balancing for the flow files which was unzip in step 2 and push the flowfiles into HDFS .
4. Then you modify content of FlowFile using convertAttribitesToJson processor (Destination=flowfile-content)?  Looks like you route the "success" relationship twice from this processor which means you have cloned your FlowFiles.  Why?  --- Initially i was trying convert attributes into JSON flowfile. I have to capature success and failure status of the processor .So i have avoided not clone the success relationship twice.
 
Ingestionflow.PNG
 
 
6. Where do the "failure" FlowFiles get introduced in to this dataflow? --- If i encounter "failure" in process of pushing files to HDFS like permission denied or folder not available . Then i will add attribute with some custom messages and send to merge content . And i have also dirceting success status with some custom message of the final process success status in attribute to replacetext followed with Mergecontent .
 
Status flow 
 
flowstatusconstruct.PNG
 
HDFSError attribute : 
updateattribute_1.PNG
 
 
HDFS Successattribute :
updateattribute_2.PNG
 
After merge content i do use Replacetext processor as suggested to add overall status of the file but somehow the status (error) and message is not captured .
 
ReplaceTextProc to construct over all status :
 
MergeandReplace.PNGreplacetextattributes.PNG
 
 
The final file will contain like below 
 
Ingest_flow.zip : Success : 
test1.csv : Success : File artikelgroep_info.csv pused to PreRAW Zone
test2.csv : Success : File demo.csv pused to PreRAW Zone
test3.csv : Success : File work11.csv pused to PreRAW Zone
 
i could not populate over all message AND if any file error then i could not capture status " Failed" and with error in overall status of the .zip file .Could you please help on this 
 
 
Thanks
Translate
adhishankarit
Gold ⭐️
February 11, 2021

@MattWho 


In continuation of above logic and i implemented and it is working fine . I have three nodes nifi cluster where a,b,c .Here a node is primary node always . If a goes out of space , we will unzip the file from another node and distributes to b,c nodes and we push the file to HDFS folder and we capture success and failure message( in Updateattribute processor)  as mentioned in the posts above . After that in mergerecord process , the queue is waiting for sometime and merging happens after 10mins around . I have a dependency of the merging processor as i have to share the status of flowfile to another API which is requesting for it. How we can speed up the MergeRecord processor here . If all three nodes have good amount of memory and the flowfiles pushed to HDFS and status updates (through UpdateProcessorattribute) and merging happens very quickly as expected in single node. But we have nodes(b,c) and 'a' primary node is out due to space issue in device .The processor unpack the .zip file then distribute to nodes tp put into HDFS .As we capture each success/failure status of PutHDFS (using updateattribute processor)  and  mergerecord is taking sometime to merge the status . Is this because of other two nodes processing it slowly or some other reason for that.


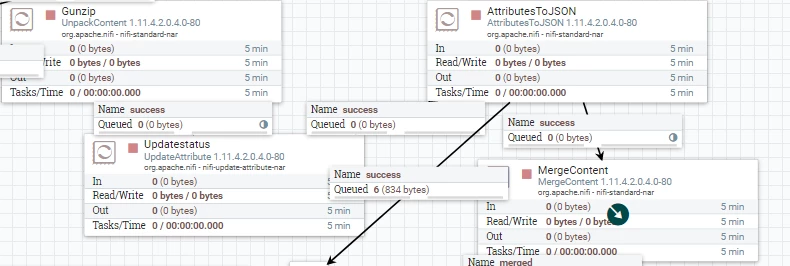
I have attached screenshot of the partial flow .

MergeRecordProcessor.PNGAttributestoJSON.PNGMergeContent_Properties.PNGMergeContent_scheduling_section.PNG

Translate