

Possibility Split Parquet file
Hello everyone,
my team using TEZ, in particular Hive, has noticed that during an insert with a very simple select a single parquet file of 1.5 gb per partition is generated in the output table.
To try to remedy the problem, a number of settings were used at the session level but had no effect.
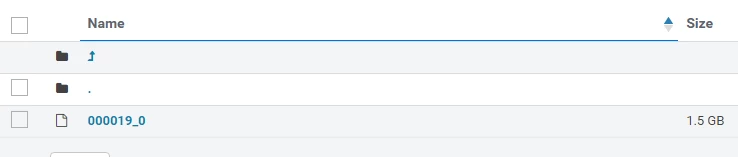
Below are the sets used at the session level:
SET hive.execution.engine=tez;
SET hive.exec.dynamic.partition=true;
SET hive.exec.dynamic.partition.mode=nonstrict;
SET hive.optimise.sort.dynamic.partition.threshold=0;
--SET tez.grouping.max-size=268435456;
--SET hive.exec.reducers.bytes.per.reducer=536870912;
--SET tez.grouping.split-count=18;
SET hive.vectorized.execution.reduce.enabled = true;
SET hive.vectorized.execution.reduce.groupby.enabled = true;
--SET hive.tez.auto.reducer.parallelism=false;
--SET mapred.reduce.tasks=12;
--SET hive.tez.partition.size=104857600;
--SET hive.tez.partition.num=10;
SET hive.parquet.output.block.size=104857600;
I would like to ask if there is a way to always have parquet type files but broken up into smaller files as shown in the image below
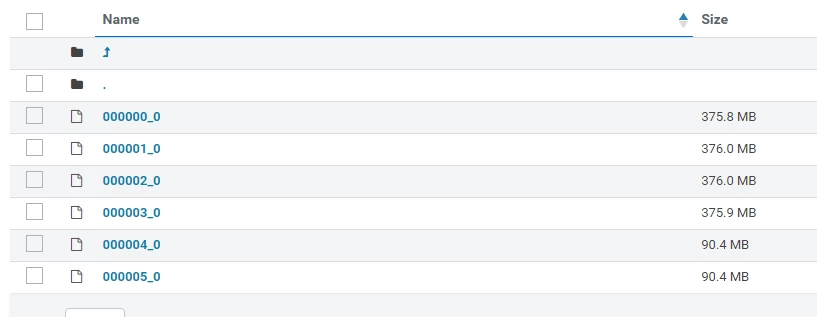
We cannot understand what the cause might be.
Files structured in this way do not guarantee sufficient parallelism for other jobs present (such as sqoop)

