
Our Community is getting an upgrade! To get everything ready for the relaunch, we’ll be placing the site in read-only mode starting September 21st.
We really appreciate your understanding while we get things set up behind the scenes. Catch up on all the exciting details about the move here.
Need help or have questions? Drop us a line at [email protected]

Archives of Support Questions (Read Only)
- Cloudera Community
- Board Archive
- Archives of Support Questions (Read Only)
- Re: How to save all the output of pyspark sql quer...
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
How to save all the output of pyspark sql query into a text file or any file
- Labels:
-
Apache Spark


Created on 08-06-2018 11:32 AM - edited 09-16-2022 06:33 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Hello community,
The output from the pyspark query below produces the following output
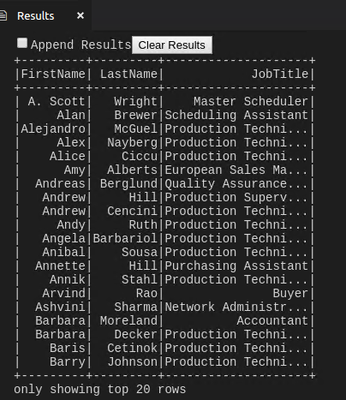
The pyspark query is as follows:
#%%
import findspark
findspark.init('/home/packt/spark-2.1.0-bin-hadoop2.7')
from pyspark.sql import SparkSession
spark = SparkSession.builder.appName('ops').getOrCreate()
df = spark.read.csv('/home/packt/Downloads/Spark_DataFrames/HumanResources_vEmployeeDepartment.csv',inferSchema=True,header=True)
df.createOrReplaceTempView('HumanResources_vEmployeeDepartment')
myresults = spark.sql("""SELECT
  FirstName
 ,LastName
 ,JobTitle
FROM HumanResources_vEmployeeDepartment
ORDER BY FirstName, LastName DESC""")
myresults.show()
Can someone show me how to save the results to a text / csv file ( or any file please)
Thanks Carlton


Created 08-06-2018 01:21 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
You can use this to write whole dataframe to single file:
myresults.coalesce(1).write.csv("/tmp/myresults.csv")HTH
*** If you found this answer addressed your question, please take a moment to login and click the "accept" link on the answer.
Created 08-06-2018 01:21 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
You can use this to write whole dataframe to single file:
myresults.coalesce(1).write.csv("/tmp/myresults.csv")HTH
*** If you found this answer addressed your question, please take a moment to login and click the "accept" link on the answer.
Created 08-06-2018 08:56 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Felix, thank you so much. It worked like a dream
Created 08-06-2018 09:02 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Is there a way to get the results with the header info?

Created 10-02-2018 11:40 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
myresults.coalesce(1).write.format('csv').save("/tmp/myresults.csv", header='true')

Created 06-12-2020 10:24 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Getting permission denied error :Permission denied: user=cldraproc, access=WRITE, inode="/":yarn:supergroup:drwxr-xr-x
df.coalesce(1).write.format('csv').save("/home/cldraproc/shobhit/ccorp.csv", header='true');

Created 06-15-2020 12:07 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
@shubh As this is an older post that has been marked solved in 2018. You would have a better chance of receiving a resolution by starting a new thread. This will also provide the opportunity to provide details specific to your environment that could aid others in providing a more accurate answer to your question.
Regards,
Vidya Sargur,Community Manager
Was your question answered? Make sure to mark the answer as the accepted solution.
If you find a reply useful, say thanks by clicking on the thumbs up button.
Learn more about the Cloudera Community:


