
Our Community is getting an upgrade! To get everything ready for the relaunch, we’ll be placing the site in read-only mode starting September 21st.
We really appreciate your understanding while we get things set up behind the scenes. Catch up on all the exciting details about the move here.
Need help or have questions? Drop us a line at [email protected]

Archives of Support Questions (Read Only)
- Cloudera Community
- Board Archive
- Archives of Support Questions (Read Only)
- Kudu web ui - cells read
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
Kudu web ui - cells read
- Labels:
-
Apache Kudu

Created on 01-29-2018 10:47 AM - edited 09-16-2022 05:48 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Hi,
I thought that during a particular scan Kudu is reporting a number of rows reand in realt-time per each column. At least on small table it was equal to roughly the number of rows in the partition.
But now I am scanning a 1 billion (1 000 000 000) row table, the table is partitioned into multiple partitions. And the cells read shows 2.3billion 4.6 billion etc.
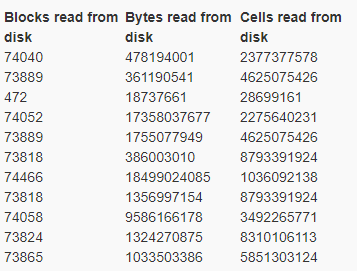
Can somebody explain why those numbers are so high?
Created 01-31-2018 06:31 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Found out that if multiple spark tasks are reading the same tablet (partition) then it counts multiple times the reads. Therefore the total cells read could be much higher than the number of rows in tablet, actual # of tasks x # rows.
Created 01-31-2018 06:30 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Found out that if multiple spark tasks are reading the same tablet (partition) then it counts multiple times the reads. Therefore the total cells read could be much higher than the number of rows in tablet, actual # of tasks x # rows.


Created 01-31-2018 10:05 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
This dashboard shows counters for a single scan, and a single scan would
only come from a single task, not aggregate across them.
I am guessing you're hitting KUDU-2231, a performance bug recently fixed.
The bug fix appears in CDH 5.14.0. Since this is a performance issue that
is not a regression and does not affect correctness, we have not yet
backported to any prior releases.
-Todd
Created 01-31-2018 06:31 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Found out that if multiple spark tasks are reading the same tablet (partition) then it counts multiple times the reads. Therefore the total cells read could be much higher than the number of rows in tablet, actual # of tasks x # rows.


