
Our Community is getting an upgrade! To get everything ready for the relaunch, we’ll be placing the site in read-only mode starting September 21st.
We really appreciate your understanding while we get things set up behind the scenes. Catch up on all the exciting details about the move here.
Need help or have questions? Drop us a line at [email protected]

Archives of Support Questions (Read Only)
- Cloudera Community
- Board Archive
- Archives of Support Questions (Read Only)
- Spark Dataframe Query not working
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
Spark Dataframe Query not working
- Labels:
-
Apache Spark


Created 02-06-2017 02:17 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
I have been trying to make the following Dataframe query work but its not giving me the results. Can someone please help?
Is there a reference guide to see all the syntax to create dataframe queries? Here this is what I want - My dataframe df has many cols among which 4 are -
- id
- deviceFlag
- device
- domain
For all rows, if deviceFlag is set to 1, then form a string "device#domain" and store that value in a new col "id". Else, just take the value in the "device" col and store it in the new "id" col without any transformation. So I am creating a new column with the .withColumn and setting value for each row depending upon the corresponding values of "device" and "deviceFlag" cols in that row.
DataFrame result= df.withColumn("id",
    ((Column) when(df.col("deviceFlag").$eq$eq$eq(1),
        concat(df.col("device"), lit("#"),
            df.col("domain")))).otherwise(df.col("device")).alias("id"));


Created 02-07-2017 02:38 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
I think your solution is ok. Probably you have problem with the input data (Try to call df.show() and df.printSchema() with the original df before the transformation). I tried out your code with this class:
package com.hortonworks.spark.example;


import static org.apache.spark.sql.functions.when;
import static org.apache.spark.sql.functions.concat;
import static org.apache.spark.sql.functions.lit;

import org.apache.spark.api.java.JavaSparkContext;
import org.apache.spark.api.java.JavaRDD;
import org.apache.spark.SparkConf;
import org.apache.spark.sql.Column;
import org.apache.spark.sql.Dataset;
import org.apache.spark.sql.Row;
import org.apache.spark.sql.SQLContext;

import java.io.Serializable;
import java.util.Arrays;
import java.util.List;


public class SparkStarter {
  public static void main(String[] args) {
    new SparkStarter().run();
  }

  private void run() {

    SparkConf conf = new SparkConf().setAppName("test").setMaster("local[*]");
    JavaSparkContext sc = new JavaSparkContext(conf);

    List<Record> data = Arrays.asList(new Record(1, null, "b"),new Record(1, "a", "b"), new Record(0, "b", "c"));
    JavaRDD<Record> distData = sc.parallelize(data);
    SQLContext sql = new SQLContext(sc);
    Dataset<Row> df = sql.createDataFrame(distData, Record.class);

    df.withColumn("id",
        ((Column) when(df.col("deviceFlag").$eq$eq$eq(1),
            concat(df.col("device"), lit("#"),
                df.col("domain")))).otherwise(df.col("device")).alias("id")).show();
  }

  public static class Record implements Serializable {
    int deviceFlag;
    String device;
    String domain;

    public int getDeviceFlag() {
      return deviceFlag;
    }

    public void setDeviceFlag(int deviceFlag) {
      this.deviceFlag = deviceFlag;
    }

    public String getDevice() {
      return device;
    }

    public void setDevice(String device) {
      this.device = device;
    }

    public String getDomain() {
      return domain;
    }

    public void setDomain(String domain) {
      this.domain = domain;
    }

    public Record(int deviceFlag, String device, String domain) {
      this.deviceFlag = deviceFlag;
      this.device = device;
      this.domain = domain;

    }
  }
}
And it worked well:
+------+----------+------+----+
|device|deviceFlag|domain|  id|
+------+----------+------+----+
|  null|         1|     b|null|
|     a|         1|     b| a#b|
|     b|         0|     c|   b|
+------+----------+------+----+
What was your problem exactly?

Created 02-06-2017 03:36 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Try
df.withColumn("id",when($"deviceFlag"===1,concat($"device", lit("#"),$"domain")).otherwise($"device"));
Created 02-06-2017 04:18 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
@Karthik Narayanan - thanks, tried that but its giving me - " Incompatible operand types String and int" at the statement - when($"deviceFlag"===1. I am writing in java - is there something else I am missing?
Created 02-06-2017 04:27 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Try with a "1" , deviceflag may be a string so it needs to be compared with string .

Created on 02-06-2017 07:57 PM - edited 08-18-2019 04:55 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
This worked well for me in Spark (Scala), which looks to be the same as @Karthik Narayanan's answer:
import org.apache.spark.sql.SparkSession
import spark.implicits._

val data = Seq((1111, 1, "device1", "domain1"), (2222, 0, "device2", "domain2"), (3333, 1, "device3", "domain3"), (4444, 0, "device4", "domain4"))

val df = data.toDF("id","deviceFlag","device","domain")

df.show()

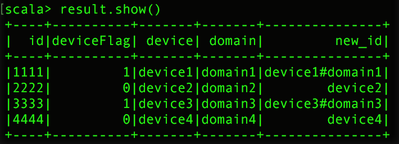
val result = df.withColumn("new_id", when($"deviceFlag"===1, concat($"device", lit("#"), $"domain")).otherwise($"device"))

result.show()
This will output:
As an alternative (and reference for others), the PySpark syntax will look like this:
from pyspark import SparkContext, SparkConf
from pyspark.sql import functions as F
from pyspark.sql.functions import lit, concat

data = [(1111, 1, 'device1', 'domain1'), (2222, 0, 'device2', 'domain2'), (3333, 1, 'device3', 'domain3'), (4444, 0, 'device4', 'domain4')]

df = spark.createDataFrame(data, ['id','deviceFlag','device','domain'])

df.show()

result = df.withColumn("new_id", F.when(df["deviceFlag"]==1, concat(df["device"], lit("#"), df["domain"])).otherwise(df["device"]))

result.show()
Hope this helps!
Created 02-06-2017 09:47 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Good pick Dan. Just noticed that Id was part of his original DF.
Created 02-06-2017 10:17 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Thanks for the detailed answer. My code is in Java so I am running into issues trying to convert this scala solution into Java. Any idea on what the version Java version of this could be?
@Karthik Narayanan - deviceFlag is Int so your comparison is correct. Just need the Java equivalent of this..
Created 02-07-2017 06:02 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
df.withColumn("id",when(df.col("deviceFlag").equalTo(1),concat(df.col("device"), lit("#"),df.col("domain"))).otherwise(df.col("device")));
Created 02-09-2017 07:09 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Thanks for the details, this is helpful
Created 02-07-2017 02:38 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
I think your solution is ok. Probably you have problem with the input data (Try to call df.show() and df.printSchema() with the original df before the transformation). I tried out your code with this class:
package com.hortonworks.spark.example;


import static org.apache.spark.sql.functions.when;
import static org.apache.spark.sql.functions.concat;
import static org.apache.spark.sql.functions.lit;

import org.apache.spark.api.java.JavaSparkContext;
import org.apache.spark.api.java.JavaRDD;
import org.apache.spark.SparkConf;
import org.apache.spark.sql.Column;
import org.apache.spark.sql.Dataset;
import org.apache.spark.sql.Row;
import org.apache.spark.sql.SQLContext;

import java.io.Serializable;
import java.util.Arrays;
import java.util.List;


public class SparkStarter {
  public static void main(String[] args) {
    new SparkStarter().run();
  }

  private void run() {

    SparkConf conf = new SparkConf().setAppName("test").setMaster("local[*]");
    JavaSparkContext sc = new JavaSparkContext(conf);

    List<Record> data = Arrays.asList(new Record(1, null, "b"),new Record(1, "a", "b"), new Record(0, "b", "c"));
    JavaRDD<Record> distData = sc.parallelize(data);
    SQLContext sql = new SQLContext(sc);
    Dataset<Row> df = sql.createDataFrame(distData, Record.class);

    df.withColumn("id",
        ((Column) when(df.col("deviceFlag").$eq$eq$eq(1),
            concat(df.col("device"), lit("#"),
                df.col("domain")))).otherwise(df.col("device")).alias("id")).show();
  }

  public static class Record implements Serializable {
    int deviceFlag;
    String device;
    String domain;

    public int getDeviceFlag() {
      return deviceFlag;
    }

    public void setDeviceFlag(int deviceFlag) {
      this.deviceFlag = deviceFlag;
    }

    public String getDevice() {
      return device;
    }

    public void setDevice(String device) {
      this.device = device;
    }

    public String getDomain() {
      return domain;
    }

    public void setDomain(String domain) {
      this.domain = domain;
    }

    public Record(int deviceFlag, String device, String domain) {
      this.deviceFlag = deviceFlag;
      this.device = device;
      this.domain = domain;

    }
  }
}
And it worked well:
+------+----------+------+----+
|device|deviceFlag|domain|  id|
+------+----------+------+----+
|  null|         1|     b|null|
|     a|         1|     b| a#b|
|     b|         0|     c|   b|
+------+----------+------+----+
What was your problem exactly?


