Our Community is getting an upgrade! To get everything ready for the relaunch, we’ll be placing the site in read-only mode starting September 21st.
We really appreciate your understanding while we get things set up behind the scenes. Catch up on all the exciting details about the move here.
Need help or have questions? Drop us a line at [email protected]
Created on
08-02-2018
04:13 PM
- edited on
04-21-2026
06:27 AM
by
GrazittiAPI
This article is designed to extend my articles Twitter Sentiment using Spark Core NLP in Apache Zeppelin and Connecting Solr to Spark - Apache Zeppelin Notebook
I have included the complete notebook on my Github site, which can be found on my GitHub site.
Step 1 - Follow the tutorial in the provide articles above, and establish an Apache Solr collection called "tweets"
Step 2 - Verify the version of Apache Spark being used, and visit the Solr-Spark connector site. The key is to match the version of Spark the version of the Solr-Spark connector. In the example below, the version of Spark is 2.2.0, and the connector version is 3.4.4
%spark2
sc
sc.version
</p><p>
Step 3 - Include the Solr-Spark dependency in Zeppelin. Important note: This needs to be run before
the Spark Context has been initialized</p>
<pre>%dep
z.load("com.lucidworks.spark:spark-solr:jar:3.4.4")
//Must be used before SparkInterpreter (%spark2) initialized
//Hint: put this paragraph before any Spark code and restart Zeppelin/Interpreter
Step 4 - Download the Stanford CoreNLP libraries found on here: <a href="http://nlp.stanford.edu/software/stanford-corenlp-full-2018-02-27.zip">http://nlp.stanford.edu/software/stanford-corenlp-full-2018-02-27.zip</a>
Upzip the download and move it to the /tmp directory. Note: This can be accomplished
on the command line or the following Zeppelin paragraph will work as well
%sh
wget /tmp/stanford-corenlp-full-2018-02-27.zip http://nlp.stanford.edu/software/stanford-corenlp-full-2018-02-27.zip unzip /tmp/stanford-corenlp-full-2018-02-27.zip
Step 5 - In Zeppelin's
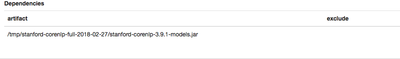
Interpreters configurations for Spark, include the following artifact:
/tmp/stanford-corenlp-full-2018-02-27/stanford-corenlp-3.9.1-models.jar

Step 6 - Include the following Spark dependencies for Stanford CoreNLP and Spark CoreNLP. Important
note: This needs to be run before the Spark Context has been initialized
%dep
z.load("edu.stanford.nlp:stanford-corenlp:3.9.1")
//In Spark Interper Settings Add the following artifact
// /tmp/stanford-corenlp-full-2018-02-27/stanford-corenlp-3.9.1-models.jar
%dep
z.load("databricks:spark-corenlp:0.2.0-s_2.11")
Step 7 Include the following Spark dependencies for
JPMML-SparkML and JPMML-Model. Important note: This needs to be run before the Spark Context has been initialized.
%dep
z.load("org.jpmml:jpmml-sparkml:1.4.5")
</p><pre>%dep
z.load("org.jpmml:pmml-model:1.4.5")
Step 8 - Run Solr query and return results into Spark DataFrame. Note: Zookeeper host might need to use full names:
"zkhost" -> "host-1.domain.com:2181,host-2.domain.com:2181,host-3.domain.com:2181/solr"
%spark2
val options = Map( "collection" ->
"Tweets", "zkhost" -> "localhost:2181/solr",
// "query" -> "Keyword, 'More Keywords'"
)
val df = spark.read.format("solr").options(options).load df.cache()
</p><p>
Step 9 - Review results of the Solr query</p><pre>%spark2
df.count()
df.printSchema()
df.take(1)
</p><p>
Step 10 - Filter the
Tweets in the Spark DataFrame to ensure the Tweet text isn't null Once filter
has been completed, add the sentiment value to the tweets.</p>
<pre>%spark2
import org.apache.spark.sql.functions._
import org.apache.spark.sql.types._
import com.databricks.spark.corenlp.functions._
val df_TweetSentiment = df.filter("text_t is not null").select($"text_t", sentiment($"text_t").as('sentimentScore))
Step 11 - Valid
results
%spark2
df_TweetSentiment.cache()
df_TweetSentiment1.printSchema()
df_TweetSentiment1.take(1)
df_TweetSentiment1.count()
Step 12 - Build Stages
to build features that will be fed into a Logistic Regression model for
classification
Stage 1 -Regex Tokenizer will be used to separate
each word into individual "tokens"
Stage 2 -Count Vectorizer will count the number
of occurrences each token occurs in the text corpus
Stage 3 -Term frequency-inverse document
frequency (TF-IDF) is a feature vectorization method widely used in text mining
to reflect the importance of a term to a document in the corpus.
Stage 4 -Logistic
Regression for classification to predict sentiment score
%spark2
import org.apache.spark.ml.feature.{HashingTF, IDF, Tokenizer, RegexTokenizer, CountVectorizer, CountVectorizerModel}
import org.apache.spark.ml.classification.LogisticRegression
val tokenizer = new RegexTokenizer()
.setInputCol("text_t")
.setOutputCol("words")
.setPattern("\W+")
.setGaps(true)
val wordsData = tokenizer.transform(df_TweetSentiment)
val cvModel = new CountVectorizer()
.setInputCol("words").setOutputCol("rawFeatures")
.setMinDF(4)
.fit(wordsData)
val featurizedData = cvModel.transform(wordsData)
val idf = new IDF()
.setInputCol("rawFeatures")
.setOutputCol("features")
val idfModel = idf.fit(featurizedData)
val rescaledData = idfModel.transform(featurizedData)
rescaledData.select("sentimentScore", "features").show()
val lr = new LogisticRegression()
.setMaxIter(10)
.setRegParam(0.001)
.setLabelCol("sentimentScore")
Step 13 - Build Spark Pipeline from Stages
%spark2
import org.apache.spark.ml.{Pipeline, PipelineModel}
import org.apache.spark.ml.classification.LogisticRegression
import org.apache.spark.ml.linalg.Vector
import org.apache.spark.sql.Row
import org.apache.spark.sql.types.StructType
val pipeline = new Pipeline()
.setStages(Array(tokenizer, cvModel, idfModel, lr))
val PipeLineModel = pipeline.fit(df_TweetSentiment)
//Save Pipeline to Disk (Optional)
PipeLineModel.write.overwrite().save("/tmp/spark-IDF-model")
val schema = df_TweetSentiment.schemaStep 14 - Export Spark Pipeline to PMML using JPMML-SparkML
%spark2
import org.jpmml.sparkml.PMMLBuilder
import java.io.File
val pmml = new PMMLBuilder(schema, PipeLineModel)
val file = pmml.buildFile(new File("/tmp/TweetPipeline.pmml"))
Created on 10-31-2018 12:13 AM
Hi Ian! Thanks for posting this article.
At the "pmml.buildFile" I'm getting the following error: java.lang.IllegalArgumentException: iperbole_
Any ideas? Thank you very much!