Our Community is getting an upgrade! To get everything ready for the relaunch, we’ll be placing the site in read-only mode starting September 21st.
We really appreciate your understanding while we get things set up behind the scenes. Catch up on all the exciting details about the move here.
Need help or have questions? Drop us a line at [email protected]

Support Questions

Find answers, ask questions, and share your expertise
Announcements
Share your experience with Cloudera on G2 and get a $25 Amazon Gift card.
Hi, I'm CLEO! Something exciting is coming to the Community. Stay Tuned!
Pyspark Dataframe into Impala table ==> syntax error

avatar
Explorer

Dear all,

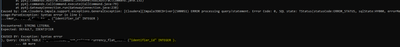
I am trying to load a PySpark Dataframe into an Impala table, using the jdbc connector. However, the df.write statement fails, because the "Create table" - statement that is generated contains quotation marks for the column names:

Ploeplse_0-1663060600342.png

Do you have any idea how to get rid of these quotation marks? If not, what would be a different approach to load a dataframe into an Impala table?

I also tried 

spark.sql('select identifier_id as identifier from tempView').write.jdbc(...), but here I am getting the error "File /tmp/hive does not exist".


Thanks a lot in advance for any help!


3 REPLIES 3

avatar
Master Collaborator

Hi @Ploeplse 

Could you please share reproducible sample code and impala tab creation script?

avatar
Community Manager

HI @Ploeplse, If you are still experiencing the issue, can you provide the information @RangaReddy   has requested?


Regards,

Vidya Sargur,
Community Manager


Was your question answered? Make sure to mark the answer as the accepted solution.
If you find a reply useful, say thanks by clicking on the thumbs up button.
Learn more about the Cloudera Community:

avatar
Master Collaborator

Hi @Ploeplse 


Still, if you are facing the issue, could you share the requested information (i.e code and impala table creation script)