
Our Community is getting an upgrade! To get everything ready for the relaunch, we’ll be placing the site in read-only mode starting September 21st.
We really appreciate your understanding while we get things set up behind the scenes. Catch up on all the exciting details about the move here.
Need help or have questions? Drop us a line at [email protected]

Support Questions
 Hi, I'm CLEO! Something exciting is coming to the Community. Stay Tuned!
- Cloudera Community
- Support
- Support Questions
- Reading CSV File Spark - Issue with Backslash
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
Reading CSV File Spark - Issue with Backslash
- Labels:
-
Apache Spark

Created 02-09-2023 03:45 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
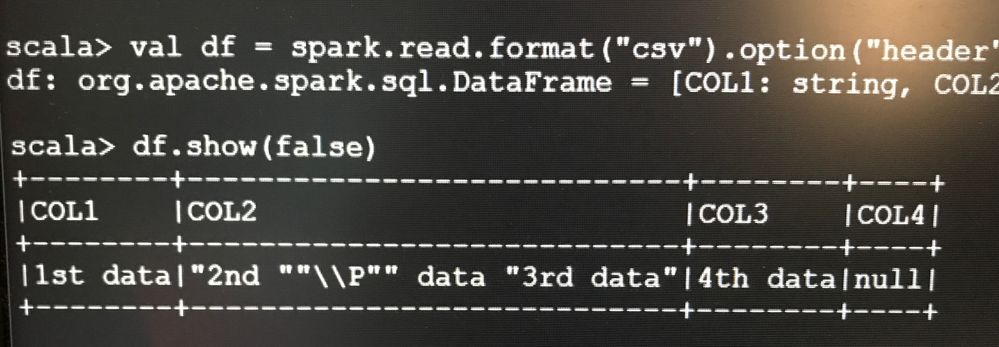
I'm facing weird issue, not sure why Spark is behaving like this.
samplefile.txt:
COL1|COL2|COL3|COL4
"1st Data"|"2nd ""\\\\P"" data"|"3rd data"|"4th data"
This is my spark code to read data:
val df = spark.read.format("csv").option("header","true").option("inferSchema","true").option("delimiter","|").load("\samplefile.xtx")
df.show(false)
Some how it is combining 2 columns data into one. Spark Scala : 2.4 Version
Any idea why spark is behaving like this.


Created on 03-30-2023 04:25 AM - edited 03-30-2023 04:26 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
You need to adjust the csv file
sample.csv
=========
COL1|COL2|COL3|COL4
1st Data|2nd|3rd data|4th data
1st Data|2nd \\P data|3rd data|4th data
"1st Data"|"2nd '\\P' data"|"3rd data"|"4th data"
"1st Data"|"2nd '\\\\P' data"|"3rd data"|"4th data"
Spark Code:
spark.read.format("csv").option("header","true").option("inferSchema","true").option("delimiter","|").load("/tmp/sample.csv").show(false)
Output:
+--------+--------------+----------+--------+
|COL1 |COL2 |COL3 |COL4 |
+--------+--------------+----------+--------+
|1st Data|2nd |3rd data |4th data|
|1st Data|2nd \\P data |3rd data |4th data|
|1st Data|2nd '\P' data |3rd data |4th data|
|1st Data|2nd '\\P' data|3rd data |4th data|
+--------+--------------+----------+--------+

Created 02-09-2023 05:53 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
@ShobhitSingh You need to handle the escape with another option:
.option("escape", "\\")You may need to experiment with the actual string in the match argument ("//") to suit your needs. Be sure to check spark docs specific to your version. For example:
https://spark.apache.org/docs/latest/sql-data-sources-csv.html
Created 02-09-2023 06:29 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Hi Steven,
Even if my data is like this, its causing issue.
"1st Data"|"2nd ""\P"" data"|"3rd data"|"4th data"What is causing issue? Any Idea.
I know spark is having default escape as backslash. But why it is behaving like this.
Created 02-09-2023 06:31 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Click into that doc and check out the other escape option. I think you need to handle the quotes too.
Created on 03-30-2023 04:25 AM - edited 03-30-2023 04:26 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
You need to adjust the csv file
sample.csv
=========
COL1|COL2|COL3|COL4
1st Data|2nd|3rd data|4th data
1st Data|2nd \\P data|3rd data|4th data
"1st Data"|"2nd '\\P' data"|"3rd data"|"4th data"
"1st Data"|"2nd '\\\\P' data"|"3rd data"|"4th data"
Spark Code:
spark.read.format("csv").option("header","true").option("inferSchema","true").option("delimiter","|").load("/tmp/sample.csv").show(false)
Output:
+--------+--------------+----------+--------+
|COL1 |COL2 |COL3 |COL4 |
+--------+--------------+----------+--------+
|1st Data|2nd |3rd data |4th data|
|1st Data|2nd \\P data |3rd data |4th data|
|1st Data|2nd '\P' data |3rd data |4th data|
|1st Data|2nd '\\P' data|3rd data |4th data|
+--------+--------------+----------+--------+

