Find answers, ask questions, and share your expertise
Recently active
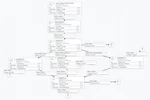
Hi All, I am building Nifi flow which fetch the filename.zip from shared server and unpack the .zip file then distributes the files across nifi cluster and finally put the files in HDFS. By doing this process , i am collecting success or failure status of each processors using custom message inUpdateattribute processor . Refer the sample attached screen-print for updateattribute processor . Next i am planning to update overall status(success or error) of .zip file along with each file processed status ,like combining all information into one file and push the file to shared server to know about the status. I tried to use Mergecontent processor but i am unable to update the .zip file status and also noticed that if there is a delay in processing How to build the flowfile like below Filename.zip:staus:error_messageFilename1.status:sucess_messageFilename2:status:success_messageFilename3:status:error_message Going forward i may also update the status me
Hi, I am trying to download the ambari repo for RHEL 6 from the cloudera site. but its asking for username and password. Not sure why ? has any policy been changed ? I was able to download this till last month. Below is URL for reference: http://public-repo-1.hortonworks.com/ambari/centos6/2.x/updates/2.4.3.0/ambari.repo Below error shows on web page:<Error><Code>AccessDenied</Code><Message>Access Denied</Message><RequestId>6AB2932EB30E54AC</RequestId> </Error> Thanks
Hello ,We have one use case where we need to connect to HDF schema registry using Python Library .We have installed python-schema-registry-client library. But Schema registry URL is kerberos authenticated URL so couldn't connect with below code from schema_registry.client import SchemaRegistryClient, schemaclient = SchemaRegistryClient(url="http://127.0.0.1:8081") provided here https://marcosschroh.github.io/python-schema-registry-client/Getting Authentication error 401.Is there any extra arguments or methods to get connect to Schema registry using python library? Thanks and Regards
Hi, I was trying to use nifi.provenance.repository.implementation=org.apache.nifi.provenance.WriteAheadProvenanceRepository. To do so i have to comment java.arg.13=-XX:+UseG1GC to get rid of any performance issues as per https://community.cloudera.com/t5/Community-Articles/HDF-CFM-NIFI-Best-practices-for-setting-up-a-high/ta-p/244999However i find it difficult on how to do it via Cloudera Manager. Please help.
Hue audits are not logging consistently /var/log/hue/audit/ on CDH 5.16.2 any ideas, is this a bug?
Hello,We have upgraded CM from 5.16.2 to 6.3.4 has finished successfuly. However, after restarting the CM agents and checking the "Review Upgrade Status" we are getting the following warnings: "View Details 2 hosts are running CDH 5 and 0 hosts are running CDH 6. There are mismatched versions across the system, which will cause failures. See below for details on which hosts are running what versions of components. Component : Supervisord Version / Host:3.4.0 / Server1 3.4.0-cm6.3.4 / Server2 " We have also tried a hard_restart of the CM agents and we are still getting the error message.Does anyone know why this can happen?Thank you in advance.
Hello,I try to work out some automated deployment situation in NiFi (no UI usage, just cli toolkit or alternatives). Let us asume, you have a nifi flow under a load which need to be updated.There are some data in in-between connection queues.What happens when you try to update the flow?Will some data be lost or will the update be refused? Are there any solution for procedure like this.1) stop the data receiving processor2) check if the success connection queue is empty3) apply steps 1 and 2 to the next processor till the last processor is stopped.4) update the flow ignoring any data in failure or error connection queues Do you think it is reasonable approach? Is there something ready to use?Best regardsJaro
http://archive-primary.cloudera.com/cdh5/cdh/5/ for download client tarballs is not available. Has it been moved to somewhere else ? Thanks in advance.
Hello, I am working through this tutorial: https://www.cloudera.com/tutorials/tour-of-cloudera-data-science-workbench.html. I'm able to install the libraries just fine. When I go to run the python script (Sharing Results section), it appears to start processing the code, then it refreshes a few times, and finally it crashes. Is this a known issue?
Hello,We are uploading the version of our clusters to 6.3. During this process, we have found the need to also upgrade the Oracle database to version 19.The Oracle upgrade was done but the process slowed down due to many Cloudera Manager objects in the Oracle database recycle bin.A simply and maybe a stupid question but... Do you know if Cloudera Manager can be affected if we disable the Oracle recycle bin?Thank you
Hi All, Currently we are building a Java application to connect hive database to perform data transfer. We are encountering issue while issuing the below query through java application"select count(*) from tablename where partition_key='xxxxx'".The above table is partitioned by partition_key column. below is the complete error log from Java ### Error querying database. Cause: java.sql.SQLException: [Cloudera][HiveJDBCDriver](500051) ERROR processing query/statement. Error Code: [Cloudera][JSQLEngine](12010) The table "dbname"."tablename" could not be found., SQL state: HY000, Query: select count(*) from dbname.tablename where partition_key='201912310002' .### The error may exist in com/hds/datatransfer/mapper/hive/HiveRepository.java (best guess)### The error may involve com.hds.datatransfer.mapper.hive.HiveRepository.test1### The error occurred while executing a query### SQL: select count(*) from dbname.tablename where partition_key='201912310002' ### Cause: java.
Hi, these repos now ask for authentication. https://archive.cloudera.com/cdh5/redhat/6/x86_64/cdh/5/https://archive.cloudera.com/cm5/redhat/6/x86_64/cm/5/ are they still available?
I'm trying to convert local json file with getfile processor into parquet file on HDFS. I'm following this guide: https://medium.com/@abdelkrim.hadjidj/using-apache-nifi-for-json-to-parquet-conversion-945219d5caba I choose Record Reader of JsonTreeReader, but I don't see any of the schema properties in the putparquet processor? (Schema Access Strategy, Schema Text). How do I get those to show up, or how do I enter them manually?
The GetSFTP processor is throwing the FlowFileAccessException when trying to read a file from a remote directory.If I look at the error stack trace I can see that at StreamUtils.copy is where IOException has happened.Is it something like file was moved when actually reading it ?Can you guys please help me understand why this issue occurring and how I can avoid it ?o.a.nifi.processors.standard.GetSFTP GetSFTP[id=7d5fe4b5-7b67-3779-8de7-00e903c20c34] Unable to retrievefile FILENAME due to org.apache.nifi.processor.exception.FlowFileAccessException: Unable to create ContentClaim due to java.io.IOException: error: org.apache.nifi.processor.exception.FlowFileAccessException: Failed to import data from com.jcraft.jsch.ChannelSftp$2@6e1e8c5e for StandardFlowFileRecord[uuid=a50179f7-b631-4aa8-9e74-a2dca44d89bd,claim=,offset=0,name=a50179f7-b631-4aa8-9e74-a2dca44d89bd,size=0] due to org.apache.nifi.processor.exception.FlowFileAccessException: Unable to create ContentClaim due to java.
Hi All, I need to migrate existing MySql DBs used for metastore, cmserver, amon, rman, oozie, hue and sentry to another MySql DB instance (MySql version 5.5). We are using CDH 5.16 and it contains 300TB data. Migration need to be done smoothly with less interruption to production workload. Appreciate if you can share the instructions/ related documents to do this. Thank you
Hello,I have tried to use nifi cli toolkit (nifi 1.11.4) to set parameter like this. However, I can't see any effect.What have I doing wrong? #> nifi get-param-context -u http://localhost:8080 -pcid 828f0882-0177-1000-aabd-d680a070c5c5# Name Value Sensitive Description- ------------- ------------- --------- -----------1 sample.Passwd ******** true2 sample.Schema SAMPLE001 false3 sample.URL jdbc://sample false4 sample.User dbsample false #> nifi set-param -u http://localhost:8080 -pcid 828f0882-0177-1000-aabd-d680a070c5c5 -pn sample.URL newvalueWaiting for update request to complete... #> nifi get-param-context -u http://localhost:8080 -pcid 828f0882-0177-1000-aabd-d680a070c5c5# Name Value Sensitive Description- ------------- ------------- --------- -----------1 sample.Passwd ******** true2 sample.Schema SAMPLE001 false3 sample.URL jdbc://sample false4 sample.User dbsample falseBest regardsJaroJaro
we have kafka cluster with 3 brokers machines and 3 zookeeper servers machines all servers are installed on redhat 7.2 version but when we run the following cli ( to know that all brokers ids are exist in zookeeper , we get: zookeeper-shell.sh zoo_server:2181 <<< "ls /brokers/ids"WATCHER::WatchedEvent state:SyncConnected type:None path:null[3, 2]instead to get that:[3, 2 , 1] we checked the first broker ( kafka01 ) by searching errors in server.log And we not see any related error in the log! port 2181 from kafka broker to zookeeper machine is working we also restart kafka01 , but this not help to get the broker id in zookeeper cli we try also to restart all zookeeper servers ( there are 3 ) , and then again to restart kafka01 , but still without results so any suggestion to this behavior? can we add the missing broker to zookeeper cli ? , if yes then how? note - I see another thread - https://community.cloudera.com/t5/Support-Questions/Specified-config-do
Hello everyone, i have data which has only one value per line, often not even a header. My goal is to conert the data to csv and format it afterwards (remove the comments and add some columns). Example base data:#This is my base data##################value1value2value3 Example finished data:value-description, source, timestampvalue1, source1, 984359345value2, source1, 98249732value3, source1, 984u9834 Right now I'm able to achieve the output if I have an input which is already in a CSV format (comma separated). But if I try is with the example data above the output is the following: header-descriptionvalue1value2value3 This happens after the ReplaceText processor which should delete blank lines. The source and timestamp column is not yet added. This is the config of the processor: I am glad about every response. Best regardsMaurice
The "Audit" tab is missing from Ranger UI. It was working fine before. We have not made any changes to the cluster.I'm unable to find any article regarding this issue. I'm hoping go them some help from the community.Thanks. The audit logs are working coming to HDFS just fine. [hdfs@mynode~]$ hdfs dfs -ls /ranger/audit/Found 7 itemsdrwx------ - hdfs hdfs 0 2021-02-05 00:00 /ranger/audit/hdfsdrwx------ - hive hive 0 2019-05-22 15:18 /ranger/audit/hive2drwx------ - hive hive 0 2021-02-05 00:00 /ranger/audit/hiveServer2drwxr-x--- - kms kms 0 2021-02-05 00:00 /ranger/audit/kmsdrwx------ - knox knox 0 2017-01-19 15:48 /ranger/audit/knoxdrwxr-x--- - nifi nifi 0 2021-02-04 18:00 /ranger/audit/nifidrwx------ - yarn yarn 0 2021-02-05 00:00 /ranger/audit/yarn Components version: HDP: 2.6.5.0Ranger: 0.7.0Ambari Infra: 0.1.0 Ranger Audit Config:
I use HDP 3.1.4 and ambari 2.7.4.0 When adding a data node, the following error occurs. failure: repodata/repomd.xml from ambari-2.7.4.0: [Errno 256] No more mirrors to try.http://public-repo-1.hortonworks.com/ambari/centos7/2.x/updates/2.7.4.0/repodata/repomd.xml: [Errno 14] HTTP Error 403 - Forbidden What do i do? Thank you.
Hi, I've got 404 on:https://archive.cloudera.com/cdh5/redhat/7/x86_64/cdh/5.15.1/https://archive.cloudera.com/cdh5/redhat/7/x86_64/cdh/RPM-GPG-KEY-cloudera changed archive path/url? what is the new one? * url's took from https://docs.cloudera.com/documentation/enterprise/5-8-x/topics/cdh_ig_cdh5_install.html
Hi, this link was working fine till morning and suddenly started displaying 404 error,maintenance window or location changed?
hello All,For now, I getting 404 error when trying to install CDH5( I tried install 5.13.0 version components ) components via yum on centos7. This work for me in Thursday. Would some one help me with this?
I am using CDH 6.3.0 HBase. Several regionserver's WALs logs directory(/hbase/wals) keep growing and logs are not moved to /hbase/oldWals for deletion. When digging the regionserver logs, i found the following logs, it happens when there are heavy write load. 2021-01-27 14:49:16,370 WARN org.apache.hadoop.hbase.regionserver.LogRoller: Failed to schedule flush of region_id_xxxxxxxx, region=null, requester=null I suspect that we come across HBASE-16721(Concurrency issue in WAL unflushed seqId tracking), however CDH 5.8.x has already fix this issue, so how come we meet this in 6.3.0. HBase regionserver WAL relevant config: hbase.regionserver.maxlogs: 64heap size: 36Gwal blocksize: 256M so if wal logs not archived for Concurrency issue, how to fix it; or are there any other reasons that could cause the phenomenonAny help would be appreciated !!@gsharma @elserj
Hi member, Could you please help my concern ? CDP Private Cloud Base 7.1.5 has Ranger 2.1.0, so we can try to use presto plugin.However, I find that Cloudera CDP Private Cloud Base 7.1.5 don't list presto plugin at at Ranger library.So, could you please let me know how to install / integrate presto plugin into CDP Private Cloud Base 7.1.5 ?Of course, I know Cloudera cannot support Presto but we really need to use Presto for our business.It would be grateful if you could give any advices. Cloudera Runtime component versions (7.1.5) :https://docs.cloudera.com/cdp-private-cloud-base/7.1.5/runtime-release-notes/topics/rt-pvc-runtime-component-versions.html Much appreciate,
Already have an account? Login
Enter your E-mail address. We'll send you an e-mail with instructions to reset your password.