
Our Community is getting an upgrade! To get everything ready for the relaunch, we’ll be placing the site in read-only mode starting September 21st.
We really appreciate your understanding while we get things set up behind the scenes. Catch up on all the exciting details about the move here.
Need help or have questions? Drop us a line at [email protected]

Archives of Support Questions (Read Only)
- Cloudera Community
- Board Archive
- Archives of Support Questions (Read Only)
- Re: How to fix corrupt blocks
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
How to fix corrupt blocks
- Labels:
-
Apache Hadoop

Created 05-30-2016 04:54 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
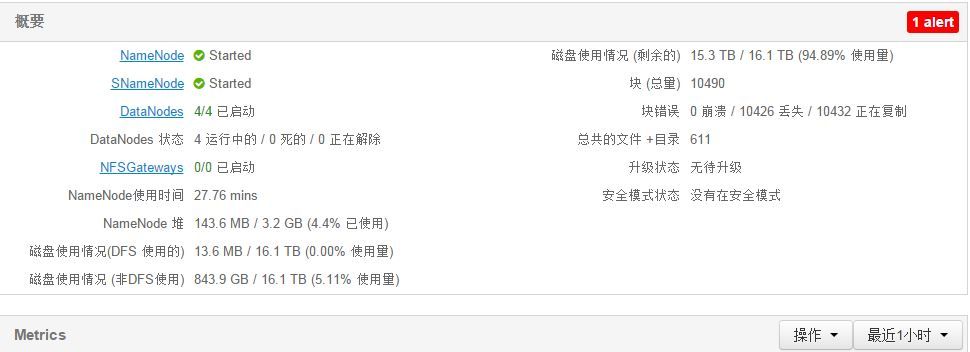
I make a cluster used ambari included 1 namenode and 4 datanode on vmware. A datanode was broken ,so I deleted this one and created a new datanode .But cluster created CORRUPT blocks .I try to "hdfs fsck -delete / " to fix it, but lost lots of data. how to fix corrupt blocks ?


Created 05-30-2016 04:56 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Please refer to below link that explains how to find corrupted blocks and fix them.
http://stackoverflow.com/questions/19205057/how-to-fix-corrupt-hadoop-hdfs
Hope this helps.
Thanks and Regards,
Sindhu

Created 05-30-2016 05:03 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
What is the replication factor defined, as 1 datanode down should not cause the corruption. Were other datanodes also down at the same time?

Created 05-30-2016 05:15 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
The best way is to find which are corrupted blocks using below command -
hdfs fsck /path/to/corrupt/file -locations -blocks -filesAnd then try to manually remove this using "hadoop rm -r </path>" to avoid dataloss.
But still fsck does not remove good copied of data blocks.


