
Our Community is getting an upgrade! To get everything ready for the relaunch, we’ll be placing the site in read-only mode starting September 21st.
We really appreciate your understanding while we get things set up behind the scenes. Catch up on all the exciting details about the move here.
Need help or have questions? Drop us a line at [email protected]

Archives of Support Questions (Read Only)
- Cloudera Community
- Board Archive
- Archives of Support Questions (Read Only)
- Re: Minimal executable jar based on Scala code pac...
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
Minimal executable jar based on Scala code packed with Maven
- Labels:
-
Apache Spark

Created on 03-21-2017 02:59 PM - edited 08-18-2019 04:06 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Hi folks,
I would like to make a minimal example packed with Maven based on Scala code (like a hello world) and run it on a HDP2.5 sandbox. What do I need to specify in my pom.xml? So far I have this:
<project xmlns="http://maven.apache.org/POM/4.0.0" xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance" xsi:schemaLocation="http://maven.apache.org/POM/4.0.0 http://maven.apache.org/maven-v4_0_0.xsd">
  <modelVersion>4.0.0</modelVersion>
  <groupId>com.test.spark</groupId>
  <artifactId>Test</artifactId>
  <version>0.0.1</version>
  <name>${project.artifactId}</name>
  <description>Simple test app</description>
  <inceptionYear>2017</inceptionYear>

  <!-- change from 1.6 to 1.7 depending on Java version -->
  <properties>
    <maven.compiler.source>1.6</maven.compiler.source>
    <maven.compiler.target>1.6</maven.compiler.target>
    <encoding>UTF-8</encoding>
    <scala.version>2.11.5</scala.version>
    <scala.compat.version>2.11</scala.compat.version>
    <spark.version>1.6.1</spark.version>
  </properties>

  <dependencies>
    <dependency>
      <groupId>org.scala-lang</groupId>
      <artifactId>scala-library</artifactId>
      <version>${scala.version}</version>
    </dependency>

    <!-- Spark dependency -->
    <dependency>
        <groupId>org.apache.spark</groupId>
        <artifactId>spark-core_${scala.compat.version}</artifactId>
        <version>${spark.version}</version>
    </dependency>
    <!-- Spark sql dependency -->
    <dependency>
        <groupId>org.apache.spark</groupId>
        <artifactId>spark-sql_${scala.compat.version}</artifactId>
        <version>${spark.version}</version>
    </dependency>
    <!-- Spark hive dependency -->
    <dependency>
        <groupId>org.apache.spark</groupId>
        <artifactId>spark-hive_${scala.compat.version}</artifactId>
        <version>${spark.version}</version>
    </dependency>
 </dependencies>

  <build>
    <sourceDirectory>src/main/scala</sourceDirectory>
    <!-- Create JAR with all dependencies -->
    <plugins>
       <plugin>
        <artifactId>maven-assembly-plugin</artifactId>
        <version>3.0.0</version>
        <executions>
          <execution>
            <phase>package</phase>
            <goals>
              <goal>single</goal>
            </goals>
          </execution>
        </executions>
        <configuration>
          <descriptorRefs>
            <descriptorRef>jar-with-dependencies</descriptorRef>
          </descriptorRefs>
        </configuration>
      </plugin>
      <plugin>
        <!-- see http://davidb.github.com/scala-maven-plugin -->
        <groupId>net.alchim31.maven</groupId>
        <artifactId>scala-maven-plugin</artifactId>
        <version>3.2.2</version>
        <configuration>
            <scalaVersion>${scala.version}</scalaVersion>
            <scalaCompatVersion>${scala.compat.version}</scalaCompatVersion>
        </configuration>
        <executions>
          <execution>
            <phase>compile</phase>
            <goals>
              <goal>compile</goal>
            </goals>
          </execution>
        </executions>
      </plugin>
    </plugins>
  </build>
</project>
And my scala code is this:
package com.test.spark

import org.apache.spark.SparkContext
import org.apache.spark.SparkConf
import org.apache.spark.sql
import org.apache.commons.lang
import org.apache.spark.sql.SQLContext
import org.apache.spark.sql.hive.HiveContext
import org.apache.spark.rdd.RDD

object Test {
 def main(args: Array[String]) {
 val conf = new SparkConf().setAppName("Test") .setMaster("local[2]")
 val spark = new SparkContext(conf)
 println( "Hello World!" )
 }
}
I run the code with
spark-submit --class com.test.spark.Test --master yarn --deploy-mode cluster hdfs://HDP25/test.jar
Unfortunately it does not run. 😞 See the image attached.
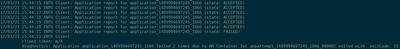
Am I missing something? Can you please help me to get a minimal example running?
Thanks and kind regards

Created 03-22-2017 04:45 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Thanks @Ken Jiiii
Looking at your error, application master failed 2 times due to exit code 15, Did you check your /spark/conf if you have placed hive-site.xml and in your code can you try removing " .setMaster("local[2]") " as you are running on yarn.
try running it
spark-submit --class com.test.spark.Test --master yarn-cluster hdfs://HDP25/test.jar


Created 03-21-2017 04:48 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
First things first: it was not clear to me, if you can build your project and create a jar file by running a maven command? Once you can build a jar file out of your project, your pom.xml is fine.
To check your pom.xml, run this command:
mvn package
If it returns en error, please update your original post and include the mvn error
Created 03-21-2017 05:20 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Hi pbarna,
Oh I am sorry. Yes I could run mvn package without any errors (at the beginninh some dependencies were missing but I fixed that). The error in my original post is when I try to run my paavked jar on HDP. So I do not need any cluster or Hortonworks specific things in my pom, right?
Created 03-21-2017 08:57 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
You can follow this link where you have example and pom.xml. and answering to questions " I do not need any cluster or Hortonworks specific things in my pom, right? " Yes you dont need. All those values should be in you code or client configs ( core-site.xml, yarn-site.xml )
Created 03-22-2017 06:41 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Hi @Vinod Bonthu,
Thanks gor the quick guide but I have a follow up question. So it seems my pom is fine since I can package it with maven. Although when I run it via "spark-submit" I get the error stated in my original post. But when I run one of the spark examples by executing below code works. So why is that? I have the feeling that still something is not right and as a forst step I just want to run an example code packaged by myself via spark-submit. Afterwards I will try an oozie workflow.
Thanks again!
spark-submit org.apache.spark.exaples.SOMEEXAMPlE --master yarn-cluster hdfs://path-to-spark-examples.jar
Created 03-22-2017 10:18 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
have you copied the jar file to the hdfs? if you run this command, what is the result?
hadoop fs -ls /path/to/your/spark.jar
Created 03-22-2017 11:21 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Yes I did. The reult is
-rwxr-xr-x 3 USER USER 12252 2017-03-17 10:49 /path-to-jar/my.jar
And the ouput when I run the spark-commit command is stated above.

Created 03-22-2017 08:28 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Can you post the error logs which are given in the tracking url -
- For example, for application id application_1459318710253_0026, we check the logs at http://cluster.manager.ip:8088/cluster/app/application_1459318710253_0026
Created 03-22-2017 10:33 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
17/03/22 11:27:53 INFO HiveContext: Initializing execution hive, version 1.2.1
17/03/22 11:27:53 INFO ClientWrapper: Inspected Hadoop version: 2.7.3.2.5.0.0-1245
17/03/22 11:27:53 INFO ClientWrapper: Loaded org.apache.hadoop.hive.shims.Hadoop23Shims for Hadoop version 2.7.3.2.5.0.0-1245
17/03/22 11:27:53 INFO HiveMetaStore: 0: Opening raw store with implemenation class:org.apache.hadoop.hive.metastore.ObjectStore
17/03/22 11:27:53 INFO ObjectStore: ObjectStore, initialize called
17/03/22 11:27:53 WARN HiveMetaStore: Retrying creating default database after error: Class org.datanucleus.api.jdo.JDOPersistenceManagerFactory was not found.
javax.jdo.JDOFatalUserException: Class org.datanucleus.api.jdo.JDOPersistenceManagerFactory was not found.
        at javax.jdo.JDOHelper.invokeGetPersistenceManagerFactoryOnImplementation(JDOHelper.java:1175)
        at javax.jdo.JDOHelper.getPersistenceManagerFactory(JDOHelper.java:808)
        at javax.jdo.JDOHelper.getPersistenceManagerFactory(JDOHelper.java:701)
...
...
That is the first error I find in the logs in stderr. Another one is
17/03/22 11:27:53 INFO HiveMetaStore: 0: Opening raw store with implemenation class:org.apache.hadoop.hive.metastore.ObjectStore
17/03/22 11:27:53 INFO ObjectStore: ObjectStore, initialize called
17/03/22 11:27:53 WARN Hive: Failed to access metastore. This class should not accessed in runtime.
org.apache.hadoop.hive.ql.metadata.HiveException: java.lang.RuntimeException: Unable to instantiate org.apache.hadoop.hive.ql.metadata.SessionHiveMetaStoreClient
        at org.apache.hadoop.hive.ql.metadata.Hive.getAllDatabases(Hive.java:1236)
        at org.apache.hadoop.hive.ql.metadata.Hive.reloadFunctions(Hive.java:174)
        at org.apache.hadoop.hive.ql.metadata.Hive.<clinit>(Hive.java:166)
...
...
Can you make use of this?
Created 03-22-2017 04:45 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Thanks @Ken Jiiii
Looking at your error, application master failed 2 times due to exit code 15, Did you check your /spark/conf if you have placed hive-site.xml and in your code can you try removing " .setMaster("local[2]") " as you are running on yarn.
try running it
spark-submit --class com.test.spark.Test --master yarn-cluster hdfs://HDP25/test.jar


