
Our Community is getting an upgrade! To get everything ready for the relaunch, we’ll be placing the site in read-only mode starting September 21st.
We really appreciate your understanding while we get things set up behind the scenes. Catch up on all the exciting details about the move here.
Need help or have questions? Drop us a line at [email protected]

Archives of Support Questions (Read Only)
- Cloudera Community
- Board Archive
- Archives of Support Questions (Read Only)
- NoSuchMethodException when running %jdbc paragraph...
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
NoSuchMethodException when running %jdbc paragraph in Zeppelin
- Labels:
-
Apache Spark
-
Apache Zeppelin

Created on 07-05-2017 11:44 AM - edited 08-17-2019 05:42 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
I installed the Hortonworks Data Platform 2.6 (still un-kerberized at the moment), which includes Zeppelin 0.7 and Spark 1.6.3.
Zeppelin seems to be prepared for Spark 2.x and Scala 2.11, so I had to remove and re-install a new Spark interpreter for my Spark version 1.6.3 and Scala 2.10. Therefore I took the following link: https://zeppelin.apache.org/docs/0.6.1/manual/interpreterinstallation.html#install-spark-interpreter...
After restarting the Zeppelin service via Ambari, I was able to run this paragraph (which didnt work before):
%spark
sc.version
===========================
res0: String = 1.6.3
Now I'm trying to use the %jdbc interpreter (part of the SAP Vora installation), just to do some select statements:
%jdbc
select * from sys.tables using com.sap.spark.engines
======================================================================================================
java.lang.NoSuchMethodError: org.apache.hive.service.cli.thrift.TExecuteStatementReq.setQueryTimeout(J)V
 at org.apache.hive.jdbc.HiveStatement.runAsyncOnServer(HiveStatement.java:297)
 at org.apache.hive.jdbc.HiveStatement.execute(HiveStatement.java:241)
 at org.apache.commons.dbcp2.DelegatingStatement.execute(DelegatingStatement.java:291)
 at org.apache.commons.dbcp2.DelegatingStatement.execute(DelegatingStatement.java:291)
 at org.apache.zeppelin.jdbc.JDBCInterpreter.executeSql(JDBCInterpreter.java:581)
 at org.apache.zeppelin.jdbc.JDBCInterpreter.interpret(JDBCInterpreter.java:692)
 at org.apache.zeppelin.interpreter.LazyOpenInterpreter.interpret(LazyOpenInterpreter.java:97)
 at org.apache.zeppelin.interpreter.remote.RemoteInterpreterServer$InterpretJob.jobRun(RemoteInterpreterServer.java:490)
 at org.apache.zeppelin.scheduler.Job.run(Job.java:175)
 at org.apache.zeppelin.scheduler.ParallelScheduler$JobRunner.run(ParallelScheduler.java:162)
 at java.util.concurrent.Executors$RunnableAdapter.call(Executors.java:511)
 at java.util.concurrent.FutureTask.run(FutureTask.java:266)
 at java.util.concurrent.ScheduledThreadPoolExecutor$ScheduledFutureTask.access$201(ScheduledThreadPoolExecutor.java:180)
 at java.util.concurrent.ScheduledThreadPoolExecutor$ScheduledFutureTask.run(ScheduledThreadPoolExecutor.java:293)
 at java.util.concurrent.ThreadPoolExecutor.runWorker(ThreadPoolExecutor.java:1142)
 at java.util.concurrent.ThreadPoolExecutor$Worker.run(ThreadPoolExecutor.java:617)
 at java.lang.Thread.run(Thread.java:745)
Here a screenshot of my JDBC interpreter settings:
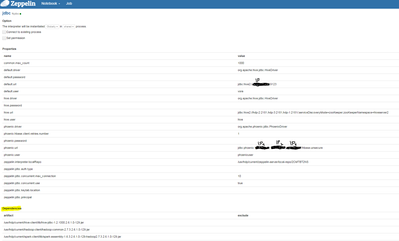
Also other selects (without the com.sap.spark.engines part) don't work for me, and I get the same exception!
Could it be a problem caused by incompatibilities of Hadoop tools? Or what could be the reason for the error message above? Is a dependency missing (if yes which)?
Thank you for each advice!
Created 07-07-2017 08:34 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Ok, easy solution here: I took the hive-jdbc-<version>.jar file as dependency, but I have to take hive-jdbc-<version>-standalone.jar, so changing
/usr/hdp/current/hive-client/lib/hive-jdbc-1.2.1000.2.6.1.0-129.jar
into
/usr/hdp/2.6.1.0-129/hive2/jdbc/hive-jdbc-2.1.0.2.6.1.0-129-standalone.jar
did it for me!
You can find the hive-jdbc-standalone.jar with
find / -name "hive-jdbc*standalone.jar


