
Our Community is getting an upgrade! To get everything ready for the relaunch, we’ll be placing the site in read-only mode starting September 21st.
We really appreciate your understanding while we get things set up behind the scenes. Catch up on all the exciting details about the move here.
Need help or have questions? Drop us a line at [email protected]

Archives of Support Questions (Read Only)
- Cloudera Community
- Board Archive
- Archives of Support Questions (Read Only)
- Spark 2 interpreter runs only 3 containers
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
Spark 2 interpreter runs only 3 containers
- Labels:
-
Apache Spark
-
Apache Zeppelin


Created on 07-17-2017 11:49 AM - edited 08-18-2019 01:59 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Hi. I have a problem with Spark 2 interpreter in Zeppelin. I configured interpreter like this:
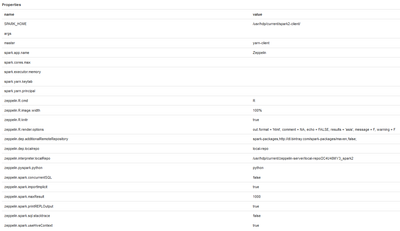
When I run query like this:
%spark2.sql
select var1, count(*) as counter
from database.table_1
group by var1
order by counter desc
Spark job runs only 3 containers and job takes 13 minutes.
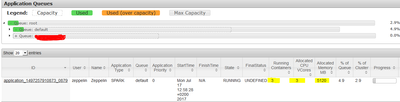
Does anyone know why Spark interpreter takes only 4.9 % of queue? How I should configure the interpreter to increase this factor?

Created 07-17-2017 09:24 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
@Mateusz Grabowski, You should enable Dynamic Resource Allocation in Spark to automatically increase/decrease executors of an app as per resource availability.
You can choose to enable DRA in either Spark or Zeppelin .
1) Enable DRA for Spark2 as below.
2) Enable DRA via Livy Interpreter. Run all spark notebooks via livy interpreters.
https://zeppelin.apache.org/docs/0.6.1/interpreter/livy.html
Created 07-18-2017 10:01 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
It works! Thank you 🙂


