
Our Community is getting an upgrade! To get everything ready for the relaunch, we’ll be placing the site in read-only mode starting September 21st.
We really appreciate your understanding while we get things set up behind the scenes. Catch up on all the exciting details about the move here.
Need help or have questions? Drop us a line at [email protected]

Archives of Support Questions (Read Only)
- Cloudera Community
- Board Archive
- Archives of Support Questions (Read Only)
- Re: can you test 2 queries and check
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
Why can't I run more than 1 query in parallel in Hive?
- Labels:
-
Apache Hive

Created on 07-03-2017 02:27 PM - edited 08-17-2019 05:11 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
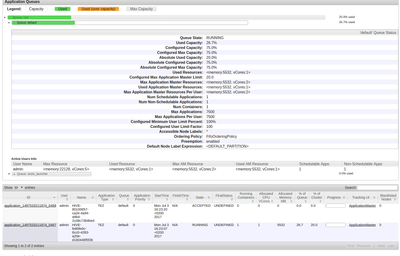
I have a small one node hdp2.6 cluster (8 CPUs, 32GB ram), and I cannot run more than 1 query at a time, although I was pretty sure that I configures the relevant settings to allow more than one container.
The relevant configs are:
yarn-site/yarn.nodemanager.resource.memory-mb = 27660
yarn-site/yarn.scheduler.minimum-allocation-mb = 5532
yarn-site/yarn.scheduler.maximum-allocation-mb = 27660
mapred-site/mapreduce.map.memory.mb = 5532
mapred-site/mapreduce.reduce.memory.mb = 11064
mapred-site/mapreduce.map.java.opts = -Xmx4425m
mapred-site/mapreduce.reduce.java.opts =  -Xmx8851m
mapred-site/yarn.app.mapreduce.am.resource.mb = 11059
mapred-site/yarn.app.mapreduce.am.command-opts = -Xmx8851m -Dhdp.version=${hdp.version}

hive-site/hive.execution.engine = tez
hive-site/hive.tez.container.size = 5532
hive-site/hive.auto.convert.join.noconditionaltask.size = 1546859315
tez-site/tez.runtime.unordered.output.buffer.size-mb = 414
tez-interactive-site/tez.am.resource.memory.mb = 5532
tez-site/tez.am.resource.memory.mb = 5532
tez-site/tez.task.resource.memory.mb = 5532
tez-site/tez.runtime.io.sort.mb = 1351
hive-site/hive.tez.java.opts = -server -Xmx4425m -Djava.net.preferIPv4Stack=true -XX:NewRatio=8 -XX:+UseNUMA -XX:+UseParallelGC -XX:+PrintGCDetails -verbose:gc -XX:+PrintGCTimeStamps

capacity-scheduler/yarn.scheduler.capacity.resource-calculator = org.apache.hadoop.yarn.util.resource.DominantResourceCalculatororg.apache.hadoop.yarn.util.resource.DominantResourceCalculator
yarn-site/yarn.nodemanager.resource.cpu-vcores = 6
yarn-site/yarn.scheduler.maximum-allocation-vcores = 6

mapred-site/mapreduce.map.output.compress = true
hive-site/hive.exec.compress.intermediate = true
hive-site/hive.exec.compress.output = true


hive-interactive-env/enable_hive_interactive = false
Which if I understand it well, gives 5GB per container.
If I run a hive query, it will use 5GB, 1 core, leaving about 15GB and 5 cores for the rest. I do not understand why the next query cannot start at the same time.
Any help would be much welcome.


Created 07-09-2020 04:21 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
In Mapreduce the Reducer output would wait after all ten Mapper is finished. We recommend to use Tez.
Created 07-09-2020 07:50 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
It is decided by the optmiser,the planning .We can not do much on this.

- « Previous
- Next »

