
Our Community is getting an upgrade! To get everything ready for the relaunch, we’ll be placing the site in read-only mode starting September 21st.
We really appreciate your understanding while we get things set up behind the scenes. Catch up on all the exciting details about the move here.
Need help or have questions? Drop us a line at [email protected]

Archives of Support Questions (Read Only)
- Cloudera Community
- Board Archive
- Archives of Support Questions (Read Only)
- Re: pig script status running but always remain at...
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
pig script status running but always remain at zero percent ?
- Labels:
-
Apache Pig

Created on 02-08-2016 10:06 AM - edited 08-19-2019 02:32 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
s i am installed hadoop using hdp on ec2 amazon cloud.
architecture is :
1 node on which ambari server is installed
2 master nodes
3 data nodes
So i have total 6 machines in the cluster.
Now when i open the pig view in ambari and run my hello world tutorial script
a = LOAD 'geolocation' using org.apache.hive.hcatalog.pig.HCatLoader();
b = filter a by event != 'normal';
c = foreach b generate driverid, event, (int) '1' as occurance;
d = group c by driverid;
e = foreach d generate group as driverid, SUM(c.occurance) as t_occ;
g = LOAD 'drivermileage' using org.apache.hive.hcatalog.pig.HCatLoader();
h = join e by driverid, g by driverid; final_data = foreach h generate $0 as driverid, $1 as events, $3 as totmiles, (float) $3/$1 as riskfactor;
store final_data into 'riskfactor' using org.apache.hive.hcatalog.pig.HCatStorer();
Its status changes to accepted and then changes to running but always remain running for hours
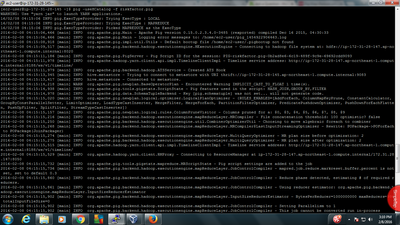
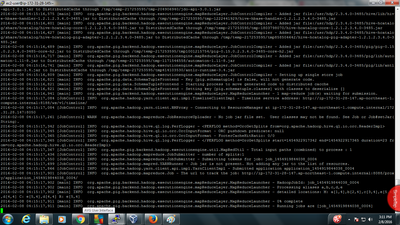
Then i try to run this script in grunt shell . Here i create new file with the name "vi riskfactor.pig" and run it using the command " pig -useHCatalog -f riskfactor.pig". This job is submitted but never moves from zero percent . Here i attach the screen shots of my console.
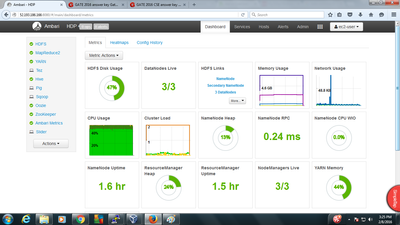
here i upload the screenshot of installed components in my cluster
Created 02-11-2016 05:04 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
thanks @Neeraj Sabharwal, @Artem Ervits, @Geoffrey Shelton Okot and @Benjamin Leonhardi for your valuable replies my problem is solved with the help of your answers. Thank You 🙂 🙂
Created 12-06-2017 01:25 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
@Artem Ervits @grajagopal @Geoffrey Shelton Okot
Hello,
I'm facing the same issue but by following the tutorial mentioned in:
https://hortonworks.com/tutorial/hadoop-tutorial-getting-started-with-hdp/section/4/.
Once i execute my pig script, it is stuck in running status as mentioned in status.png.

From RM UI, my application is also stuck in Running status as shown in rm-application.png and i attached the launched job in MapReduce in mr-job.png.


From pig view log, i got hive-log.png.

How can i resolve my issue? I'll be really grateful if you could help me.

- « Previous
- Next »

