
Our Community is getting an upgrade! To get everything ready for the relaunch, we’ll be placing the site in read-only mode starting September 21st.
We really appreciate your understanding while we get things set up behind the scenes. Catch up on all the exciting details about the move here.
Need help or have questions? Drop us a line at [email protected]

Archives of Support Questions (Read Only)
- Cloudera Community
- Board Archive
- Archives of Support Questions (Read Only)
- this version of libhadoop was built without snappy...
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
this version of libhadoop was built without snappy support.
- Labels:
-
Apache Hadoop
-
HDFS


Created on 02-23-2016 02:37 PM - edited 09-16-2022 03:05 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Hi,
I hope it's the right place to ask the following question 🙂
I try to put in hdfs a file with snappy compression. I write a Java code for that and when I try to run it on my cluster I got the following exception:
Exception in thread "main" java.lang.RuntimeException: native snappy library not available: this version of libhadoop was built without snappy support.
at org.apache.hadoop.io.compress.SnappyCodec.checkNativeCodeLoaded(SnappyCodec.java:65)
at org.apache.hadoop.io.compress.SnappyCodec.getCompressorType(SnappyCodec.java:134)
at org.apache.hadoop.io.compress.CodecPool.getCompressor(CodecPool.java:150)
at org.apache.hadoop.io.compress.CompressionCodec$Util.createOutputStreamWithCodecPool(CompressionCodec.java:131)
at org.apache.hadoop.io.compress.SnappyCodec.createOutputStream(SnappyCodec.java:99)
Apparently the snappy library is not available... I check on the os with the following cmd "rpm -qa | less | grep snappy" and snappy and snappy-devel is present.
In the configuration of hdfs (core-site.xml) org.apache.hadoop.io.compress.SnappyCodec is present in the field io.compression.codecs.
Does anyone has a idea why it's not working?
Thanks in advance
Created on 03-17-2016 08:39 AM - edited 08-18-2019 05:34 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
The problem is solve by making the following change in the spark config:
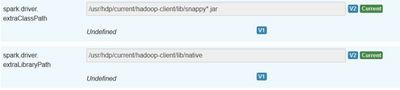
Thanks for the help guys!

Created 02-23-2016 02:37 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
please post your code.
Created 02-23-2016 02:44 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
here's the piece of code:
Path outFile = new Path(destPathFolder.toString() + "/" + listFolder[i].getName() + "_" + listFiles[b].getName() + ".txt");
FSDataOutputStream fin = dfs.create(outFile);
Configuration conf = new Configuration();
conf.setBoolean("mapreduce.map.output.compress", true);
conf.set("mapreduce.map.output.compress.codec", "org.apache.hadoop.io.compress.SnappyCodec");
CompressionCodecFactory codecFactory = new CompressionCodecFactory(conf);
CompressionCodec codec = codecFactory.getCodecByName("SnappyCodec");
CompressionOutputStream compressedOutput = codec.createOutputStream(fin);
FileReader input = new FileReader(listFiles[b]);
BufferedReader bufRead = new BufferedReader(input);
String myLine = null;
while ((myLine = bufRead.readLine()) != null) {
if (!myLine.isEmpty()) {
compressedOutput.write(myLine.getBytes());
compressedOutput.write('\n'); } }
compressedOutput.flush();
compressedOutput.close();
Created 02-23-2016 03:13 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
I don't remember setting CompressionCodecFactory explicitly. Just let configuration do its magic so remove the following
CompressionCodecFactory codecFactory = new CompressionCodecFactory(conf);
CompressionCodec codec = codecFactory.getCodecByName("SnappyCodec");
CompressionOutputStream compressedOutput = codec.createOutputStream(fin);
and
compressedOutput.write(myLine.getBytes());
compressedOutput.write('\n'); } }
compressedOutput.flush();
compressedOutput.close();
Created 02-23-2016 03:22 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Hi Artem,
Thanks for the fast reply. I don't really understand how it will work without the
compressedOutput.write(myLine.getBytes());
compressedOutput.write('\n'); } }
compressedOutput.flush();
compressedOutput.close();
How it will write to hdfs? Also if I remove the first part, when the configuration will be use?
Can you give me an example because, I don't see how it works without the part that you specify :s
Thanks in advance
Created 02-23-2016 03:30 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
it's been awhile, here's an example from definitive guide book
public class StreamCompressor {

  public static void main(String[] args) throws Exception {
    String codecClassname = args[0];
    Class<?> codecClass = Class.forName(codecClassname);
    Configuration conf = new Configuration();
    CompressionCodec codec = (CompressionCodec)
      ReflectionUtils.newInstance(codecClass, conf);

    CompressionOutputStream out = codec.createOutputStream(System.out);
    IOUtils.copyBytes(System.in, out, 4096, false);
    out.finish();
  }
}
Created 02-24-2016 08:52 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
@Artem Ervits I just made the test with the example of the definitve guide and I still have exactly the same error:
Exception in thread "main" java.lang.RuntimeException: native snappy library not available: this version of libhadoop was built without snappy support.
Any idea?
Created 02-24-2016 11:56 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Please go through these steps and confirm everything is in place https://docs.hortonworks.com/HDPDocuments/HDP2/HDP-2.3.0/bk_installing_manually_book/content/install... and just double-check snappy versions according to this doc http://docs.hortonworks.com/HDPDocuments/Ambari-2.1.1.0/bk_releasenotes_ambari_2.1.1.0/content/ambar...
Created 03-05-2016 03:03 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Can you post your maven pom?
Created 02-23-2016 04:06 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
@Michel Sumbul See this thread. The same solution was used in the past by a client.


