


COD - CDE via Phoenix
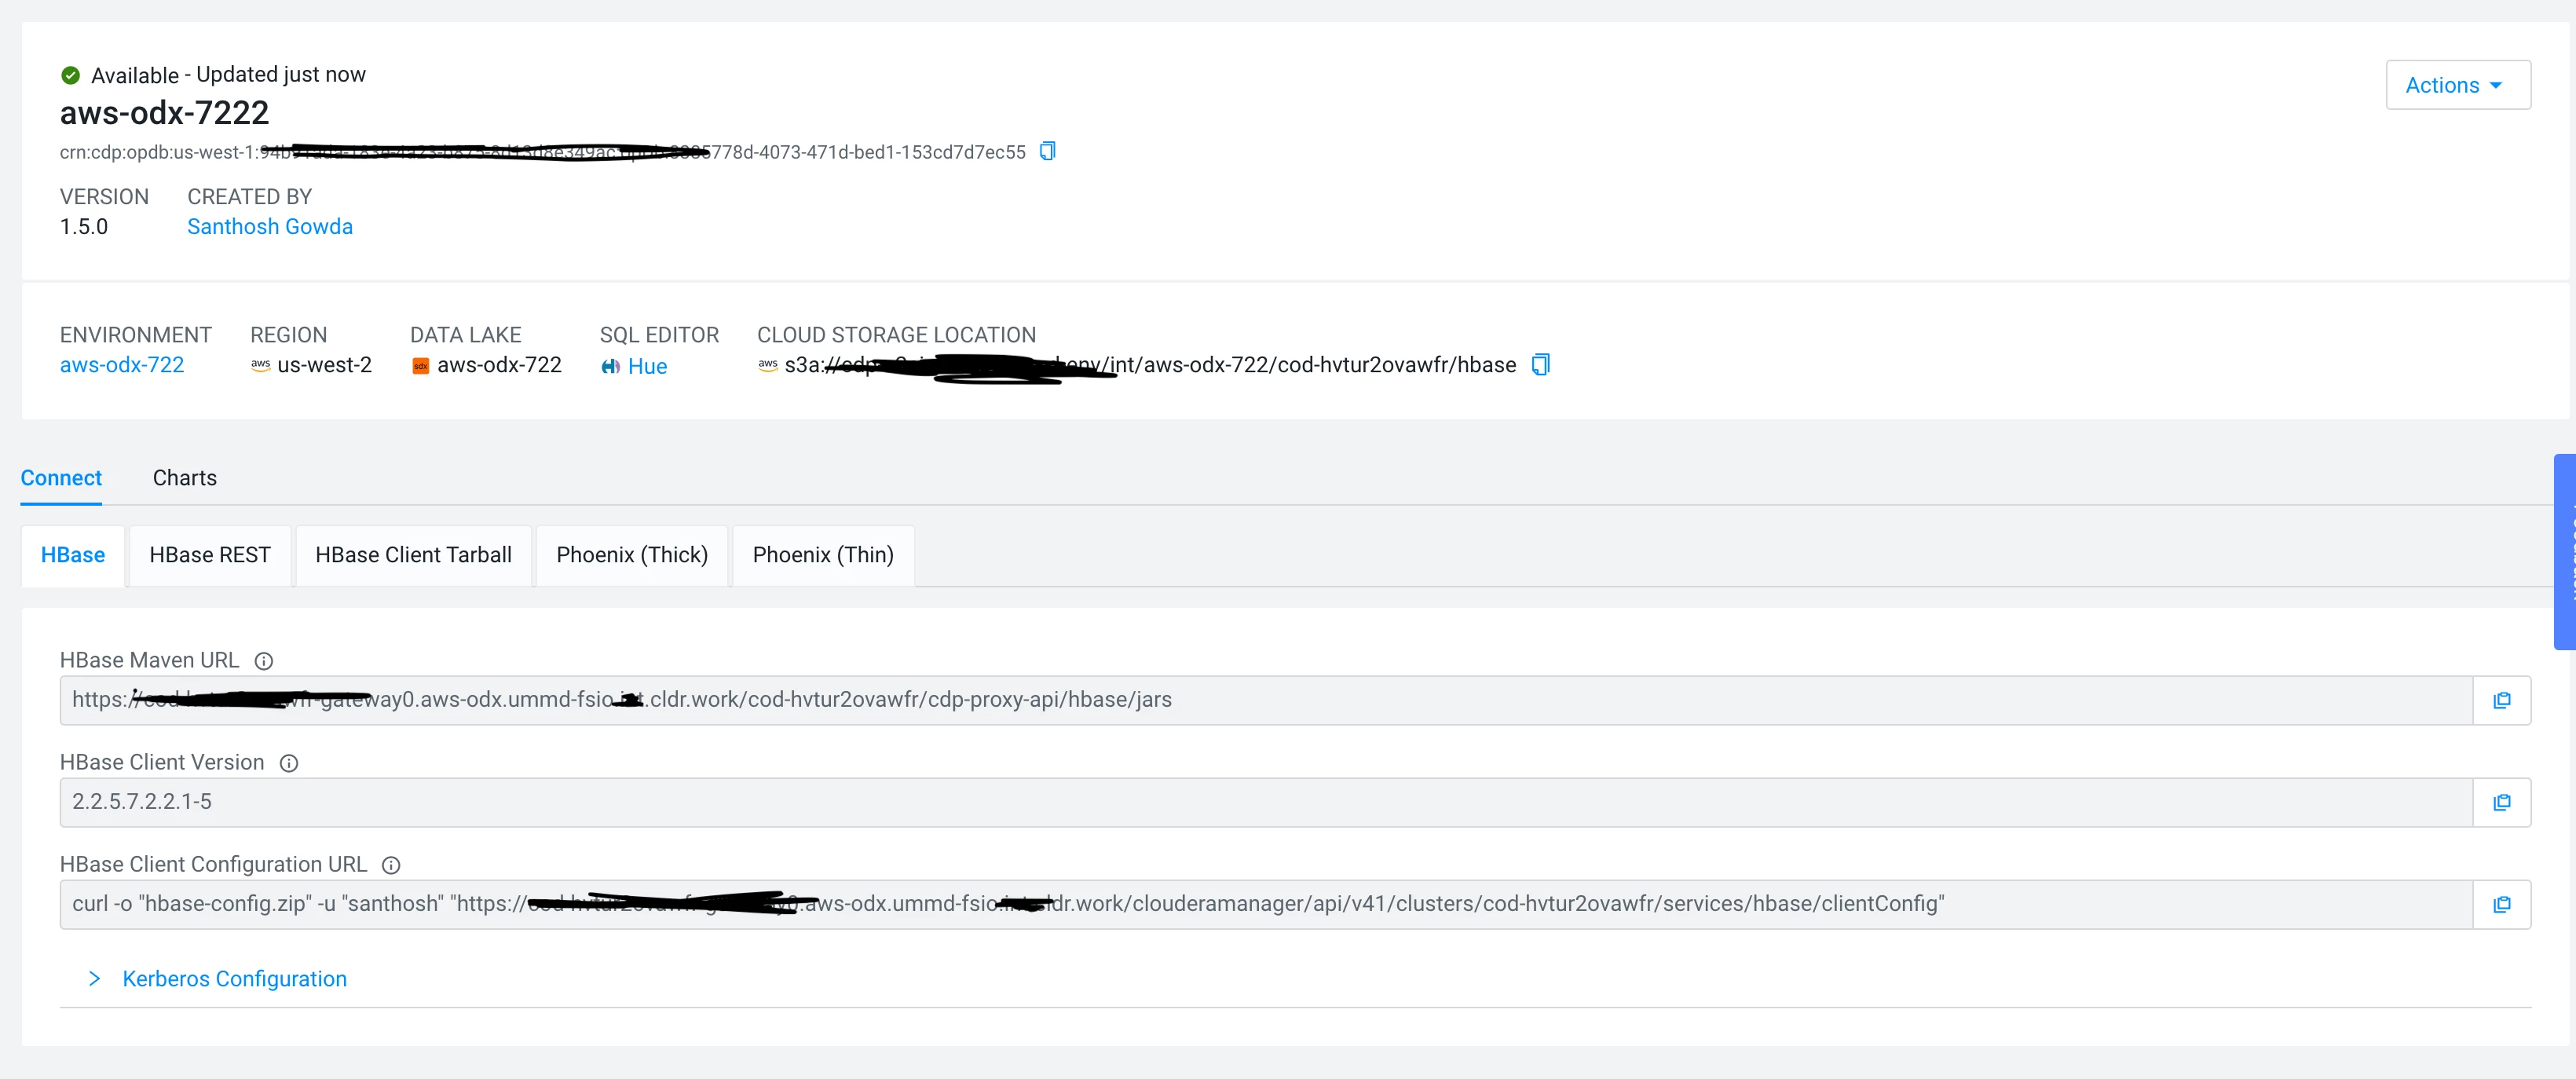
curl -o "hbase-config.zip" -u "santhosh" "https://XXXXXX.cldr.work/clouderamanager/api/v41/clusters/cod-hvtur2ovawfr/services/hbase/clientConfig"
- Make sure to provide the "workload" password for above curl call.
- Explore the downloaded zip file to obtain the hbase-site.xml file.
- Note down the Phoenix JDBC url from the Phoenix (Thick) tab.
Create table in COD
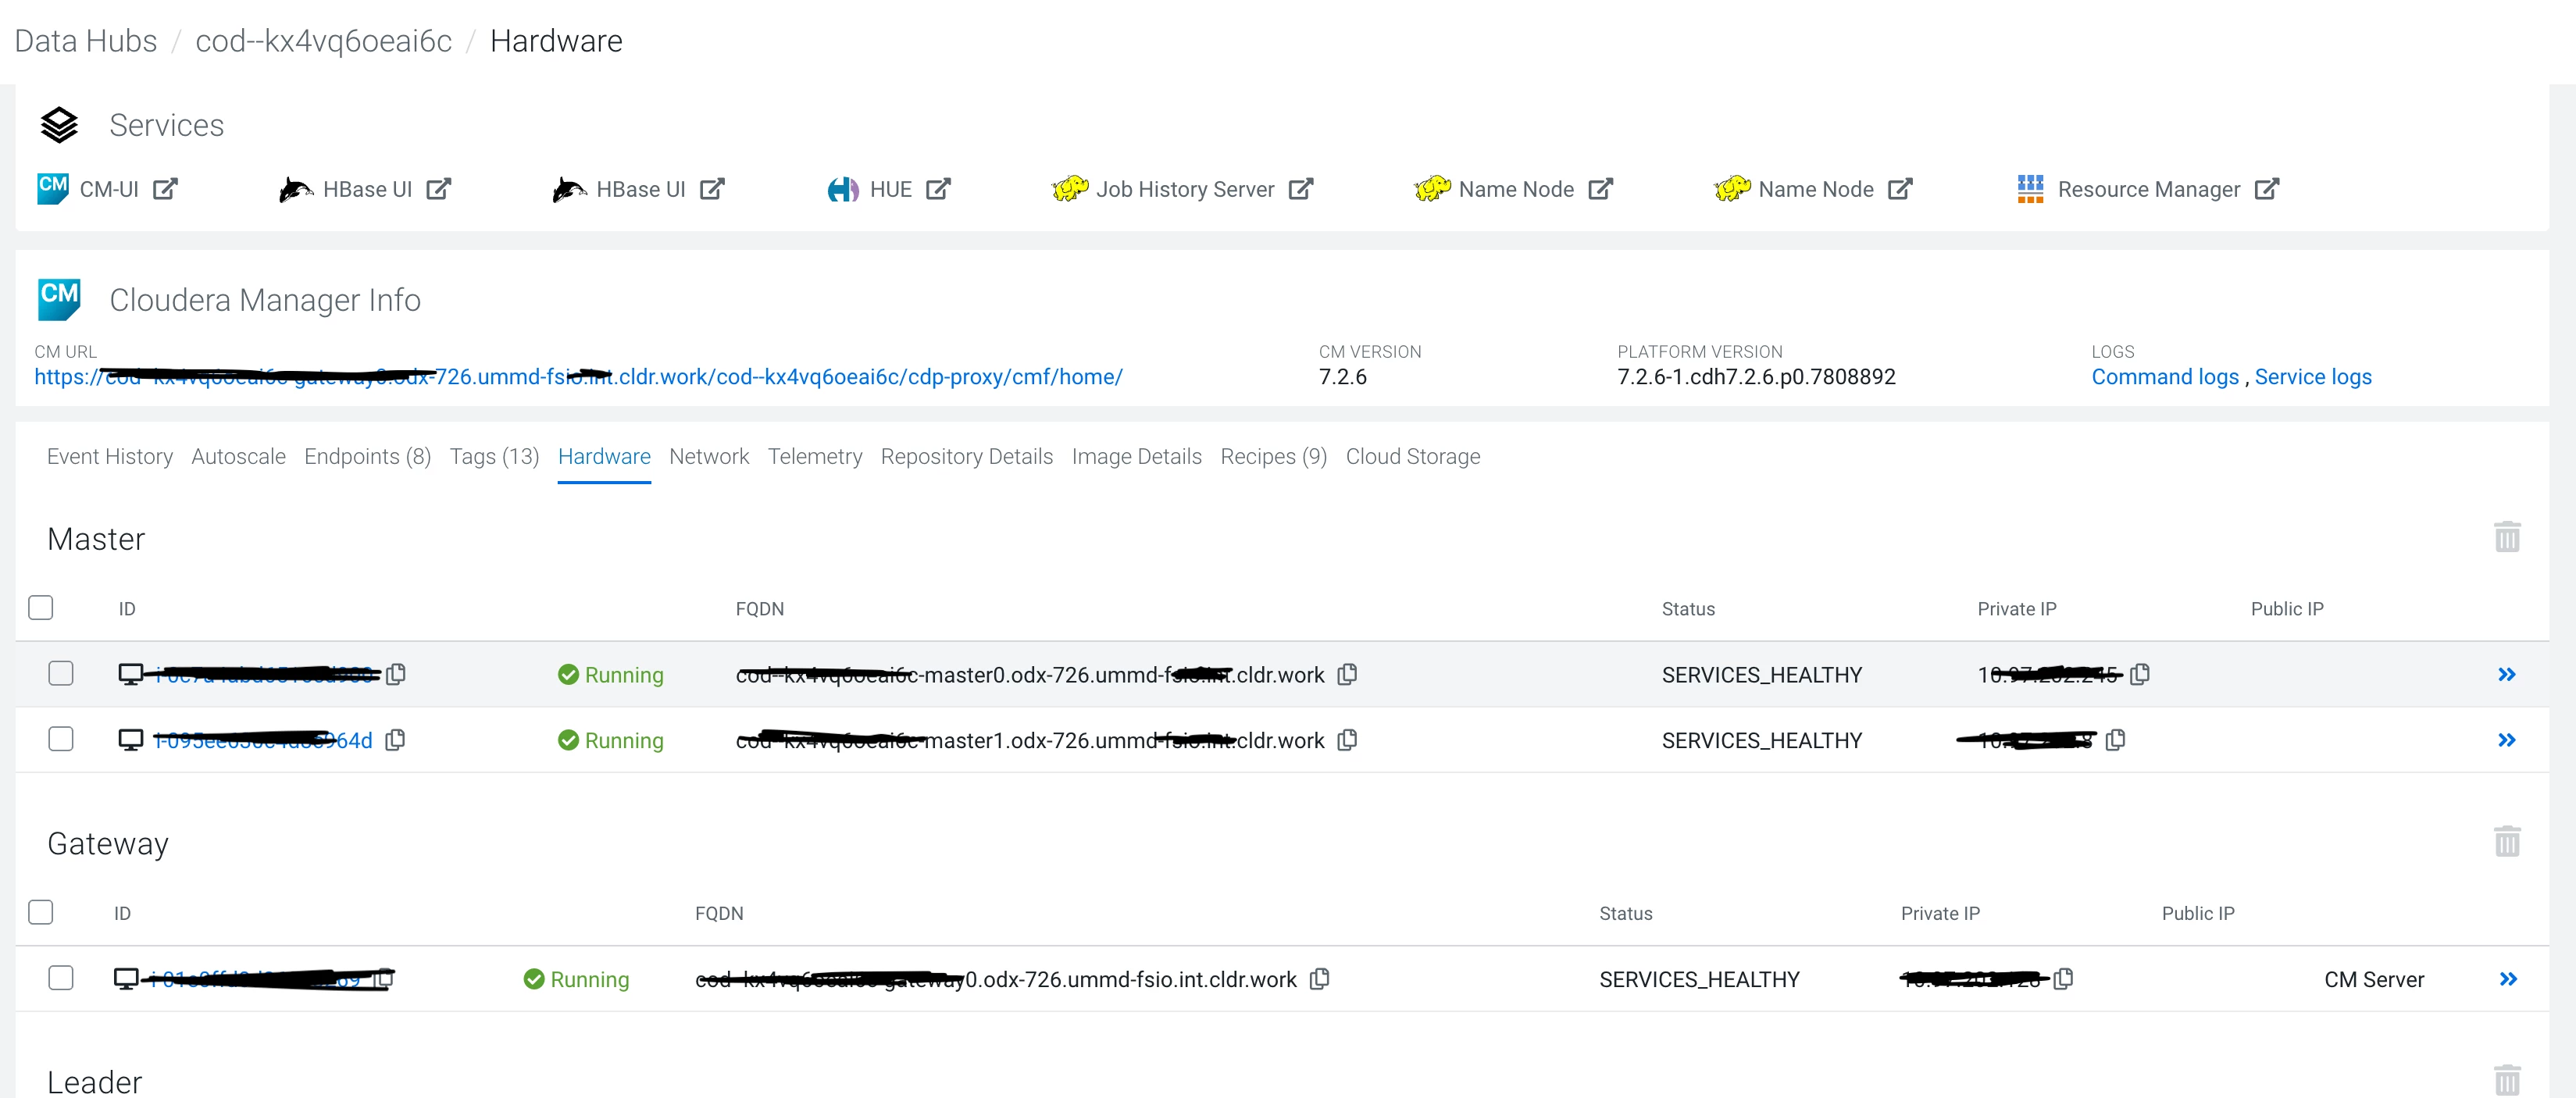
We would need to create table in COD using Phoenix for this demo. In order to do the same, please login into the gateway node of the COD cluster and run phoenix-sqlline command to create table as follows.
CREATE TABLE OUTPUT_TEST_TABLE (id BIGINT NOT NULL PRIMARY KEY, col1 VARCHAR, col2 INTEGER);
The node details can be obtained from the datahub hardware tab from control plane UI. Following is the screenshot for the same.
Build phoenix-spark project
Build the following Spark phoenix demo maven project.
https://github.com/bgsanthosh/spark-hbase/tree/master/spark-hbase
Make sure to bump the phoenix-spark and hbase-client version as per the Cloudera runtime version.
Run the following command from the project home.
mvn clean compile package
CDE
Configure and Run Job
- Configure CDE CLI to point to the virtual cluster created in the above step. For more details, see Configuring the CLI client.
- Create resource using the following command.
cde resource create --name odx-spark-resource - Upload hbase-site.xml
cde resource upload --name odx-spark-resource --local-path hbase-site.xml --resource-path conf/hbase-site.xml - Upload the demo app jar that was built earlier.
cde resource upload --name odx-spark-resource --local-path ./spark-hbase/target/spark-hbase-1.0-SNAPSHOT.jar --resource-path spark-hbase-1.0-SNAPSHOT.jar - Create the CDE job using the following json and import command.
{
"mounts": [
{
"resourceName": "odx-spark-resource"
}
],
"name": "odx-read-write",
"spark": {
"className": "org.cloudera.e2e.spark.PhoenixReadWrite",
"conf": {
"spark.executor.extraClassPath": "/app/mount/conf",
"spark.driver.extraClassPath": "/app/mount/conf"
},
"args": [ "{{ phoenix_jdbc_url }}"],
"driverCores": 1,
"driverMemory": "1g",
"executorCores": 1,
"executorMemory": "1g",
"file": "spark-hbase-1.0-SNAPSHOT.jar",
"pyFiles": [],
"files": ["conf/hbase-site.xml"],
"numExecutors": 4
}
}cde job import --file odx-readwrite-var.json
Next, run the job using the following command:
cde job run --name odx-read-write --variable phoenix_jdbc_url=<phoenix_jdbc_url>
Check in phoenix-sqlline, the following data should be present.
0: jdbc:phoenix:> select * from OUTPUT_TEST_TABLE;
+-----+-------+-------+
| ID | COL1 | COL2 |
+-----+-------+-------+
| 1 | 1 | 1 |
| 2 | 2 | 2 |
| 3 | 3 | 3 |
+-----+-------+-------+

