Data Ingest with Apache Zeppelin + Apache Spark 1.6 + Hive
Create a Hive Table as ORC File through Spark SQL in Zeppelin.
%sql

create table default.logs_orc_table (clientIp STRING, clientIdentity STRING, user STRING, dateTime STRING, request STRING, statusCode INT, bytesSent FLOAT, referer STRING, userAgent STRING) stored as orc
Load data from a DataFrame into this table:
%sql


insert into table default.logs_orc_table select t.* from accessLogsDF t
I can create a table in the Hive View from Ambari.
CREATE TABLE IF NOT EXISTS survey
( firstName STRING, lastName STRING, gender STRING,
  phone STRING, email STRING,
 address STRING,
 city STRING,
 postalcode STRING,
 surveyanswer STRING)
 ROW FORMAT DELIMITED FIELDS TERMINATED BY ','
LINES TERMINATED BY '\n' STORED AS TEXTFILE;
Then really easy to load some data from a CSV file.
LOAD DATA INPATH '/demo/survey1.csv' OVERWRITE INTO TABLE survey;
I can create an ORC based table in Hive from Hive View in Ambari, Spark / Spark SQL or Hive areas in Zeppelin:
create table survey_orc(
firstName  varchar(255),
lastName   varchar(255),
gender     varchar(255),
phone      varchar(255),
email      varchar(255),
address    varchar(255),
city       varchar(255),
postalcode    varchar(255),
surveyanswer  varchar(255)
) stored as orc tblproperties
("orc.compress"="NONE");
I can do the same insert into from Hive.
%hive

insert into table default.survey_orc select t.* from survey t
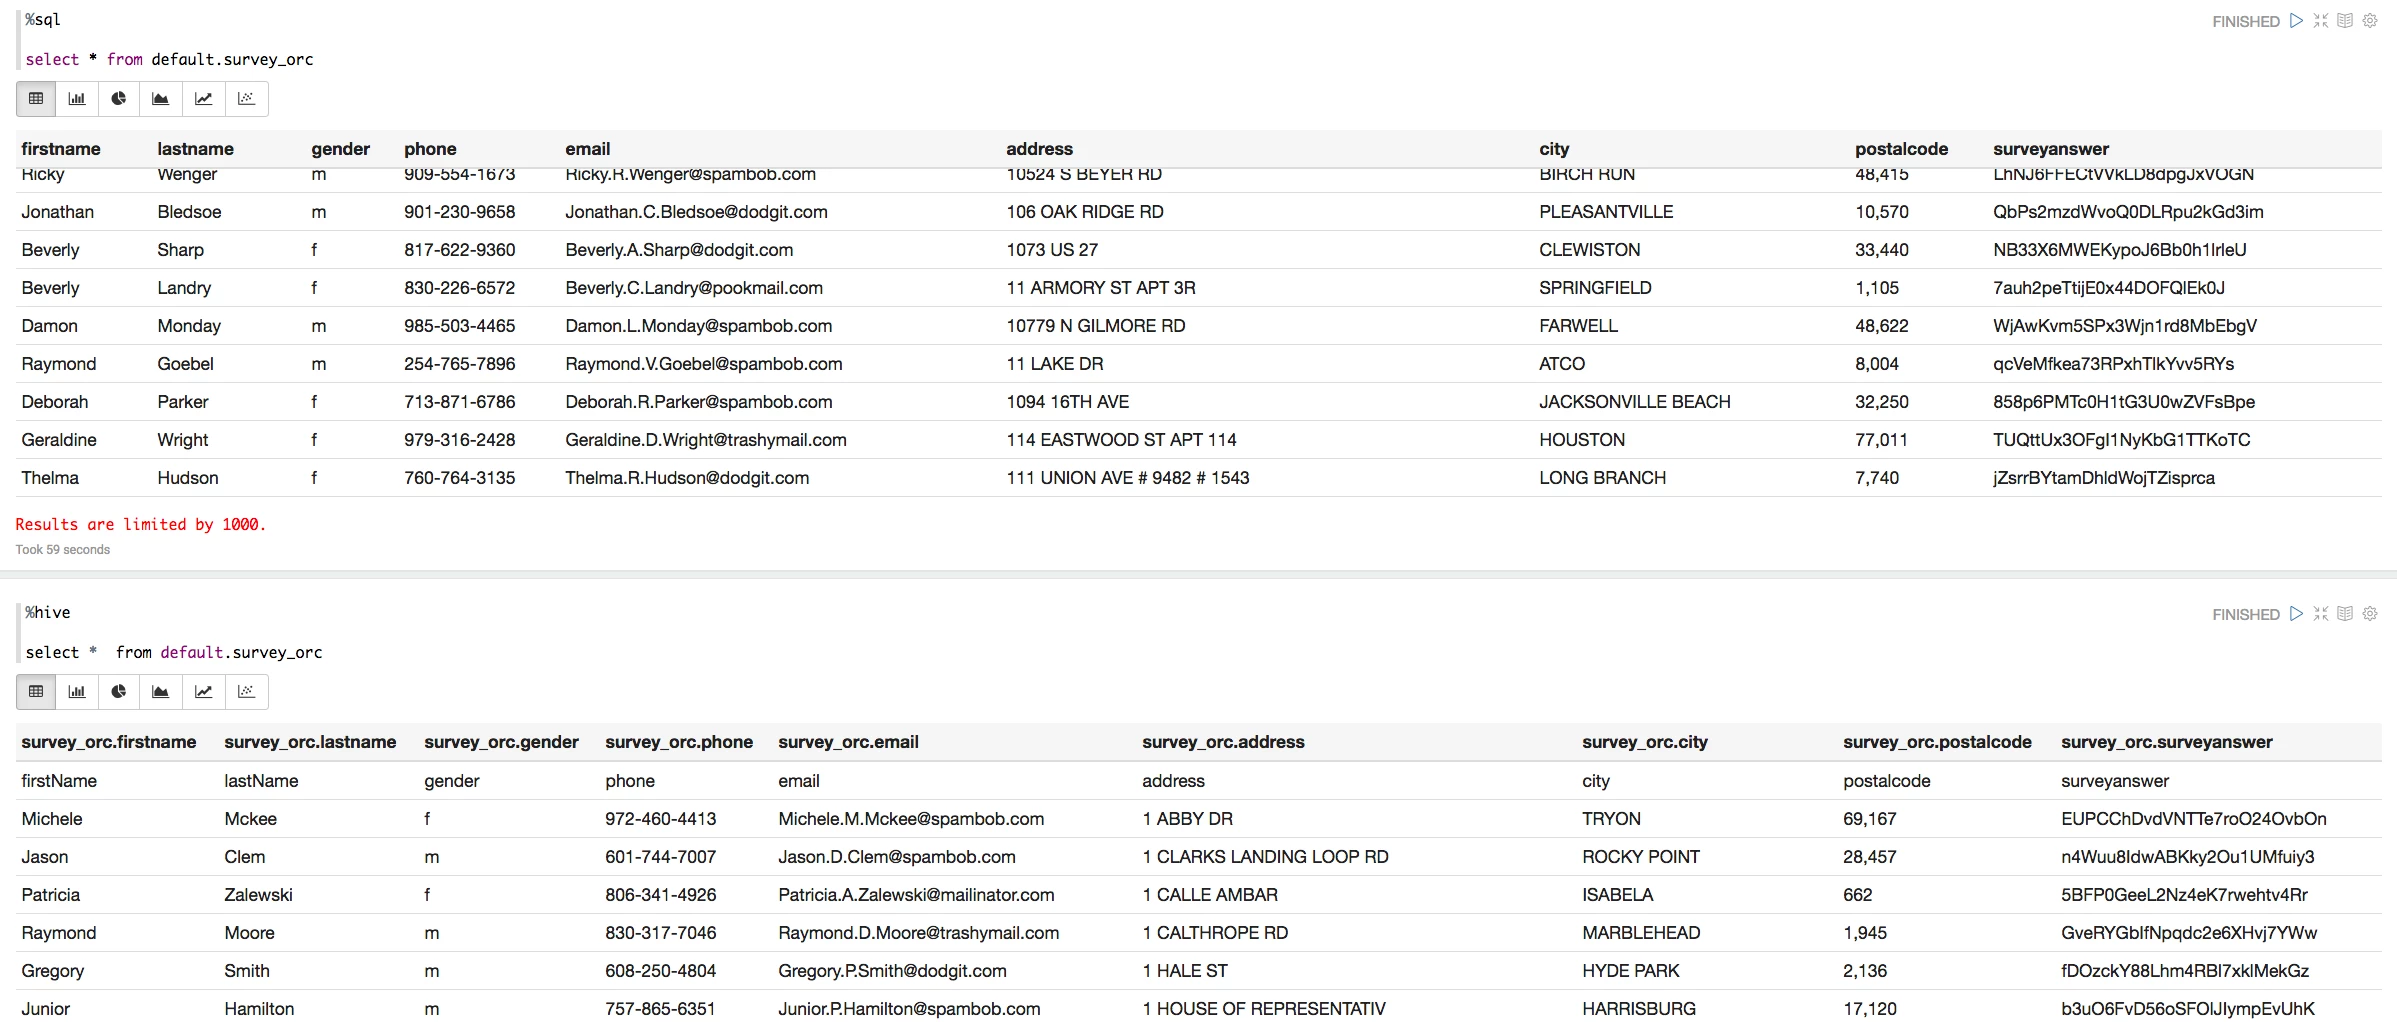
I can query Hive tables from Spark SQL or Hive easily.