Deep dive into YARN Log Aggregation / Deep dive into managing logs
yarn logs -applicationId <application ID> -appOwner <application Owner> > <application ID>_logs.txt
- The LogAggregator threads in a particular node upload the logs of all the containers that were running on that node to the target filesystem as a single aggregated file. Ultimately there will be as many files as nodes that have had running containers belonging to the application. As a matter of fact, an aggregated log file is a set of key-value pairs, where the key is the log meta (file properties like name, size, etc.) and the value is the content of the file. If Kerberos is enabled, the thread must have tokens available to upload the log files with the correct permissions. Check the Path structure section to read more about this.
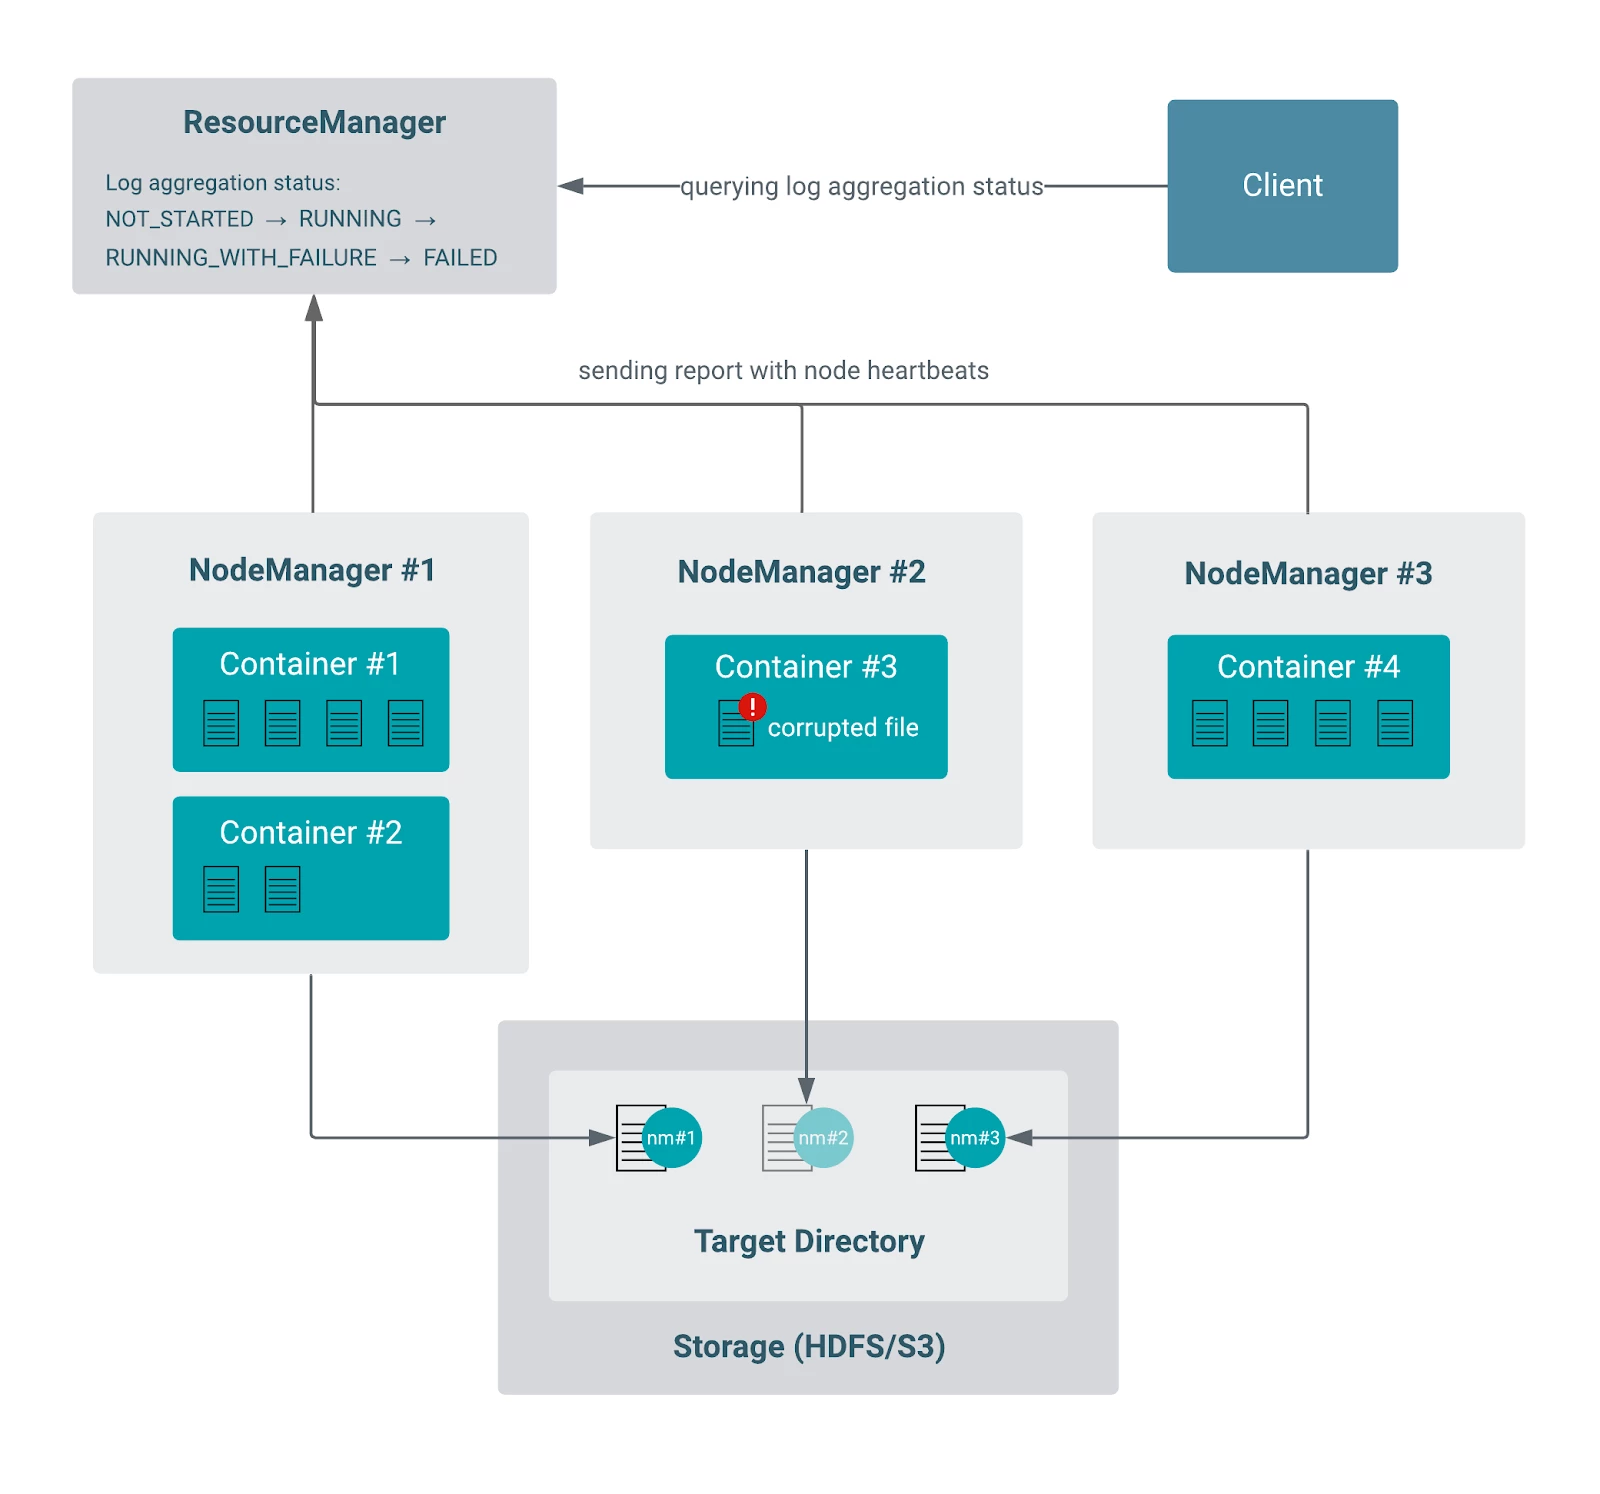
- The application-level log aggregation status is initialized as NOT_STARTED. If everything goes well, the status transitions from NOT_STARTED to RUNNING, and then to SUCCEEDED state. If any of the nodes failed to perform log aggregation, the combined (application’s) log aggregation status will be changed to RUNNING_WITH_FAILURE (despite one failure, other nodes may continue with the aggregation). If all the other nodes are finished, the application level log aggregation state will be FAILED. By default, the Resource Manager keeps 10 of these failure reports in memory, which can contain some more granular information of the failure’s whereabouts. If the node’s log aggregation threads could not finish the upload in time, the Resource Manager will stop waiting for those Node Managers and the final log aggregation status of the application will be TIMED_OUT.
Example of aggregation with partial failure
The following is an example of a log aggregation attempt where one of the nodes has a corrupted file and thus is not able to upload that log.
Default mode
The following steps are performed when the logs of an application are aggregated in default mode:
- Cluster administrators may specify log aggregation properties in yarn-site.xml before YARN is started.
- Upon application submission, the client can override some of the configured parameters and specify some additional parameters like setting the policy and the filename include/exclude patterns (see more details in the Configuration > Submission time configurations section).
- The application is started by the Application Master container coming alive.
- The application terminates when every container, including the Application Master, exits.
- As all containers are finished, a log aggregation cycle is performed as described in the General steps section.
More details
- The cluster administrator can specify the roll-monitoring-interval-seconds to be a non-zero value. This configuration controls how often the Node Manager should wake up to check whether it has to upload the logs (because the application has finished). This may delay the actual aggregation by at most roll-monitoring-interval-seconds.
Rolling mode
The following steps are performed when the logs of an application are aggregated in rolling mode:
- Cluster administrator specifies log aggregation properties in yarn-site.xml before YARN is started.
The administrator must configure the roll-monitoring-interval-seconds property to a non-zero number to use rolling mode. - Upon application submission, the client can override some of these parameters and specify some additional parameters.
The LogAggregationContext of the application must contain a non-empty rolledLogsIncludePattern (and possibly the rolledLogsExcludePattern) field. - YARN performs a special log aggregation cycle in every configured number of seconds (defined with the roll-monitoring-interval-seconds config property) which consist of the following steps:
- Node Managers check every log file that has been produced by the running or finished containers of the application so far.
- If any log file’s name matches against the rolledLogsIncludePattern and does not match against rolledLogsExcludePattern, it is marked for aggregation.
- The selected log files are uploaded as described in the General steps section (steps 1-5)
- Once all containers are finished, a final log aggregation cycle is performed, again as described in the General steps section (steps 1-6).
More details
- Depending on the log aggregation controller, the files may or may not be deleted in every cycle. If a file is deleted, it can be recreated before the next log aggregation cycle starts, the system is able to handle that.
- Depending on the log aggregation controller, the new content can be appended to the end of the previous aggregated logs or created as a new file.
Limitations
- The log aggregation status is not persisted in either the state store or the disk due to performance reasons. See the discussion in YARN-4029. Therefore, if an application is recovered because of Resource Manager restart or failover, the log aggregation status will be NOT_START even for already finished applications.
- The log aggregation configurations should match for all Node Managers, otherwise, some logs will be aggregated to a separate remote log directory that can be confusing. This rule is enforced by Cloudera Manager.
- Rolling Log Aggregation is not supported in CDH, but it is supported in CDP, see the Use Rolling Log Aggregation with long running applications section). Also see the Use cases section on how to circumvent long-running applications that are filling up disks of certain nodes with log files.
- The log files can be huge, but this is handled reliably in YARN.
Path structure
As we have seen in the previous section, one node creates one aggregated log file per application. The concrete path where these logs are stored can be different based on configuration. Due to a recent change in Apache Hadoop 3.3.0 (YARN-6929), there are two path structures for the logs. In this article, we refer to them as legacy and new path structures.
New path structure
The logs are aggregated to the following path:<remote-app-log-dir>/<user>/bucket-<suffix>/<bucket id>/<application id>/<NodeManager id>.
The controller’s and YARN’s global settings
The first half of the path is calculated in the following way:
- YARN selects the file-controller for writing, and retrieves its configured directory (yarn.log-aggregation.<file controller name>.remote-app-log-dir).
If not specified, it checks the global configuration (yarn.nodemanager.remote-app-log-dir), defaulting to the value of: /tmp/logs. - A similar mechanism applies to the suffix, with one difference: if there is no defined configuration for the controller, the suffix will be logs- by default, concatenated with the name of the file controller used for writing, in lowercase.
For example, the TFile default file controller’s target directory will be /tmp/logs/<user>/logs-tfile/.
See more about file controllers and their respective configurations in the Configuration section later.
Bucket directory
In a very large cluster, one could bump into the limitation where there are so many applications that the remote storage could not handle the amount of subdirectories under one single directory (check YARN-6929). For this reason, the applications are put into buckets using their id’s remainder divided by 10000. For example if user “test” starts three applications with id 1,2 and 3 their respective paths will be: /tmp/logs/test/bucket-logs-tfile/0001/app_1/,
/tmp/logs/test/bucket-logs-tfile/0002/app_2/ and
/tmp/logs/test/bucket-logs-tfile/0003/app_3/.
Rolling mode
In rolling mode, depending on the file controller, a new aggregated file can be created. If that happened in each cycle, these files would overwrite each other. Thus, a timestamp is appended to the Node Manager’s ID to distinguish the files written in different cycles. An example of the filename: node-1_8041_1592238362.
Legacy path structure
Before YARN-6929 was committed, there was no directory level between the suffix and the application id. Thus, the path looked like this:
<remote-app-log-dir>/<user>/<suffix>/<application id>/<NodeManager id>. This still holds for every CDH and HDP release, while for CDP releases new application’s logs are aggregated to the new path structure, but previously written application’s logs are still accessible for backward compatibility reasons. When a request comes for an already aggregated application’s logs, the new path structure will be checked, but if the application is not found, the legacy path is also checked. Please note that you can disable the legacy path checking feature.
Permissions
The Node Manager enforces that the remote root log directory exists and it has the correct permission settings. A warning is emitted in the Node Manager logs if the folder does not exist or exists but with incorrect permissions (e.g. 1777).
If created, the directory’s owner and the group will be the same user as the Node Manager’s user, and group. The group is configurable, which is useful in scenarios where the Job History Server (or JHS in short) is running in a different UNIX group than the Node Manager that can prevent aggregated logs from being deleted.
Because directly under the filesystem's root, each user has its own directory, everything under the user’s directory is created with 0770 permissions, so that only the specific user and the hadoop group are allowed to access those directories and files.
Each individual aggregated log file will be created with 0640 permissions - providing rw access to the user and read-only access to the hadoop group. Since the directory has 0770 permission, the members of the hadoop group will be able to delete these files, which is important for the automatic deletion.
Accessing aggregated logs
The recommended way to access the aggregated logs is the way they are written: through the corresponding Java class of the log aggregation controller. Reading the aggregated logs directly from the remote storage is discouraged, as controllers may have written additional binary strings to the log file, making it hardly comprehensible for humans.
Though the actual Java classes can only be accessed through Java-compatible code, there are also multiple endpoints to interact with the controller. Clients can use this built-in functionality of the Resource Manager (through the REST API or the UIs), YARN log CLI, etc. (see the Accessing logs section for more details).
Note that the user’s credentials are used when accessing the logs, so if the user is not the owner of the application or in the hadoop group, they will not be able to access the files.
- The controller takes inputs (like configurations) from multiple places. One is the yarn-site.xml shared with the YARN daemons. Keep in mind that it is crucial to match the daemons’ configurations.
See more in the Configurations section. - The other input is the parameterized ContainerLogsRequest object. This object already contains every data about the whereabouts of the logs: the application id, the id and the address of the node if the container is not yet aggregated, the state of the container if it is running, and many more.
- The ContainerLogsRequest object has to be already parameterized by the caller, adding all necessary information (like the ID of the node to forward, if needed). A common choice is the LogServlet (used through the REST API or the UI) and the Logs CLI, but potentially any Java code is capable of doing that.
Keep in mind that the caller has to be able to provide up-to-date details of the container: for example, the Resource Manager knows exactly where to find a certain container, while the Job History Server does not have this information locally. Therefore the Resource Manager and the Timeline Server are able to provide every detail for assembling a proper request object. - Going further on the line, depending on the status of the application the behavior can be one of the following.
- If FINISHED: the controller reads the remote application directory directly.
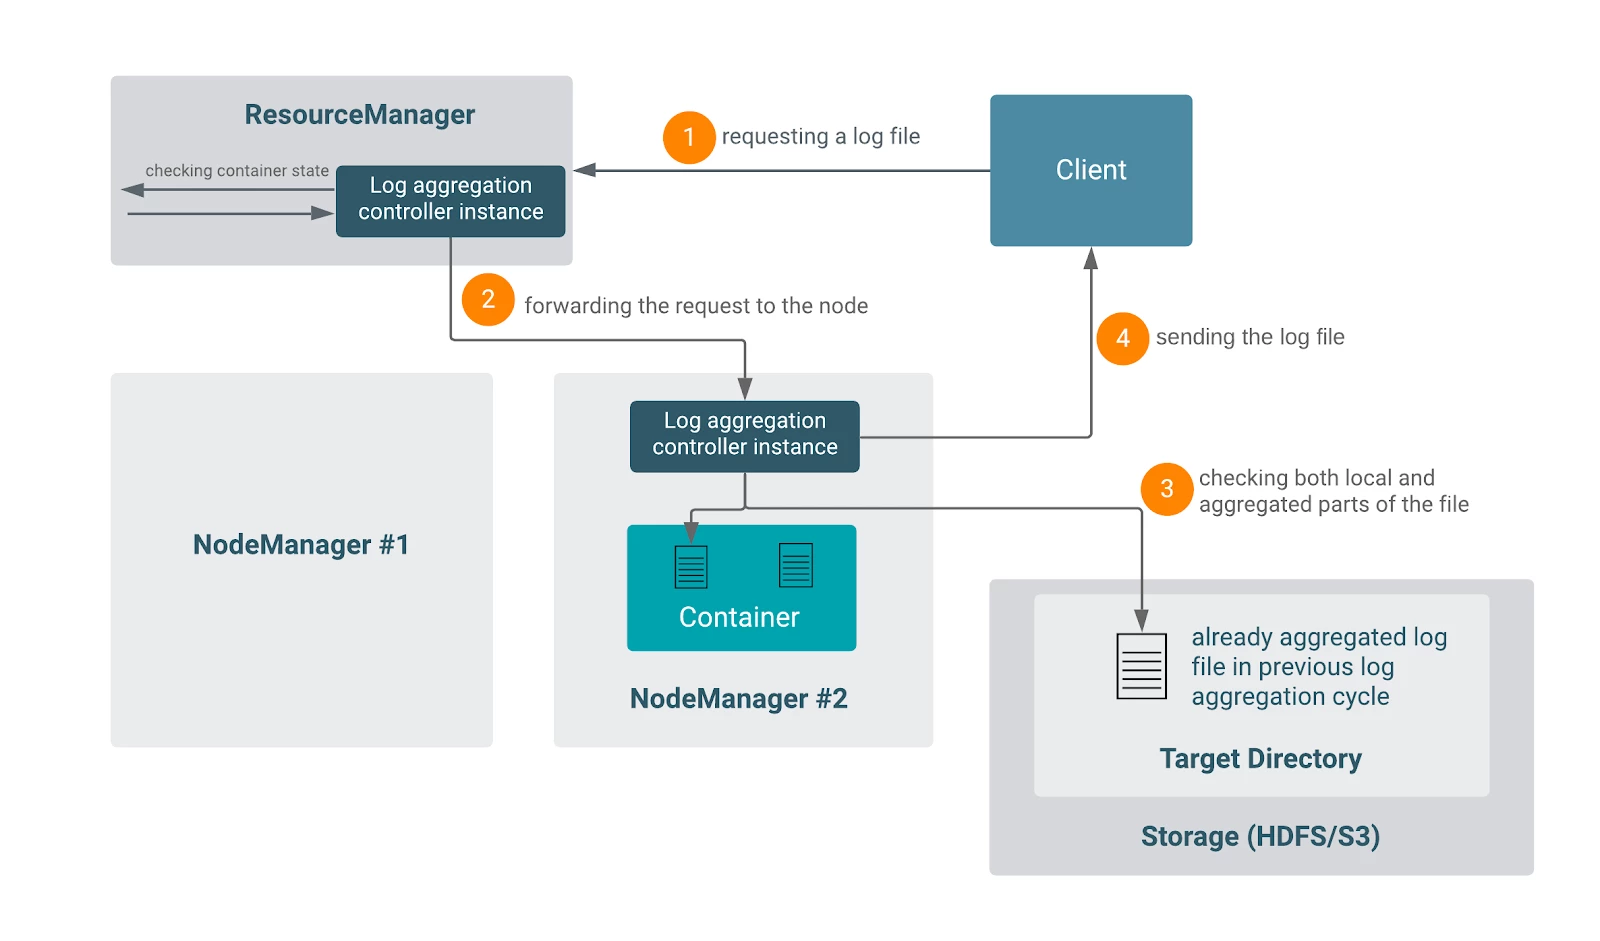
- If RUNNING: the request is redirected to the node where the container is running, and the local Node Manager will handle the request. The Node Manager also communicates with the remote storage to check whether there was any log aggregation cycle containing logs of this particular container (in rolling mode). If yes, concatenates the aggregated and the local parts into the final log file.
Limitations
Currently, it is not supported to access an arbitrary finished container of a running application. It is only possible if the user knows the ID of the container and provides it in the request. There is no general way to query the list of finished containers of a running application - see YARN-10027 about this missing feature.
Deleting aggregated logs
For historical purposes, this operation is the responsibility of the Job History Server, even though it does not fit into the JHS’s other duties.
Its implementation is quite simple: there is a timer thread that wakes up periodically and checks all the aggregated log files. If it finds a file that is older than the configured time interval, the file will be deleted. Both the wake-up period and the retention timeout are configurable. If the latter is a negative number, the log deletion is disabled. Disabling the log deletion is dangerous and requires the administrator to periodically delete the aggregated log files in order to avoid filling up the storage.
Important note: The JobHistory Server must have access to the aggregated log files. Using the default settings it is provided, but in certain cases, it needs some additional configuration to be set (for more information, see the Path structure > Permission section).
Obviously, aggregated log deletion is disabled if log aggregation is disabled itself. If the configuration is changed, it can be reconfigured with the hsadmin -refreshLogRetentionSettings command without restart.
Configurations
In this section, we describe the settings that enable you to use and fine-tune log aggregation and its features for your purpose.
Warning: Changing the log aggregation configuration, especially the path-related ones, is not backward compatible. If the aggregated logs are in a certain location, and the user changes the remote application log directory, already created logs will not be accessible using the new configurations. In these cases, manual intervention is recommended: copying or symlinking the affected directories and files. |
Role-based configurations (Resource Manager, Node Manager, Job History Server)
Below you can find a comprehensive list of different configuration options listed with their default value in the open-source Apache Hadoop categorized by relevance. Note that for certain configurations the defaults are different in Cloudera Manager - see this link. As an example, Cloudera Manager enables log aggregation by default. The descriptions are mostly from the upstream documentation. For the latest default configurations check the upstream documentation.
General
- yarn.log-aggregation-enable: false
- Whether to enable log aggregation.
- yarn.nodemanager.remote-app-log-dir: /tmp/logs
- Where to aggregate logs to. See the Architectural overview section for more details.
- yarn.nodemanager.remote-app-log-dir-suffix: log
- The remote log dir will be created at <remote-app-log-dir>/<user>/<suffix>.
See the Architectural overview section for more details.
- The remote log dir will be created at <remote-app-log-dir>/<user>/<suffix>.
- yarn.nodemanager.log-aggregation.compression-type: none
- T-file compression types used to compress aggregated logs.
- yarn.log-aggregation.retain-seconds: -1
- How long to keep aggregation logs before deleting them. The value of -1 disables this functionality, and deletes the aggregated logs immediately. Be careful, setting this to a too small value will spam the NameNode.
- yarn.log-aggregation.retain-check-interval-seconds: -1
- How long to wait between aggregated log retention checks. If set to 0 or a negative value, the value is computed as 1/10 of the aggregated log retention time. Be careful, setting this too small will spam the NameNode.
Policies
The log aggregation policy is a Java class name that implements ContainerLogAggregationPolicy. At runtime, Node Manager will refer to the policy if a given container's log should be aggregated based on the ContainerType and other runtime states, such as exit code. This is useful when the application only wants to aggregate logs of a subset of containers. The available policies are listed here. Please ensure to specify the canonical name by prefixing with: org.apache.hadoop.yarn.server. nodemanager.containermanager.logaggregation. to the class simple name below.
- AllContainerLogAggregationPolicy: Aggregate all containers. This is the default policy.
- NoneContainerLogAggregationPolicy: Skip aggregation for all containers.
- AMOrFailedContainerLogAggregationPolicy: Aggregate application master or failed containers.
- FailedOrKilledContainerLogAggregationPolicy: Aggregate failed or killed containers.
- FailedContainerLogAggregationPolicy: Aggregate failed containers.
- AMOnlyLogAggregationPolicy: Aggregate application master containers.
- SampleContainerLogAggregationPolicy: Sample logs of successful worker containers, in addition to application master and failed or killed containers.
The log aggregation policy has some optional parameters. These are passed to the policy class during the policy object initialization. Some policy classes might use parameters to adjust their settings. It is up to the policy class to define the scheme of parameters. For example, SampleContainerLogAggregationPolicy supports the format of "SR:0.5,MIN:50", which means a sample rate of 50% beyond the first 50 successful worker containers.
Default config values:
yarn.nodemanager.log-aggregation.policy.class: org.apache.hadoop.yarn.server.
nodemanager.containermanager.logaggregation.AllContainerLogAggregationPolicy
yarn.nodemanager.log-aggregation.policy.parameters:
Controllers
- yarn.log-aggregation.file-formats: TFile
- Specify which log file controllers we will support. The first file controller we add will be used to write the aggregated logs. This comma-separated configuration will work with the configuration: yarn.log-aggregation.file-controller.%s.class which defines the supported file controller's class. By default, the TFile controller would be used. The user could override this configuration by adding more file controllers. To support backward compatibility, make sure that we always add the TFile file controller.
- yarn.log-aggregation.file-controller.%s.class:
- Class that supports file controller’s read and write operations. The file controller is defined by %s.
For example: yarn.log-aggregation.file-controller.TFile.class: org.apache.hadoop.yarn.logaggregation.filecontroller.tfile.LogAggregationTFileController
- Class that supports file controller’s read and write operations. The file controller is defined by %s.
- yarn.log-aggregation.%s.remote-app-log-dir:
- Where to aggregate logs to. It overrides the NodeManager level config yarn.nodemanager.remote-app-log-dir. However, if not set, the NodeManager level config will be in effect.
- yarn.log-aggregation.%s.remote-app-log-dir-suffix:
- The remote log dir will be created at <remote-app-log-dir>/<user>/<suffix>.
It overrides the NodeManager level config yarn.nodemanager.remote-app-log-dir-suffix. However, if not set, the NodeManager level config will be in effect.
- The remote log dir will be created at <remote-app-log-dir>/<user>/<suffix>.
Rolling mode
- yarn.nodemanager.log-aggregation.roll-monitoring-interval-seconds: -1
- Defines how often Node Managers wake up to upload log files. The default value is -1. By default, the logs will be uploaded when the application is finished. By setting this configuration, logs can be uploaded periodically while the application is running. The minimum positive accepted value can be configured by the setting yarn.nodemanager.log-aggregation.roll-monitoring-interval-seconds.min.
- yarn.nodemanager.log-aggregation.num-log-files-per-app: 30
- Defines how many aggregated log files per application per Node Manager we can have in the remote file system. By default, the total number of aggregated log files per application per Node Manager is 30. Takes effect only in rolling mode.
Fine-graining
Fine-graining related properties are only needed in some special use cases:
- yarn.nodemanager.remote-app-log-dir-include-older: true
- Whether the legacy path structure should also be checked when the log aggregation controller searches for aggregated logs in remote storage. See the Architecture > Path structure section for more detail.
- yarn.log-aggregation-status.time-out.ms: 600000 (10 minutes)
- How long for Resource Manager to wait for Node Manager to report its log aggregation status. This configuration will be used in Node Manager as well to decide whether and when to delete the cached log aggregation status.
- yarn.nodemanager.logaggregation.threadpool-size-max: 100
- Thread pool size for LogAggregationService in Node Manager.
- yarn.nodemanager.remote-app-log-dir.groupname:
- The Node Manager will create the remote application log directory with this user group in UNIX systems. In Cloudera Manager, this is set to hadoop to enforce that the Job History Server access to the directory.
- yarn.nodemanager.log.retain-seconds: 10800 (3 hours)
- Time in seconds to retain user logs. Only applicable if log aggregation is disabled
- yarn.resourcemanager.max-log-aggregation-diagnostics-in-memory: 10
- The number of diagnostics/failure messages can be saved in RM for log aggregation. It also defines the number of diagnostics/failure messages that can be shown in log aggregation Web UI.
Debugging
- yarn.nodemanager.delete.debug-delay-sec: 0
- Number of seconds after an application finishes before the Node Manager's DeletionService will delete the application's localized file directory and log directory. To diagnose YARN application problems, set this property's value large enough (for example, to 600 = 10 minutes) to permit inspection of these directories. After changing the value of the property, you must restart the Node Manager in order for it to take effect. The roots of YARN applications' work directories are configurable with the yarn.nodemanager.local-dirsproperty (see below), and the roots of the YARN applications' log directories are configurable with the yarn.nodemanager.log-dirs property (see also below).
- yarn.log-aggregation.debug.filesize: 104857600 (100Mb)
- The log files created under NM Local Directories will be logged if it exceeds the configured bytes. This only takes effect if Log4j level is DEBUG or lower.
- yarn.nodemanager.log-aggregation.roll-monitoring-interval-seconds.min: 3600
- Defines the positive minimum hard limit for yarn.nodemanager.log-aggregation.roll-monitoring-interval-seconds. If this configuration has been set less than its default value (3600), the Node Manager may raise a warning. Modify this only for debugging purposes!
Other log related configurations
- yarn.nodemanager.log-container-debug-info.enabled: false
- Generate additional logs about container launches. Currently, this creates a copy of the launch script and lists the directory contents of the container work dir. When listing directory contents, we follow symlinks to a max-depth of 5 (including symlinks that point to outside the container work dir) which may lead to slowness in launching containers.
- yarn.nodemanager.log.deletion-threads-count: 4
- Number of threads to use in Node Manager log cleanup. Used when log aggregation is disabled.
Submission time configurations
LogAggregationContext represents the options that can be applied to an application.
Policy
In the context object, the user can define a different log aggregation policy than the cluster default (specified by yarn.nodemanager.log-aggregation.policy.class). To overwrite the policy class, define the policyClassName property while its properties can be overwritten by setting the policyParameters property.
Patterns
The user can provide patterns to specify which log files should and should not be aggregated. These patterns are regular expressions.
If a log file’s name matches the includePattern, it will be uploaded when the application finishes. Similarly, if matches excludePattern, it will not be uploaded when the application finishes. If the log file name matches both the include and the exclude pattern, this file will be excluded eventually.
In order for the application to operate in rolling mode, the user should provide a rolledLogsIncludePattern. It works similarly to the includePattern: If a log file matches the defined pattern, it will be aggregated in a rolling fashion. Its counterpart is the rolledLogsExcludePattern: If a log file matches that pattern, it will not be aggregated in a rolling fashion. Also, if the log file name matches both patterns, this file will be excluded eventually.
Storage
Log aggregation is supported in CDH and CDP against HDFS and S3 seamlessly and against ADLS with some limitations.
It should work against Hadoop-supported file systems after version 3.3.0 when the PathCapabilities interface was introduced in HADOOP-15691. This feature enables the automatic configuration of the log aggregation controller, taking the file system properties into account, for example, whether the file system supports the append operation or not.
Controllers
In short, a log aggregation controller is a Java class responsible for handling any log aggregation-related task, including the creation, filtering, and reading of the aggregated logs.
It may have additional logic (like creating meta or index files) and can have different layouts. They may also behave differently in rolling mode.
Storing not just the raw files, but an aggregated file serves multiple purposes:
- There can be thousands of log files - copying just their metadata would be inefficient
- HDFS is better at storing big files
- Can be better compressed together
- The search can be faster in a single aggregated log file, if it is indexed.
By default, log aggregation supports two file controllers: TFile and IndexedFile (the latter is IFile for short). Users can also add their own custom file controller implementing the LogAggregationController Java class. TFile and IFile are commonly referred to as file formats, but the controller is a more descriptive term, as they are not only responsible for the file format itself but also the whole aggregation process. You can also find some more information about them in Cloudera Runtime’s documentation.
The default file controller in YARN is TFile, while Cloudera Runtime uses the IFile format by default because it is more advanced.
Features
Upon deciding which controller to use, the best is to compare the feature set of theirs:
- Whether it creates an index to search in the aggregated log file
- To what extent it is configurable
- Whether it keeps or deletes the aggregated file in rolling mode
- Whether it creates new aggregated files in each rolling cycle
TFile
TFile in HDFS
TFile is not used in YARN log aggregation exclusively. We refer here to the upstream javadoc where some more details can be found about this file format.
Briefly, TFile is a container format of key-value pairs of strings providing the following features:
- Block Compression
- Named metadata blocks
- Sorted or unsorted keys
- Seek by key or by file offset
The memory footprint of a TFile includes some constant overhead of reading or writing a compressed block. Also, each compressed block requires a compression/decompression codec for I/O. It is highly customizable, see the upstream javadoc (serving as documentation) for further details regarding performance optimization for example. Some design rationale behind TFile can be found at HADOOP-3315. TFile has been in Hadoop since 0.20.1 so it is considered reliable and well tested.
TFile in YARN
From log aggregation’s perspective, TFile is used as follows: the key of the TFile is the id of the container and the value is the content, name, and size of the log files belonging to that container. There are some special reserved attributes that the controller puts as keys to the file. The Application ACLs (which users can view and modify the application), the owner of the application, and the layout version of the format are also put into the key-value pairs.
An important difference between the two file controllers is that TFile does not keep the local log files when a log aggregation cycle completes. That means the local logs are deleted, which has an impact on applications that assume the file descriptor of the log is protected during the lifetime of its containers. Long-running applications are vulnerable to this, they should manage their logging with care (see the Use cases section).
When the rolling mode is used, TFile will create a new aggregated file in each log aggregation cycle.
IFile (IndexedFile)
IFile is a newer file controller than TFile. It also uses TFile internally so it provides the same features as TFile and more. In an IndexedFile the files are indexed so it is faster to search in the aggregated log file than in a regular TFile. This causes performance gain when users download individual log files.
IFile uses checksums and temporary files to prevent failures and recover from them. Its buffer sizes and rollover file size are configurable on top of the configuration options of TFile.
Another thing to keep in mind is that IFile does not delete the log files in each rolling cycle because the indexing needs the original file (the upload will only affect the delta though).
Keeping the files can cause major problems in case of a long-running application that produces a constantly growing log file during the lifetime of such applications (see the Use cases section).
Configurations
The input and output buffer size can be configured with the indexedFile.fs.output.buffer.size and indexedFile.fs.input.buffer.size parameters. Another notable parameter is the indexedFile.log.roll-over.max-file-size-gb which controls the roll-over size. A roll-over is executed if an aggregated log file would exceed the value of this parameter in a log aggregation cycle. By default, if rolling mode is used and this limit is not reached, the IFile controller will try to append the new contents to the bottom of the last aggregated log file. Only otherwise it will create a new file for the new deltas. For filesystems that do not support append operation, this is hardcoded to 0, see YARN-9607 for more details.
To fine-tune the connection to the file system, the indexedFile.fs.op.num-retries and the indexedFile.fs.retry-interval-ms configurations properties can be used.
Accessing logs
After the collection and configuration of the log aggregation, we may want to access those logs. There are several ways to do that. Let’s go through each of them.
Warning: The tools described here are sensitive to the log aggregation configuration. If the configuration used by these tools does not match the ones used by the YARN processes, the aggregated logs can become inaccessible. |
Raw files in remote storage
Since the aggregated logs exist on a remote storage, users may access these files directly. This is not recommended, mainly because these files contain multiple concatenated log files, can be compressed in a complex way (could not be unzipped in a conventional way), and may also contain binary/non human-readable parts used by the log aggregation controller.
The recommended way to read these log files is to use one of the dedicated tools that are bundled in Hadoop such as the YARN CLI or the Resource Manager Web UI.
If you want to keep the aggregated logs, but also move it to some archive storage, you can use a useful HDFS tool, the HAR (Hadoop Archive) tool. See Cloudera’s documentation on how to use it.
Logs CLI
There is a command-line interface to access aggregated log files. The tool is highly configurable. It has several features, including:
- Check the list of aggregated files belonging to a container/application
- Obtain metadata of the log files:
- -show_application_log_info
- -show_container_log_info
- size, last modification time
- -list_nodes
- Shows the list of nodes that successfully aggregated logs.
- Show log of specific containers
- Only AM containers with the -am option
- Only specific containers with the -containerId option
- Show specific logs
- -log_files <Log File Name>
- Use "ALL" or "*" to fetch all the log files for the container.
- -log_files_pattern <Log File Pattern>
- This can be any regex, containing wildcards like “.*”
- -log_files <Log File Name>
- Show parts of the log files
- -size for bytes and -size_limit_mb for Megabytes.
- Download logs to location using the -out <directory> option
Check the CDP documentation for the most common use cases illustrated with examples.For CDH 6 and CDP versions here is the help message:
> yarn logs -help

Retrieve logs for YARN applications.

usage: yarn logs -applicationId <application ID> [OPTIONS]

...
Metadata results
Besides the log files themselves, this command-line utility is useful for extracting metadata information about the log aggregation.
The -show_application_log_info option shows a concise list of the containers whose logs are aggregated:
Application State: Completed.

Container: container_1591596957952_0005_01_000002 on node-1.address_port

Container: container_1591596957952_0005_01_000001 on node-2.address_port
While the -show_container_log_info option displays a more descriptive table containing the individual log files (subject to the filtering options shown above):
Container: container_1591596957952_0005_01_000002 on node-1.address_port

==========================================================================

       LogFile LogLength           LastModificationTime LogAggregationType

==========================================================================

 prelaunch.err         0 Mon Jun 08 10:05:54 +0000 2020     AGGREGATED

 prelaunch.out        94 Mon Jun 08 10:05:54 +0000 2020     AGGREGATED

        stderr         0 Mon Jun 08 10:05:54 +0000 2020     AGGREGATED

        stdout         0 Mon Jun 08 10:05:54 +0000 2020     AGGREGATED

Container: container_1591596957952_0005_01_000001 on node-2.address_port

===========================================================================

        LogFile LogLength           LastModificationTime LogAggregationType

===========================================================================

AppMaster.stderr     3499 Mon Jun 08 10:05:54 +0000 2020     AGGREGATED

AppMaster.stdout        0 Mon Jun 08 10:05:54 +0000 2020     AGGREGATED

   prelaunch.err        0 Mon Jun 08 10:05:54 +0000 2020     AGGREGATED

   prelaunch.out       70 Mon Jun 08 10:05:54 +0000 2020     AGGREGATED
In the above table we can see the LogAggregationType column, the value of which can be either LOCAL indicating local files of running containers on the node or AGGREGATED which is already aggregated and copied to the remote storage.
Limitations
Matching configuration
Note that the command line should use the same configuration that is used by the YARN daemons (Resource Manager, Node Manager). If not the same yarn-site.xml configuration file is provided the tool may not be able to find the location of the aggregated log files.
Older releases
In CDH 5 releases, the feature set of the YARN log CLI was limited. In versions prior to CDH 6.0, the CLI was able to retrieve containers of only finished applications - which was a big limitation.
See details in YARN-5141.
Also, in CDH 5 releases prior to CDH 6.0, the appOwner parameter has to be provided manually, so in order to access aggregated log files of an application, users should know which user the application belongs to.
See details in YARN-4842.
Kerberos and SSL
As logs could be read even while a container is running, the YARN log CLI must provide a way to directly reach nodes. If TLS is enabled, the correct certificates must be set for each node.
Before YARN-9606, one could have run into SSLHandshakeException without the correct settings. The mitigation involved importing the truststore manually on the host on which the YARN log CLI ran.
This patch, however, allows LogsCLI to set up an SSLFactory upon initialization in order to include the necessary certificates.
Resource Manager UI v1 / Job History Server
Accessing logs through the Resource Manager’s old UI is possible, but often not very user-friendly. It actually redirects to the Job History Server’s UI.
For any arbitrary container, use the following URL template to reach the Resource Manager UI v1. Note that you have to provide the containerId parameter twice:
http://JHS-node:<JHS port>/jobhistory/logs//<node>:port/<container id>/<container id>/<user>. Routed in the Job History Server’s web application, it uses a log aggregation controller instance to obtain the log files.
Finished applications
For finished applications, on the Resource Manager UI’s All applications tab, a user should click on the application’s ID which redirects to the Application Overview page. On this page, there’s a link at the bottom (logs) that redirects to the Job History Server’s page which displays the Application Master’s logs. If other container logs are needed, the user has to rewrite the URL with the requested container id.
Running applications
For running applications, the JHS displays direct links for the running containers. (Due to a known limitation currently, it is not possible to provide links for every finished container though.) One can access these links by clicking on the application’s ID on the All applications page, then following the link to the application attempt where the user should find the list of running containers. For these containers, the link displays the page from the Job History Server, but behind the scenes, it redirects the request to the node where the container is currently running.
Resource Manager UI v2
In contrast with the older UI, UI v2 is capable of displaying arbitrary containers for finished applications. By default, it uses the Job History server to obtain application meta information (for the log aggregation file controller’s ContainerLogsRequest). If the UI is not able to connect to the Job History Server, it will attempt to obtain these pieces of data from the Timeline Server. It uses the REST API endpoints described below for both the meta information and to display the logs.
Limitations
Before YARN-10029, users should also have a working Timeline Server, because the UIv2 used the AHS or ATS to obtain application-related data. This was resolved in version 3.3.0 and backported to CDP 7.2.x and later releases.
REST API
Multiple YARN daemons provide REST API endpoints for getting log aggregation-related data. These endpoints had similar implementations before they were unified (see LogServlet improvements in YARN-10025).
Paths start with:
- The Job History Server (/ws/v1/history)
- Node Manager (/ws/v1/node)
- Application History Server (/ws/v1/applicationhistory)
- Application Timeline Server (/ws/v1/applicationlog)
Note that AHS and ATS are not available in CDP yet.
Endpoints
/containers/{containerid}/logs
- Returns data about the logs of a specific container. This output is displayed in table format for the logs CLI.
{
    "containerLogsInfo": {
        "containerLogInfo": [
            {
                "fileName": "prelaunch.err",
                "fileSize": "0",
                "lastModifiedTime": "Mon Jun 15 06:13:18 +0000 2020"
            },
            {
                "fileName": "syslog",
                "fileSize": "49962",
                "lastModifiedTime": "Mon Jun 15 06:16:44 +0000 2020"
            },
            {
                "fileName": "prelaunch.out",
                "fileSize": "70",
                "lastModifiedTime": "Mon Jun 15 06:13:18 +0000 2020"
            },
            {
                "fileName": "stdout",
                "fileSize": "14032",
                "lastModifiedTime": "Mon Jun 15 06:22:56 +0000 2020"
            },
            {
                "fileName": "stderr",
                "fileSize": "708",
                "lastModifiedTime": "Mon Jun 15 06:17:40 +0000 2020"
            }
        ],
        "logAggregationType": "AGGREGATED",
        "containerId": "container_1592201557896_0002_01_000001",
        "nodeId": "node-1:8041"
    }
}
- The Node Manager endpoint only works if the container is currently running on that node.
/containerlogs/{containerid}/{filename}
- Returns the content of the log file
Container: container_1592201557896_0002_01_000001 on node-1:8041
LogAggregationType: AGGREGATED
========================================================
LogType:stderr
LogLastModifiedTime:Mon Jun 15 06:17:40 +0000 2020
LogLength:118
LogContents:
2020-06-15 06:16:44 Running Dag: dag_1592201557896_0002_1
2020-06-15 06:16:50 Completed Dag: dag_1592201557896_0002_1
End of LogType:stderr
***********************************************************************
- JHS, AHS, and ATS will redirect to the NM if the container is still running on that node.
/containers/{containerid}/logs/{filename}
- This is the old path for the previous endpoints, it will redirect to the previous one
/aggregatedlogs
- Returns data about the logs of a specific container. Its additional functionality is to provide query parameter support. For example,. /aggregatedlogs?appattemptid=appattempt_1592201557896_0002_000001 will produce a similar output.
{
    "containerLogsInfo": [
        {
            "containerLogInfo": [
                {
                    "fileName": "prelaunch.err",
                    "fileSize": "0",
                    "lastModifiedTime": "Mon Jun 15 06:13:18 +0000 2020"
                },
                {
                    "fileName": "syslog",
                    "fileSize": "49962",
                    "lastModifiedTime": "Mon Jun 15 06:16:44 +0000 2020"
                },
                {
                    "fileName": "prelaunch.out",
                    "fileSize": "70",
                    "lastModifiedTime": "Mon Jun 15 06:13:18 +0000 2020"
                },
                {
                    "fileName": "stdout",
                    "fileSize": "14032",
                    "lastModifiedTime": "Mon Jun 15 06:22:56 +0000 2020"
                },
                {
                    "fileName": "stderr",
                    "fileSize": "708",
                    "lastModifiedTime": "Mon Jun 15 06:17:40 +0000 2020"
                }
            ],
            "logAggregationType": "AGGREGATED",
            "containerId": "container_1592201557896_0002_01_000001",
            "nodeId": "node-4:8041"
        },
        {
            "containerLogInfo": [
                {
                   "fileName": "prelaunch.err",
                    "fileSize": "0",
                    "lastModifiedTime": "Mon Jun 15 06:16:46 +0000 2020"
                },
                {
                    "fileName": "stdout",
                    "fileSize": "38592",
                    "lastModifiedTime": "Mon Jun 15 06:17:58 +0000 2020"
                },
                {
                    "fileName": "prelaunch.out",
                    "fileSize": "70",
                    "lastModifiedTime": "Mon Jun 15 06:16:46 +0000 2020"
                },
                {
                    "fileName": "stderr",
                    "fileSize": "3008",
                    "lastModifiedTime": "Mon Jun 15 06:17:40 +0000 2020"
                },
                {
                    "fileName": "syslog",
                    "fileSize": "39717",
                    "lastModifiedTime": "Mon Jun 15 06:17:40 +0000 2020"
                },
            ],
            "logAggregationType": "AGGREGATED",
            "containerId": "container_1592201557896_0002_01_000002",
            "nodeId": "node-2:8041"
        }
    ]
}
- It is currently implemented only for the Job History Server.
- Supports filtering application, application attempt, and container id.
Summary
In this community article, you have seen a brief introduction of YARN Logging Aggregation along with a Glossary. In the History section, there are a handful of links to YARN upstream jira references that laid the groundwork of most of the functionality of today’s Log Aggregation.
Also, you could see the most important configuration options for this feature, with some use-cases and a more detailed use-case of how one could use Log Aggregation for Long running applications.
For more details, please see our Cloudera Community Article here.
In the Community Article, you will see details on the Architecture, the difference between the legacy and new path structure, a detailed description of how to access aggregated logs and a more detailed Configuration section with some implementation details as well.