HBase – Query Performance when storing and retrieving 'N' versions
Objective
- -To store multiple row versions in HBase to evaluate the impact on performance when doing reading all versions vs. getting the latest version. To put this differently, would storing multiple versions affect the performance when querying the latest version.
- -Using NiFi to be able to quickly ingest millions or rows into HBase
Warning
- -Do not store more than a few versions in HBase. This can have negative impacts. HBase is NOT designed to store more than a few versions of a cell.
Step 1: Create Sample Workflow using NiFi to ingest data into HBase table
- -Create HBase Table
- Dataset: https://www.citibikenyc.com/system-data
create 'venkataw:nycstations','nycstationfam'
0 row(s) in 1.3070 seconds
hbase(main):014:0> desc 'venkataw:nycstations'
Table venkataw.nycstations is ENABLED
venkataw.nycstations
COLUMN FAMILIES DESCRIPTION
{NAME => 'nycstationfam', BLOOMFILTER => 'ROW', VERSIONS => '1', IN_MEMORY => 'false', KEEP_DELETED_CELLS => 'FALSE', DATA_BLOCK_ENCODING => 'NONE', TTL => 'FOREVER', COMPRESSION => 'NONE', MIN_VERSIONS =>
'0', BLOCKCACHE => 'true', BLOCKSIZE => '65536', REPLICATION_SCOPE => '0'}
1 row(s) in 0.1870 seconds
put 'venkataw:nycstations', 1224, 'nycstationfam:name', 'citiWunnava'
put 'venkataw:nycstations',1224,'nycstationfam:short_name','citiW'
put 'venkataw:nycstations',1224,'nycstationfam:lat','-90.12'
put 'venkataw:nycstations',1224,'nycstationfam:lon','.92'
put 'venkataw:nycstations',1224,'nycstationfam:region_id','9192'
put 'venkataw:nycstations',1224,'nycstationfam:capacity','100202'
put 'venkataw:nycstations',1224,'nycstationfam:rental_url','http://www.google.com/'
hbase(main):016:0> scan 'venkataw:nycstations'
ROW                              COLUMN+CELL
 1224                            column=nycstationfam:capacity, timestamp=1538594876306, value=100202
 1224                            column=nycstationfam:lat, timestamp=1538594875626, value=-90.12
 1224                            column=nycstationfam:lon, timestamp=1538594875643, value=.92
 1224                            column=nycstationfam:name, timestamp=1538594875555, value=citiWunnava
 1224                            column=nycstationfam:region_id, timestamp=1538594875660, value=9192
 1224                            column=nycstationfam:rental_url, timestamp=1538594902755, value=http://www.google.com/
 1224                            column=nycstationfam:short_name, timestamp=1538594875606, value=citiW


alter 'venkataw:nycstations', NAME=>'nycstationfam',VERSIONS => 10000
Step 2: NiFi Workflow to publish data to HBase table
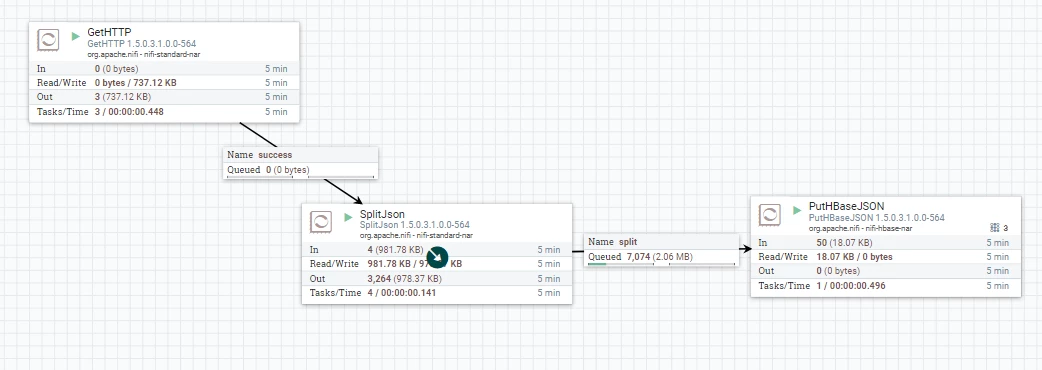
- The above NiFi workflow consumes messages from a web server and published it to HBase.
Configuration for the processors is as follows:
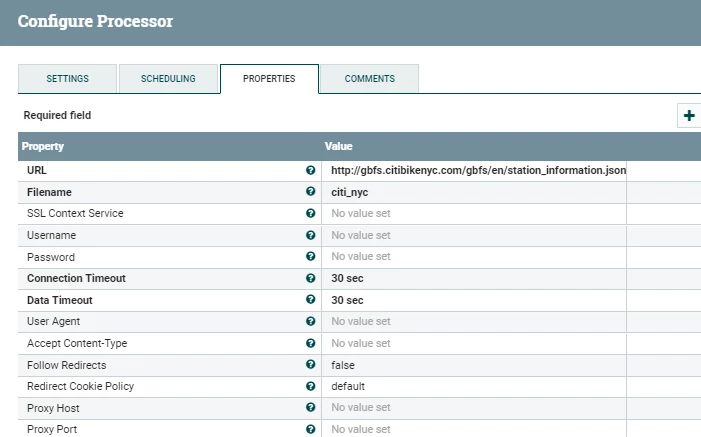
GetHTTP processor reads the REST endpoint every 5 seconds.
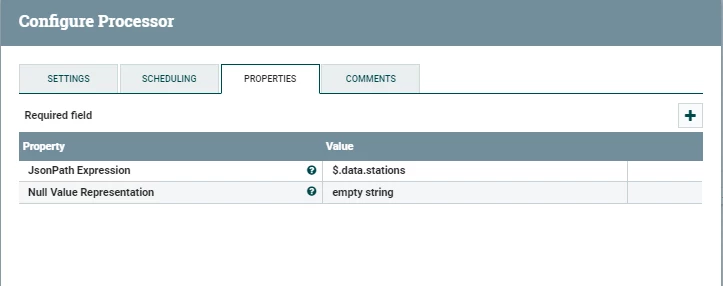
We extract the stations object using SplitJson processor
Finally we use the PutHBaseJson processor we ingest the data to the destination HBase Table created above. Notice that I am trying to randomly assign row identifier so that eventually I get multiple rows versions for the same identifier
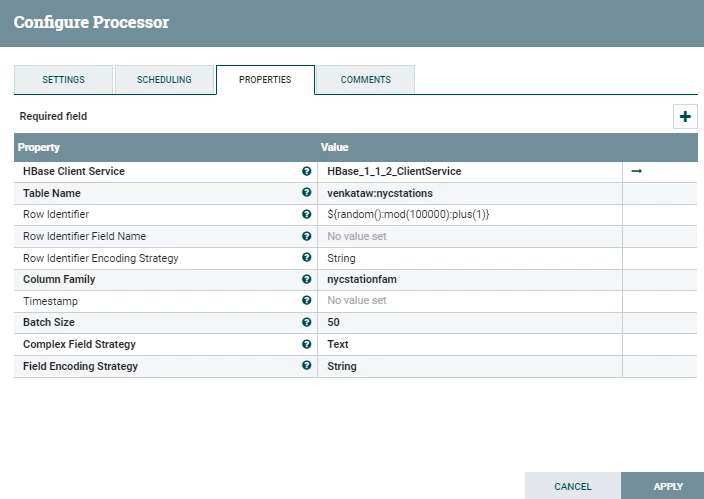
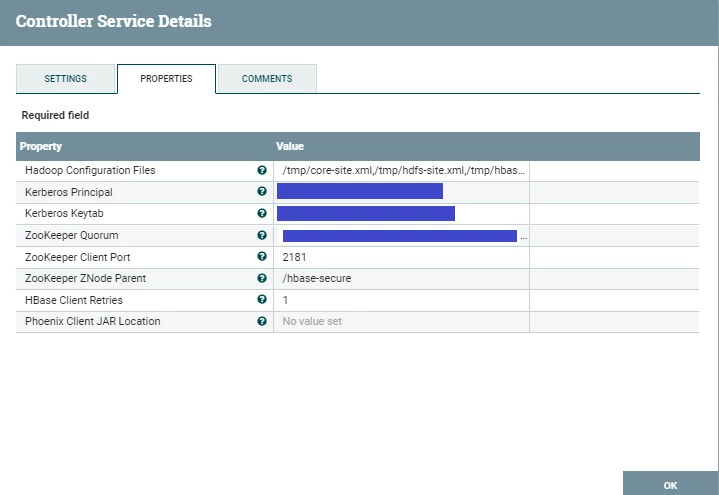
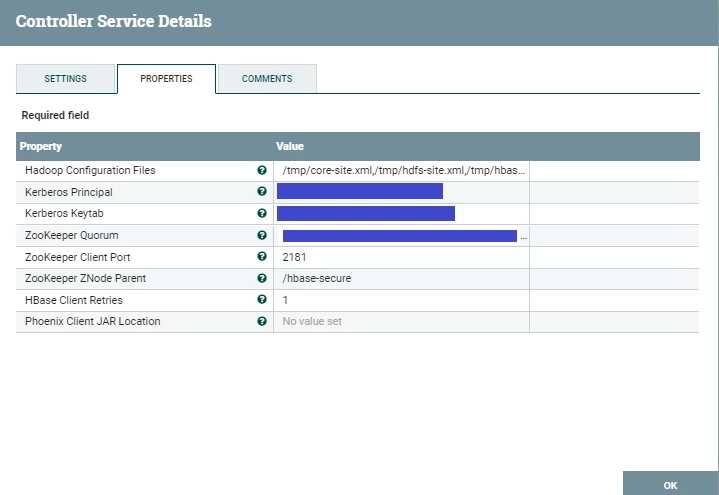
The PutHBaseJson processor uses the HBase Client Controller Servicer to connect to HBase using Kerberos credentials.
Step 3: Run queries to read the latest version and all available versions
- I tried querying all versions vs. latest versions in HBase with the following queries
hbase(main):002:0> get 'venkataw:nycstations', 99886 , {COLUMN=> ['nycstationfam:station_id','nycstationfam:name','nycstationfam:short_name','nycstationfam:lat','nycstationfam:lon','nycstationfam:region_id','nycstationfam:capacity','nycstationfam:rental_url']}
COLUMN                                                CELL
 nycstationfam:capacity                               timestamp=1507322481470, value=31
 nycstationfam:lat                                    timestamp=1507322481470, value=40.71286844
 nycstationfam:lon                                    timestamp=1507322481470, value=-73.95698119
 nycstationfam:name                                   timestamp=1507322481470, value=Grand St & Havemeyer St
 nycstationfam:region_id                              timestamp=1507322481470, value=71
 nycstationfam:rental_url                             timestamp=1507322481470, value=http://app.citibikenyc.com/S6Lr/IBV092JufD?station_id=471
 nycstationfam:short_name                             timestamp=1507322481470, value=5267.08
 nycstationfam:station_id                             timestamp=1507322481470, value=471
8 row(s) in 0.0600 seconds


get 'venkataw:nycstations', 99828 , {COLUMN=> ['nycstationfam:station_id','nycstationfam:name','nycstationfam:short_name','nycstationfam:lat','nycstationfam:lon','nycstationfam:region_id','nycstationfam:capacity','nycstationfam:rental_url'],VERSIONS => 100}
{done for diff. rowids}
24 row(s) in 0.0200 seconds
16 row(s) in 0.0300 seconds
8 row(s) in 0.0310 seconds
232 row(s) in 0.1850 seconds
8 row(s) in 0.0570 seconds
152 row(s) in 0.0380 seconds
184 row(s) in 0.0420 seconds
208 row(s) in 0.1550 seconds


1 row:-
8 row(s) in 0.0050 seconds
8 row(s) in 0.0040 seconds
8 row(s) in 0.0060 seconds


all versions:-
14765 row(s) in 2.4350 seconds
14351 row(s) in 1.1620 seconds
14572 row(s) in 2.4210 seconds
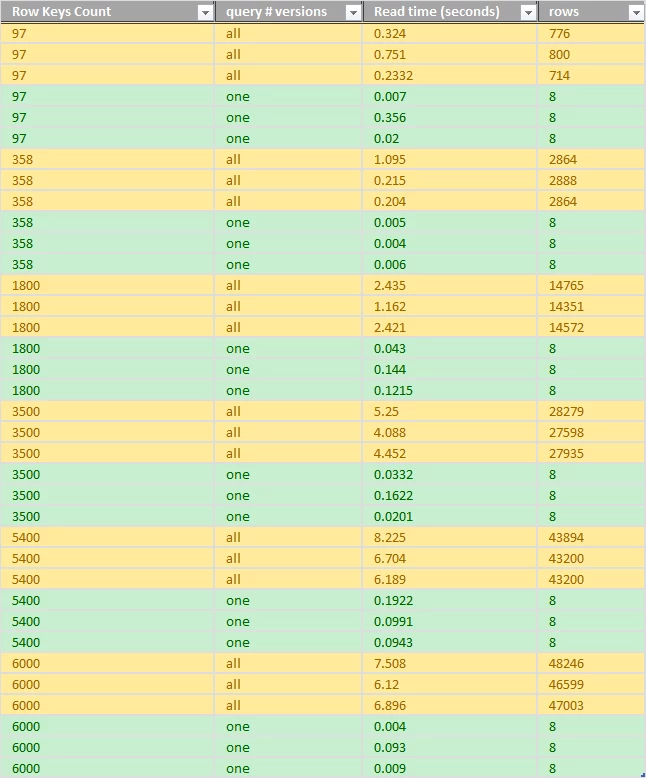
In the above results
* The green rows are for the latest version reads
* The yellow rows are all version reads
Notice how latest version reads are fairly consistent and have a smaller response times.
Also notice as the number of versions (rows) increase, the response times for all-version reads keep increasing.
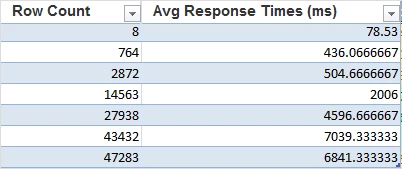
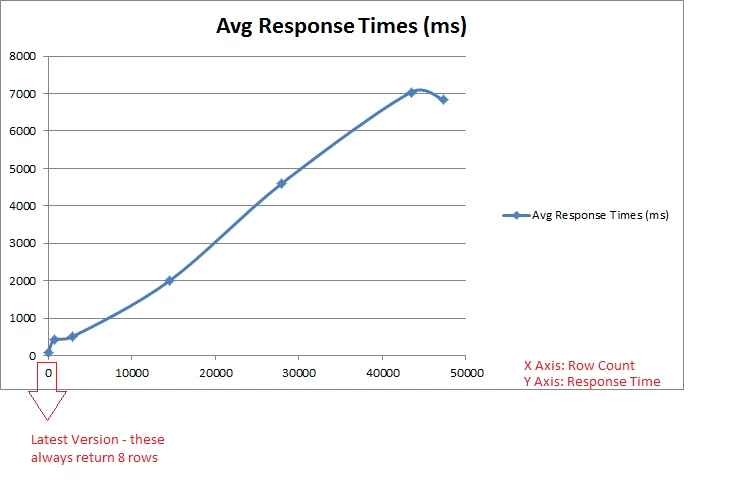
So based on this observation, as expected, it would seem like a query to get the latest version would consistently perform well when compared to a query which returns ‘n’ versions.