Parsing Web Pages for Images with Apache NiFi
Parsing Web Pages for Images with Apache NiFi
This could be used to build a web crawler that downloads images. I am downloading awesome images from Pixabay!
URL: https://pixabay.com/en/photos/?image_type=&cat=&min_width=&min_height=&q=data+science&order=popular
I wanted to be able to grab every image from a page, I have some web sites I want to backup my images from. So I added a processor that uses JSoup to do.
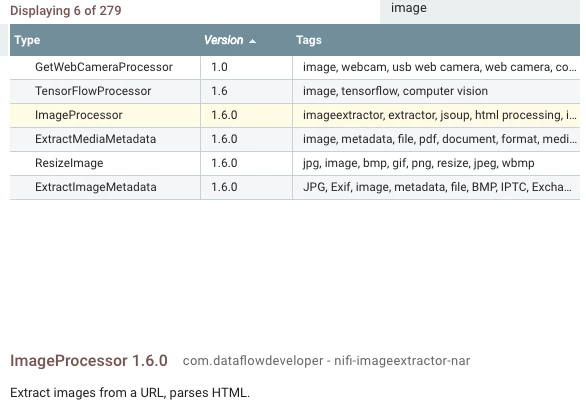
Once you download the NAR from github and deploy to your /usr/hdf/current/nifi/lib directories and restart Apache NiFi you will have a new processor. It is ImageProcessor listed version 1.6.0.
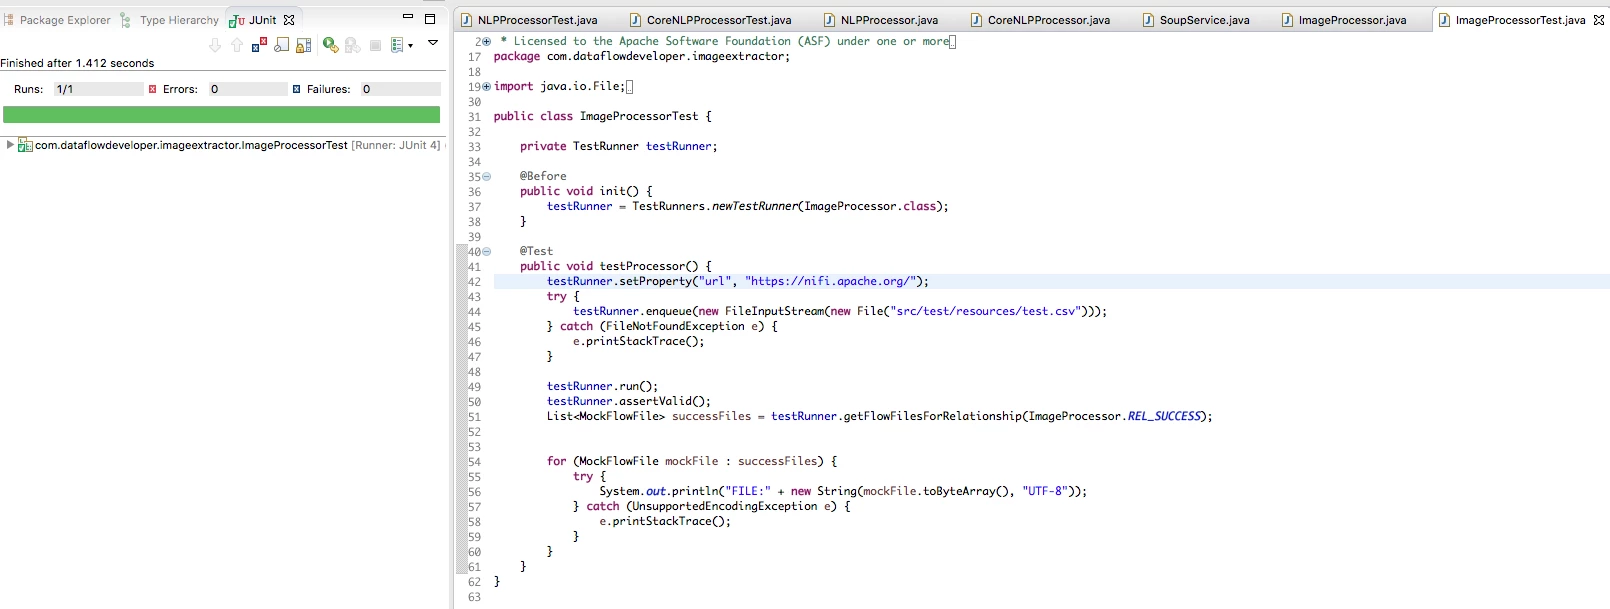
You can examine and test the Java source code if you wish.
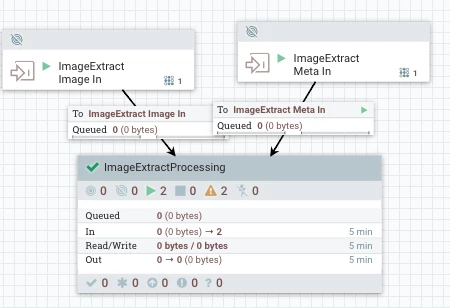
Here is an example flow of grabbing all the images from a pixabay URL then filtering out the empty images. Then we split into individual image URLs. We pull out that tag and then download those images. If they are not blank or small I route to TensorFlow to run some inception on it. I extract image meta data and then we send it to my production cluster for processing and storing of the image in an object store and the meta data to a Hive table.
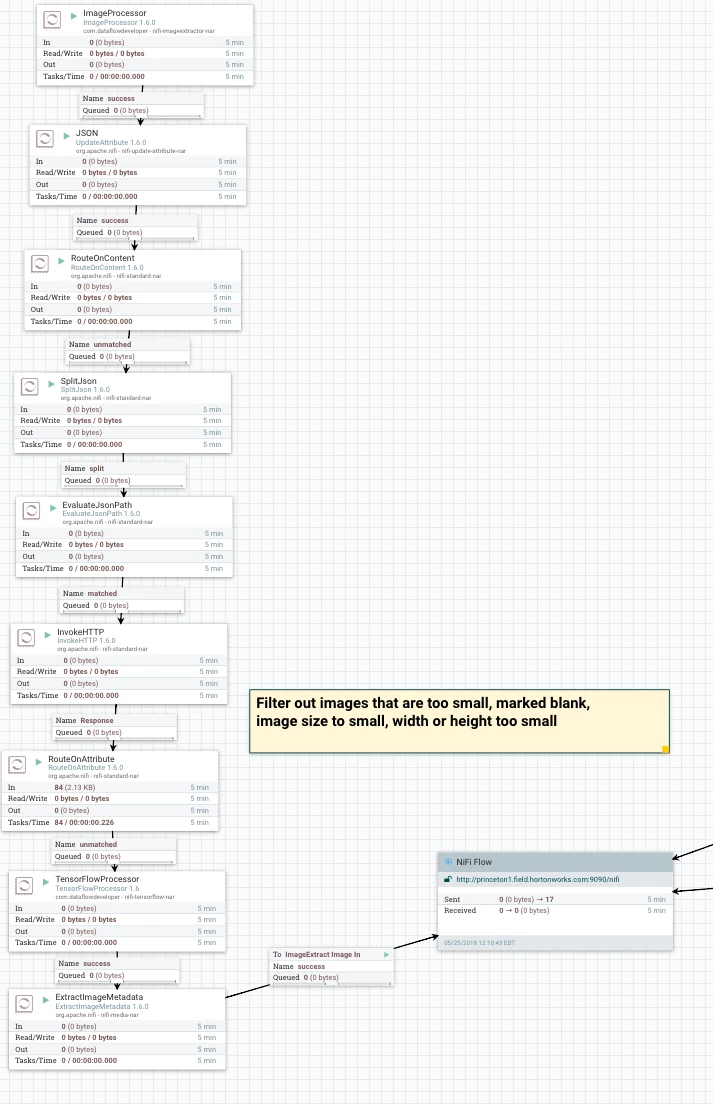
Our Routing To Filter Away Small and blank images
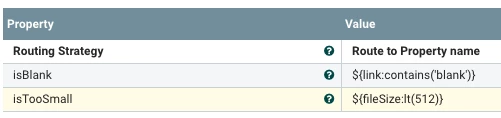
Pretty basic flow to process. I use my custom Attribute Cleaner to clean up the names and make all the attribute names Apache Avro name compliant.
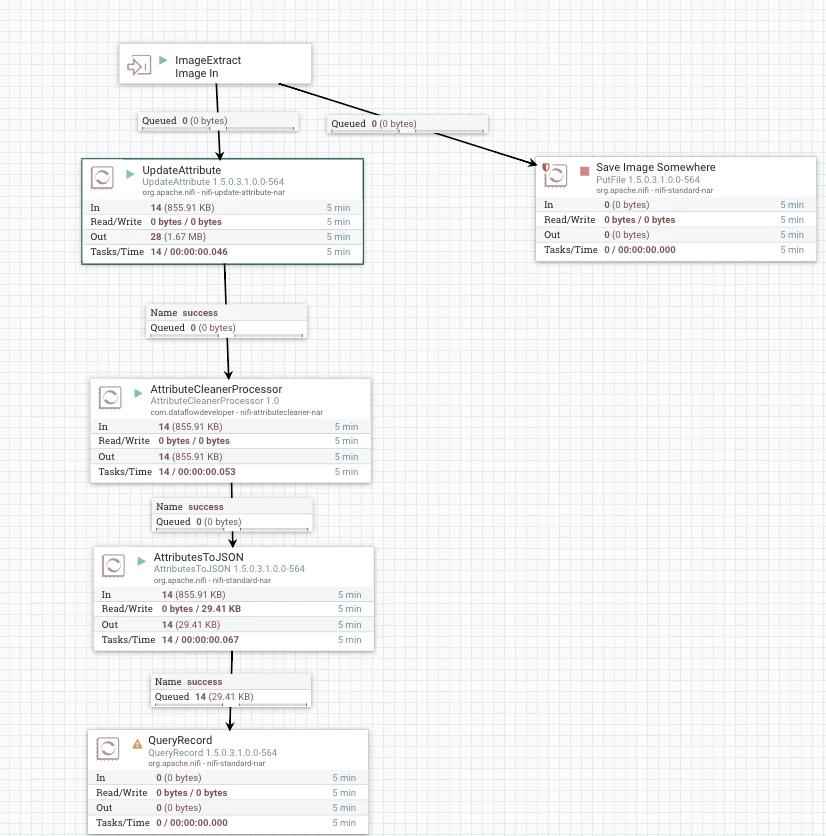
Some of the useful metadata pulled from the image. See the Height and Width, very useful.
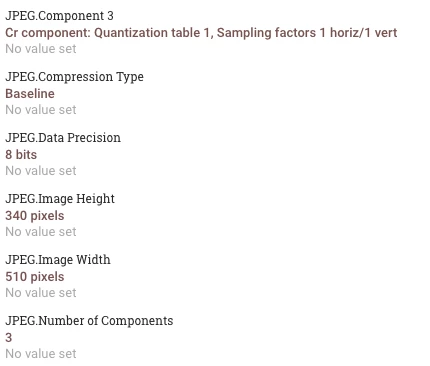
High Level Processing Flow
Example Data
{
  "segmentoriginalfilename" : "331368950519412",
  "ExifSubIFDFocalLength" : "16.7 mm",
  "Server" : "nginx/1.13.5",
  "ContentType" : "application/json",
  "invokehttpstatuscode" : "200",
  "fragmentidentifier" : "a5e50c12-4c36-4a65-bc74-83209bae7a9c",
  "JPEGImageWidth" : "453 pixels",
  "FileTypeDetectedFileTypeName" : "JPEG",
  "ExifIFD0Model" : "V-LUX 1",
  "label4" : "paintbrush",
  "LastModified" : "Wed, 18 Apr 2018 13:04:35 GMT",
  "label5" : "binder",
  "ExifIFD0ExposureTime" : "1/30 sec",
  "MediaType" : "application/json",
  "JFIFYResolution" : "300 dots",
  "JPEGImageHeight" : "340 pixels",
  "ExifSubIFDFNumber" : "f/3.2",
  "JFIFThumbnailHeightPixels" : "0",
  "ExifSubIFDExposureTime" : "1/30 sec",
  "invokehttpstatusmessage" : "OK",
  "ETag" : "\"5ad74263-4dab\"",
  "JPEGNumberofComponents" : "3",
  "JFIFXResolution" : "300 dots",
  "fragmentcount" : "100",
  "CacheControl" : "no-cache, must-revalidate",
  "invokehttptxid" : "74ee166e-7897-40be-b508-b823bece6ce6",
  "FileTypeExpectedFileNameExtension" : "jpg",
  "mediatype" : "application/json",
  "JPEGDataPrecision" : "8 bits",
  "probability4" : "2.19%",
  "probability3" : "4.25%",
  "invokehttprequesturl" : "https://cdn.pixabay.com/photo/2018/04/18/15/04/literature-3330647__340.jpg",
  "probability2" : "4.44%",
  "probability1" : "42.69%",
  "link" : "https://cdn.pixabay.com/photo/2018/04/18/15/04/literature-3330647__340.jpg",
  "JFIFThumbnailWidthPixels" : "0",
  "JPEGCompressionType" : "Baseline",
  "sshost" : "10.42.80.116",
  "JFIFVersion" : "1.1",
  "MimeType" : "application/json",
  "FileTypeDetectedFileTypeLongName" : "Joint Photographic Experts Group",
  "invokehttpremotedn" : "CN=pixabay.com",
  "fragmentindex" : "15",
  "JPEGComponent3" : "Cr component: Quantization table 1, Sampling factors 1 horiz/1 vert",
  "RouteOnContentRoute" : "unmatched",
  "JPEGComponent2" : "Cb component: Quantization table 1, Sampling factors 1 horiz/1 vert",
  "AcceptRanges" : "bytes",
  "JPEGComponent1" : "Y component: Quantization table 0, Sampling factors 2 horiz/2 vert",
  "FileTypeDetectedMIMEType" : "image/jpeg",
  "HuffmanNumberofTables" : "4 Huffman tables",
  "ExifSubIFDDateTimeOriginal" : "2012:10:08 13:44:30",
  "ssaddress" : "10.42.80.116:50450",
  "Connection" : "keep-alive",
  "miimetype" : "application/json",
  "label1" : "quill",
  "label2" : "safety pin",
  "Date" : "Fri, 25 May 2018 15:46:15 GMT",
  "label3" : "umbrella",
  "contenttype" : "application/json",
  "ExifIFD0Make" : "LEICA",
  "mimetype" : "application/json",
  "ContentLength" : "19883",
  "JFIFResolutionUnits" : "inch",
  "probability5" : "1.82%"
}
Source Code:
https://github.com/tspannhw/nifi-imageextractor-processor
References:
- Parsing Any Document https://community.hortonworks.com/articles/163776/parsing-any-document-with-apache-nifi-15-with-apac.html
- A Simple Webcrawler (First Part) https://community.hortonworks.com/articles/65239/mp3-jukebox-with-nifi-1x.html
- Webcrawler Options
- https://github.com/USCDataScience/sparkler
- http://nutch.apache.org/
- https://github.com/yasserg/crawler4j