
Our Community is getting an upgrade! To get everything ready for the relaunch, we’ll be placing the site in read-only mode starting September 21st.
We really appreciate your understanding while we get things set up behind the scenes. Catch up on all the exciting details about the move here.
Need help or have questions? Drop us a line at [email protected]

Support Questions
 Hi, I'm CLEO! Something exciting is coming to the Community. Stay Tuned!
- Cloudera Community
- Support
- Support Questions
- Error while processing statement: FAILED: Error in...
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
Error while processing statement: FAILED: Error in acquiring locks: Error communicating with the metastore (state=42000,code=10)
- Labels:
-
Apache Hive

Created 03-18-2021 12:32 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Error while processing statement: FAILED: Error in acquiring locks: Error communicating with the metastore (state=42000,code=10)
Unable to create Hive Table, while creating a table getting error in acquiring locks: Error communicating with the metastore,
ERROR : FAILED: Error in acquiring locks: Error communicating with the metastore
org.apache.hadoop.hive.ql.lockmgr.LockException: Error communicating with the metastore
at org.apache.hadoop.hive.ql.lockmgr.DbLockManager.lock(DbLockManager.java:178)
at org.apache.hadoop.hive.ql.lockmgr.DbTxnManager.acquireLocks(DbTxnManager.java:447)
at org.apache.hadoop.hive.ql.lockmgr.DbTxnManager.acquireLocksWithHeartbeatDelay(DbTxnManager.java:463)
at org.apache.hadoop.hive.ql.lockmgr.DbTxnManager.acquireLocks(DbTxnManager.java:278)
at org.apache.hadoop.hive.ql.lockmgr.HiveTxnManagerImpl.acquireLocks(HiveTxnManagerImpl.java:76)
at org.apache.hadoop.hive.ql.lockmgr.DbTxnManager.acquireLocks(DbTxnManager.java:95)
at org.apache.hadoop.hive.ql.Driver.acquireLocks(Driver.java:1651)
at org.apache.hadoop.hive.ql.Driver.lockAndRespond(Driver.java:1838)
at org.apache.hadoop.hive.ql.Driver.runInternal(Driver.java:2008)
at org.apache.hadoop.hive.ql.Driver.run(Driver.java:1752)
at org.apache.hadoop.hive.ql.Driver.run(Driver.java:1746)
at org.apache.hadoop.hive.ql.reexec.ReExecDriver.run(ReExecDriver.java:157)
at org.apache.hive.service.cli.operation.SQLOperation.runQuery(SQLOperation.java:226)
at org.apache.hive.service.cli.operation.SQLOperation.access$700(SQLOperation.java:87)
at org.apache.hive.service.cli.operation.SQLOperation$BackgroundWork$1.run(SQLOperation.java:324)
at java.security.AccessController.doPrivileged(Native Method)
at javax.security.auth.Subject.doAs(Subject.java:422)
at org.apache.hadoop.security.UserGroupInformation.doAs(UserGroupInformation.java:1730)
at org.apache.hive.service.cli.operation.SQLOperation$BackgroundWork.run(SQLOperation.java:342)
at java.util.concurrent.Executors$RunnableAdapter.call(Executors.java:511)
at java.util.concurrent.FutureTask.run(FutureTask.java:266)
at java.util.concurrent.Executors$RunnableAdapter.call(Executors.java:511)
at java.util.concurrent.FutureTask.run(FutureTask.java:266)
at java.util.concurrent.ThreadPoolExecutor.runWorker(ThreadPoolExecutor.java:1149)
at java.util.concurrent.ThreadPoolExecutor$Worker.run(ThreadPoolExecutor.java:624)
at java.lang.Thread.run(Thread.java:748)
Caused by: org.apache.thrift.TApplicationException: Internal error processing lock
at org.apache.thrift.TApplicationException.read(TApplicationException.java:111)
at org.apache.thrift.TServiceClient.receiveBase(TServiceClient.java:79)
at org.apache.hadoop.hive.metastore.api.ThriftHiveMetastore$Client.recv_lock(ThriftHiveMetastore.java:5510)
at org.apache.hadoop.hive.metastore.api.ThriftHiveMetastore$Client.lock(ThriftHiveMetastore.java:5497)
at org.apache.hadoop.hive.metastore.HiveMetaStoreClient.lock(HiveMetaStoreClient.java:2745)
at sun.reflect.NativeMethodAccessorImpl.invoke0(Native Method)
at sun.reflect.NativeMethodAccessorImpl.invoke(NativeMethodAccessorImpl.java:62)
at sun.reflect.DelegatingMethodAccessorImpl.invoke(DelegatingMethodAccessorImpl.java:43)
at java.lang.reflect.Method.invoke(Method.java:498)
at org.apache.hadoop.hive.metastore.RetryingMetaStoreClient.invoke(RetryingMetaStoreClient.java:212)
at com.sun.proxy.$Proxy58.lock(Unknown Source)
at sun.reflect.NativeMethodAccessorImpl.invoke0(Native Method)
at sun.reflect.NativeMethodAccessorImpl.invoke(NativeMethodAccessorImpl.java:62)
at sun.reflect.DelegatingMethodAccessorImpl.invoke(DelegatingMethodAccessorImpl.java:43)
at java.lang.reflect.Method.invoke(Method.java:498)
at org.apache.hadoop.hive.metastore.HiveMetaStoreClient$SynchronizedHandler.invoke(HiveMetaStoreClient.java:2956)
at com.sun.proxy.$Proxy58.lock(Unknown Source)
at org.apache.hadoop.hive.ql.lockmgr.DbLockManager.lock(DbLockManager.java:103)
... 25 more
Error: Error while processing statement: FAILED: Error in acquiring locks: Error communicating with the metastore (state=42000,code=10)
tried few solutions, it didn't work,
set hive.support.concurrency= true to false
set hive.lock.numretries=100;
set hive.lock.sleep.between.retries=50;
hive.server2.metrics.enabled = true to false
hive.metastore.metrics.enabled = true to false
hive.exec.compress.intermediate = false to true
and also
show locks;
show locks extended;
it's not showing any locks in hive,
Hope you understand the issue,


Created 03-18-2021 05:55 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
This is a known issue hash indexes are prone to become corrupted. HiveMetastore makes use of hash indexes for PostgreSQL and these corruptions cause issues.
Affected Indexes: TC_TXNID_INDEX and HL_TXNID_INDEX
Workaround:
The workaround is to reindex the corrupted indexes. For example, in PostgreSQL run reindex index tc_txnid_index. And, If you use PostgreSQL as the backend database, a supported version later than 9.6 is recommended.
You can refer the below link for more reference:
https://docs.cloudera.com/HDPDocuments/HDP3/HDP-3.1.5/release-notes/content/known_issues.html
Created 03-18-2021 05:55 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
This is a known issue hash indexes are prone to become corrupted. HiveMetastore makes use of hash indexes for PostgreSQL and these corruptions cause issues.
Affected Indexes: TC_TXNID_INDEX and HL_TXNID_INDEX
Workaround:
The workaround is to reindex the corrupted indexes. For example, in PostgreSQL run reindex index tc_txnid_index. And, If you use PostgreSQL as the backend database, a supported version later than 9.6 is recommended.
You can refer the below link for more reference:
https://docs.cloudera.com/HDPDocuments/HDP3/HDP-3.1.5/release-notes/content/known_issues.html
Created on 03-19-2021 03:07 AM - edited 03-19-2021 03:09 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Thanks Asish,
now facing some other issue,
I have been reindex the corrupted indexes successfully(hl_txnid_index and tc_txnid_index),
but now unable to query the any table's in Hive,
In Postgresql logs showing
2021-03-19 09:00:15 UTC::@:[9941]:LOG: skipping vacuum of "hive_locks" --- lock not available
2021-03-19 09:00:31 UTC::@:[10049]:LOG: skipping vacuum of "hive_locks" --- lock not available
2021-03-19 09:00:46 UTC::@:[10178]:LOG: skipping vacuum of "hive_locks" --- lock not available
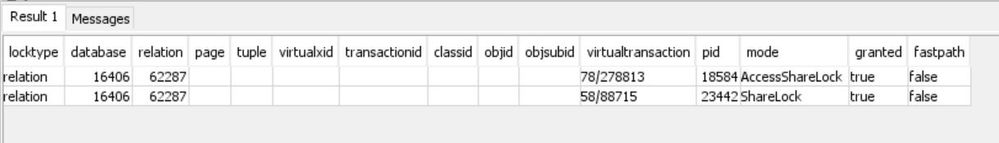
SELECT * FROM pg_locks WHERE relation = 'HIVE_LOCKS'::regclass;
please check attached file for locks,
And also in Hive logs showing Unable to rename temp file
2021-03-19T09:59:27,909 ERROR [json-metric-reporter]: metrics2.JsonFileMetricsReporter (:()) - Unable to rename temp file /tmp/hmetrics8066666106938386459json to /tmp/report.json
2021-03-19T09:59:27,909 ERROR [json-metric-reporter]: metrics2.JsonFileMetricsReporter (:()) - Exception during rename
java.nio.file.FileSystemException: /tmp/hmetrics8066666106938386459json -> /tmp/report.json: Operation not permitted
at sun.nio.fs.UnixException.translateToIOException(UnixException.java:91) ~[?:1.8.0_232]
at sun.nio.fs.UnixException.rethrowAsIOException(UnixException.java:102) ~[?:1.8.0_232]
at sun.nio.fs.UnixCopyFile.move(UnixCopyFile.java:396) ~[?:1.8.0_232]
at sun.nio.fs.UnixFileSystemProvider.move(UnixFileSystemProvider.java:262) ~[?:1.8.0_232]
at java.nio.file.Files.move(Files.java:1395) ~[?:1.8.0_232]
at org.apache.hadoop.hive.common.metrics.metrics2.JsonFileMetricsReporter.run(JsonFileMetricsReporter.java:175) ~[hive-common-3.1.0.3.1.0.0-78.jar:3.1.0.3.1.0.0-78]
at java.util.concurrent.Executors$RunnableAdapter.call(Executors.java:511) ~[?:1.8.0_232]
at java.util.concurrent.FutureTask.runAndReset(FutureTask.java:308) ~[?:1.8.0_232]
at java.util.concurrent.ScheduledThreadPoolExecutor$ScheduledFutureTask.access$301(ScheduledThreadPoolExecutor.java:180) ~[?:1.8.0_232]
at java.util.concurrent.ScheduledThreadPoolExecutor$ScheduledFutureTask.run(ScheduledThreadPoolExecutor.java:294) ~[?:1.8.0_232]
at java.util.concurrent.ThreadPoolExecutor.runWorker(ThreadPoolExecutor.java:1149) ~[?:1.8.0_232]
at java.util.concurrent.ThreadPoolExecutor$Worker.run(ThreadPoolExecutor.java:624) ~[?:1.8.0_232]
at java.lang.Thread.run(Thread.java:748) [?:1.8.0_232]
Created 03-25-2021 07:01 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Can we track in a separate thread ?
We need the queryId and the hiveserver2 logs
Created 04-05-2021 03:04 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content

Created 06-14-2022 12:54 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
HI,
We have the same problem, but the database where the metastore is located is ORACLE; How can we provide a solution, it is very frequent in several consultations that we make to HIVE

Created 06-14-2022 12:57 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
@sdlfjfldgj As this is an older post, you would have a better chance of receiving a resolution by starting a new thread. This will also be an opportunity to provide details specific to your environment that could aid others in assisting you with a more accurate answer to your question. You can link this thread as a reference in your new post. Thanks!
Regards,
Diana Torres,Senior Community Moderator
Was your question answered? Make sure to mark the answer as the accepted solution.
If you find a reply useful, say thanks by clicking on the thumbs up button.
Learn more about the Cloudera Community:

Created 02-19-2023 11:00 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
What was the fix made to resolve this issue? we have same issue from past 4 to 5 months. It will be thankful if anyone can share their experience here.
Created 02-20-2023 06:33 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
@TADA As this is an older post, you would have a better chance of receiving a resolution by starting a new thread. This will also be an opportunity to provide details specific to your environment that could aid others in assisting you with a more accurate answer to your question. You can link this thread as a reference in your new post.
Regards,
Diana Torres,Senior Community Moderator
Was your question answered? Make sure to mark the answer as the accepted solution.
If you find a reply useful, say thanks by clicking on the thumbs up button.
Learn more about the Cloudera Community:


