Our Community is getting an upgrade! To get everything ready for the relaunch, we’ll be placing the site in read-only mode starting September 21st.
We really appreciate your understanding while we get things set up behind the scenes. Catch up on all the exciting details about the move here.
Need help or have questions? Drop us a line at [email protected]

Support Questions
 Hi, I'm CLEO! Something exciting is coming to the Community. Stay Tuned!
- Cloudera Community
- Support
- Support Questions
- how to connect to livy with kerberos authenticatio...
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
how to connect to livy with kerberos authentication on cloudera cluster
- Labels:
-
Apache Hadoop
-
Cloudera Manager

Created on
08-16-2022
09:25 AM
- last edited on
08-16-2022
05:46 PM
by
 ask_bill_brooks

- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
hello cloudera community,
we have installed livy directly on a cloudera cluster host and we are now trying to connect to livy now using kerberos but we are getting the following error:
<html>
<head>
<meta http-equiv="Content-Type" content="text/html;charset=ISO-8859-1"/>
<title>Error 401 </title>
</head>
<body>
<h2>HTTP ERROR: 401</h2>
<p>Problem accessing /sessions. Reason:
<pre> Authentication required</pre></p>
<hr /><a href="http://eclipse.org/jetty">Powered by Jetty:// 9.3.24.v20180605</a><hr/>
</body>
</html>
how can we make this connection to retest livy?
we are testing the connection with python3 script as follows:
import json, pprint, requests, textwrap
from requests_kerberos import HTTPKerberosAuth
host='http://localhost:8998'
data = {'kind': 'spark'}
headers = {'Requested-By': 'livy','Content-Type': 'application/json'}
auth=HTTPKerberosAuth()
r0 = requests.post(host + '/sessions', data=json.dumps(data), headers=headers,auth=auth)
r0.json()


Created 08-17-2022 02:51 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Hello @yagoaparecidoti :
- Did we get the valid kerberos ticket before running the code?
- Does the klist command show the valid expiry date?
- Check the output of the below code after running your code:
r0.headers["www-authenticate"]
Are we able to run the Sample Livy job using the CURL command?
Steps to run the sample job:
1. Copy the JAR to HDFS:
# hdfs dfs -put /opt/cloudera/parcels/CDH/jars/spark-examples<VERSION>.jar /tmp2. Make sure the JAR is present.
# hdfs dfs -ls /tmp/3. CURL command to run the Spark job using Livy API.
# curl -v -u: --negotiate -X POST --data '{"className": "org.apache.spark.examples.SparkPi", "jars": ["/tmp/spark-examples<VERSION>.jar"], "name": "livy-test", "file": "hdfs:///tmp/spark-examples<VERSION>.jar", "args": [10]}' -H "Content-Type: application/json" -H "X-Requested-By: User" http://<LIVY_NODE>:<PORT>/batches4. Check for the running and completed Livy sessions.
# curl http://<LIVY_NODE>:<PORT>/batches/ | python -m json.tool
NOTE:
* Change the JAR version ( <VERSION> ) according your CDP version.
* Replace the LIVY_NODE and PORT with the actual values.
* If you are running the cluster in secure mode, then make sure you have a valid Kerberos ticket and use the Kerberos authentication in curl command.
Created 08-17-2022 03:57 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
We can also try running the below python code:
1. Run the kinit command.
2. Run the code in Python shell:
import json, pprint, requests, textwrap
from requests_kerberos import HTTPKerberosAuth

host='http://localhost:8998'
headers = {'Requested-By': 'livy','Content-Type': 'application/json','X-Requested-By': 'livy'}
auth=HTTPKerberosAuth()

data={'className': 'org.apache.spark.examples.SparkPi','jars': ["/tmp/spark-examples_2.11-2.4.7.7.1.7.1000-141.jar"],'name': 'livy-test1', 'file': 'hdfs:///tmp/spark-examples_2.11-2.4.7.7.1.7.1000-141.jar','args': ["10"]}
r0 = requests.post(host + '/batches', data=json.dumps(data), headers=headers, auth=auth)
r0.json()
Created 08-17-2022 10:52 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
hi @Deepan_N
the "kinit" command was successfully executed
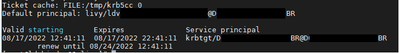
the "klist" command returns the date of the validated ticket and I have more than 10h to use the ticket.
Both modes have been tested:
curl:
curl -v -u: --negotiate -X POST --data '{"className": "org.apache.spark.examples.SparkPi", "jars": ["/tmp/spark-examples-1.6.0-cdh5.16.1-hadoop2.6.0-cdh5.16.1.jar"], "name": "livy-test", "file": "hdfs:///tmp/spark-examples-1.6.0-cdh5.16.1-hadoop2.6.0-cdh5.16.1.jar", "args": [10]}' -H "Content-Type: application/json" -H "X-Requested-By: User" http://localhost:8998/batches
python:
import json, pprint, requests, textwrap
from requests_kerberos import HTTPKerberosAuth
host='http://localhost:8998'
headers = {'Requested-By': 'livy','Content-Type': 'application/json','X-Requested-By': 'livy'}
auth=HTTPKerberosAuth()
data={'className': 'org.apache.spark.examples.SparkPi','jars': ["/tmp/spark-examples-1.6.0-cdh5.16.1-hadoop2.6.0-cdh5.16.1.jar"],'name': 'livy-test1', 'file': 'hdfs:///tmp/spark-examples-1.6.0-cdh5.16.1-hadoop2.6.0-cdh5.16.1.jar','args': ["10"]}
r0 = requests.post(host + '/batches', data=json.dumps(data), headers=headers, auth=auth)
r0.json()
but unfortunately both ways return the error:
<html>
<head>
<meta http-equiv="Content-Type" content="text/html;charset=ISO-8859-1"/>
<title>Error 401 </title>
</head>
<body>
<h2>HTTP ERROR: 401</h2>
<p>Problem accessing /batches. Reason:
<pre> Authentication required</pre></p>
<hr /><a href="http://eclipse.org/jetty">Powered by Jetty:// 9.3.24.v20180605</a><hr/>
</body>
</html>
PS¹: the cluster has kerberos
PS²: the user that validated the ticket with "kinit" is the livy user that is created in AD (active directory)
Created 08-19-2022 03:37 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Hello @yagoaparecidoti ,
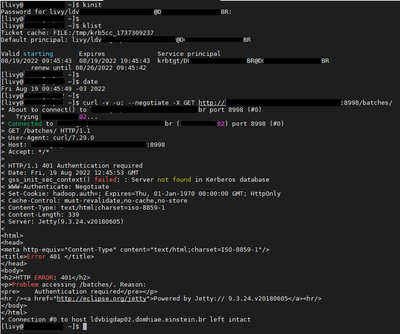
Can you please share the output of the below commands?
From the Python shell:
r0.headers["www-authenticate"]From the bash:
# kinit
# klist
# date
# curl -v -u: --negotiate -X GET http://<LIVY_NODE>:<PORT>/batches/Created 08-19-2022 05:51 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
hi @Deepan_N
by running the command below directly in python3:
r0.headers["www-authenticate"]
returns the following error:
Python 3.6.8 (default, Nov 16 2020, 16:55:22)
[GCC 4.8.5 20150623 (Red Hat 4.8.5-44)] on linux
Type "help", "copyright", "credits" or "license" for more information.
>>> r0.headers["www-authenticate"]
Traceback (most recent call last):
File "<stdin>", line 1, in <module>
NameError: name 'r0' is not defined
>>>
below is the screenshot of the commands executed in bash: