
Our Community is getting an upgrade! To get everything ready for the relaunch, we’ll be placing the site in read-only mode starting September 21st.
We really appreciate your understanding while we get things set up behind the scenes. Catch up on all the exciting details about the move here.
Need help or have questions? Drop us a line at [email protected]

Archives of Support Questions (Read Only)
- Cloudera Community
- Board Archive
- Archives of Support Questions (Read Only)
- Who agreed with this solution
Who agreed with this solution

Created on 04-21-2018 05:54 PM - edited 08-17-2019 06:38 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
As you are Fetching results of Join in this case, We need to store the state in DistributeMapCache/HDFS/Hive/Hbase and then pull the state value from DistributeMapCache/HDFS/Hive/Hbase and use that value as lower bound, run the join incrementally.
Example:-
As i'm having emp,dept tables with joindate(timestamp datatype) as incremental column name in emp table.
Flow:-
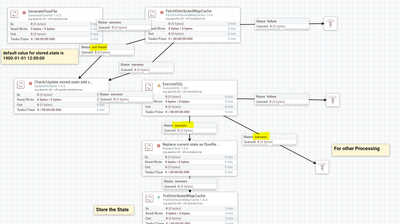
Flow Explanation:-
1.GenerateFlowFile processor:-
This processor will be trigger for the flow and Added a new property
increment.value
cache_key
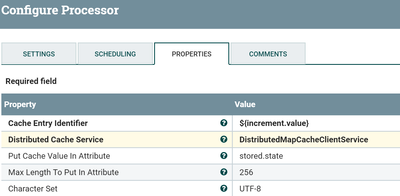
2.FetchDistributeMapCache:-
Configure and enable DistributedMapCacheClientService and change the below property values
Cache Entry Identifier
${increment.value}Distributed Cache Service
DistributedMapCacheClientService
Put Cache Value In Attribute
stored.state //if found then the value will be added to the flowfile as a attribute with name as stored.state
3.UpdateAttribute:-
We have feeded both success/not-found relations to Update Attribute processor
Add two properties
current.state
${now():format("yyyy-MM-dd HH:mm:ss")} //current timestamp as current.state attributestored.state
${stored.state:isNull():ifElse('1900-01-01 12:00:00','${stored.state}')} //if the value is null(in first run) then we are changing as 1900-01-01 12:00:00 and if the value is presented then we are keeping as is.

You can change the default value, stored/current.state values as per your requirements.
4.ExecuteSql:-
SQL select query
select e.id,d.name from
emp e join
dept d
on e.deptid=d.deptid
where
 e.joindate > '${stored.state}'
and
 e.joindate > '${current.state}'
as my emp table having joindate as incremental column so i have used stored.state and current.state attribute values in my join where clause to run incrementally.
--
Fork the success relation from executesql processor
Fork1: to stored the current.state in distributecache
Fork2: For other processing
--
Fork1:To store the state:-
5.Replace Text:-
Search Value
(?s)(^.*$)
Replacement Value
${current.state}
Replacement Strategy
Always Replace
Evaluation Mode
Entire text
Now we are changing the flowfile content with current.state value as new flowfile content.
-
6.PutDistributeCacheMap:-
Cache Entry Identifier
${increment.value}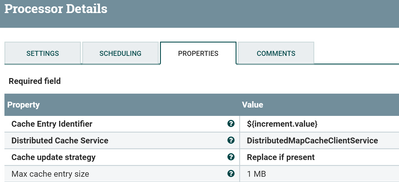
-
Fork2:-Further processing
like processing (or) storing the results to HDFS..etc
I have attached sample template below save/upload template to your NiFi instancce and change the configs as per your requirements.
