
Our Community is getting an upgrade! To get everything ready for the relaunch, we’ll be placing the site in read-only mode starting September 21st.
We really appreciate your understanding while we get things set up behind the scenes. Catch up on all the exciting details about the move here.
Need help or have questions? Drop us a line at [email protected]

Archives of Support Questions (Read Only)
- Cloudera Community
- Board Archive
- Archives of Support Questions (Read Only)
- Re: CDH 5.4.7 spark-streaming(1.3.0) kafka messag...
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
CDH 5.4.7 spark-streaming(1.3.0) kafka message into hive, too many staging directory not cleaned
- Labels:
-
Apache Hive
-
Apache Kafka
-
Apache Spark

Created on 01-16-2017 10:53 PM - edited 09-16-2022 03:55 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
This seems a bug of spark, see https://github.com/apache/spark/pull/16325
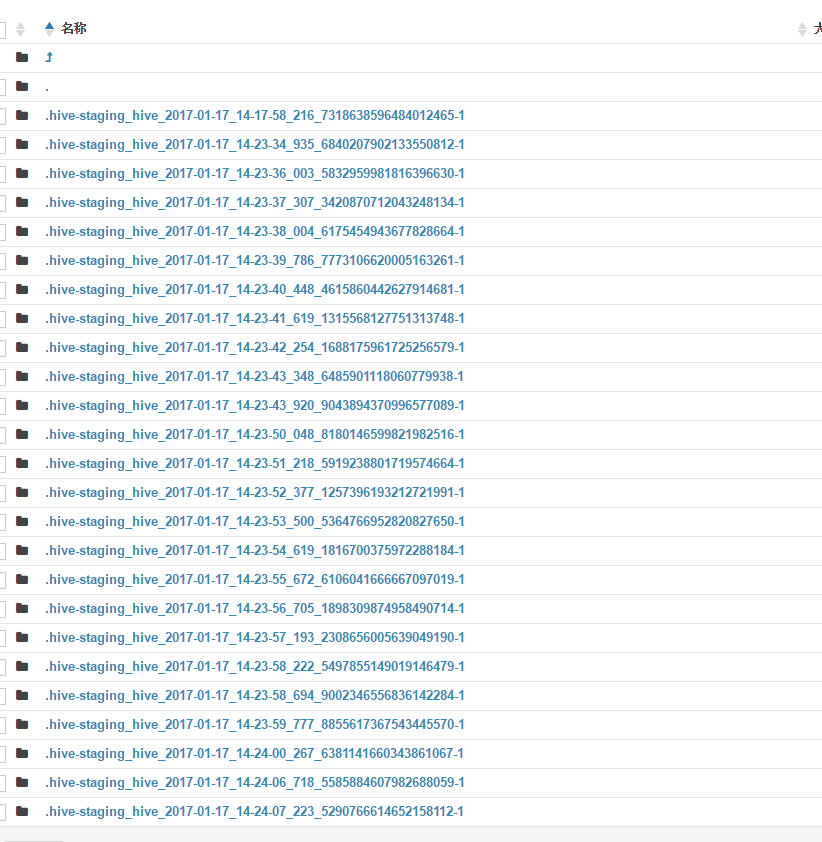
my code is here,it's work.But after a while,there are a lot of .hive-stagingXXXX directory.
a photo of my warehouse as attachment.
val sparkConf = new SparkConf()
    .setAppName("SendHistoryConsumer")
// .setMaster("local[2]") // for debug
val ssc = new StreamingContext(sparkConf, Seconds(batchInterval.toInt))
ssc.checkpoint("/opt/cloudera/checkPoint")

// kafka configuration
val topicsSet = Set(KafkaConfigConstant.PRIORITY_10)
val kafkaParams = Map[String, String](
    "metadata.broker.list" -> brokers,
    "serializer.class"->"kafka.serializer.StringEncoder",
    "group.id" -> groupId,
    "auto.offset.reset" -> "smallest"

val messages = KafkaUtils.createDirectStream[String, String, StringDecoder, StringDecoder](ssc, kafkaParams,
topicsSet)
//messages.print()
val dStream = messages
    .map(_._2)
    .filter(message =>
        !message.isEmpty
    )
    .map(parseTopic10)

dStream.foreachRDD(rdd =>

    if (!rdd.isEmpty && !rdd.partitions.isEmpty) {

        val hiveCtx = new HiveContext(rdd.sparkContext)
        val sendCallBackPoolDF = hiveCtx.createDataFrame(rdd, classOf[SmsSendHistDataSede])

        hiveCtx.sql("use db")
        sendCallBackPoolDF.registerTempTable("sendCallBack")

        hiveCtx.sql("set hive.exec.dynamic.partition=true")
        hiveCtx.sql("set hive.exec.dynamic.partition.mode=nonstrict")

        val smTrgPart = hiveCtx.sql("insert into table SmsSendHistData_orc partition" +
            "(partittime) select userid,city,mobile,msgcount,msgbody,sender,accepttype,sendcode," +
            "msgid,bmsgid,usermsgid,userbulkmsgid,channelmsgid,channelid,fileid,notifyurl,smscode ,smsstat," +
            "notifycallnum,sendsmsbody,parentmsgid,errormessage,queuename,startdeliveryid,acctime,sendtime," +
            "notifytime,smstype,from_unixtime(floor(acctime/1000),'yyyyMMdd') as partittime from sendCallBack")
        smTrgPart.saveAsTable("SmsSendHistData_orc", SaveMode.Append)

    }


Created 01-16-2017 11:08 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Created 01-16-2017 10:54 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
It seems like , every batch of streaming create a .hive-staging directory. Any suggestions ??
Created 01-16-2017 11:08 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Created on 01-16-2017 11:21 PM - edited 01-16-2017 11:51 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
@mbigelow Some of these directories only have a _success file which is a result of batch. In spark-streaming scene, should I periodly remove the empty directory since they're too much?
Could you explain your solution in more detail, I'm a stupid guy.
Created on 01-16-2017 11:25 PM - edited 01-16-2017 11:26 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
@mbigelow my active partition's data also split into small files too, It's really strange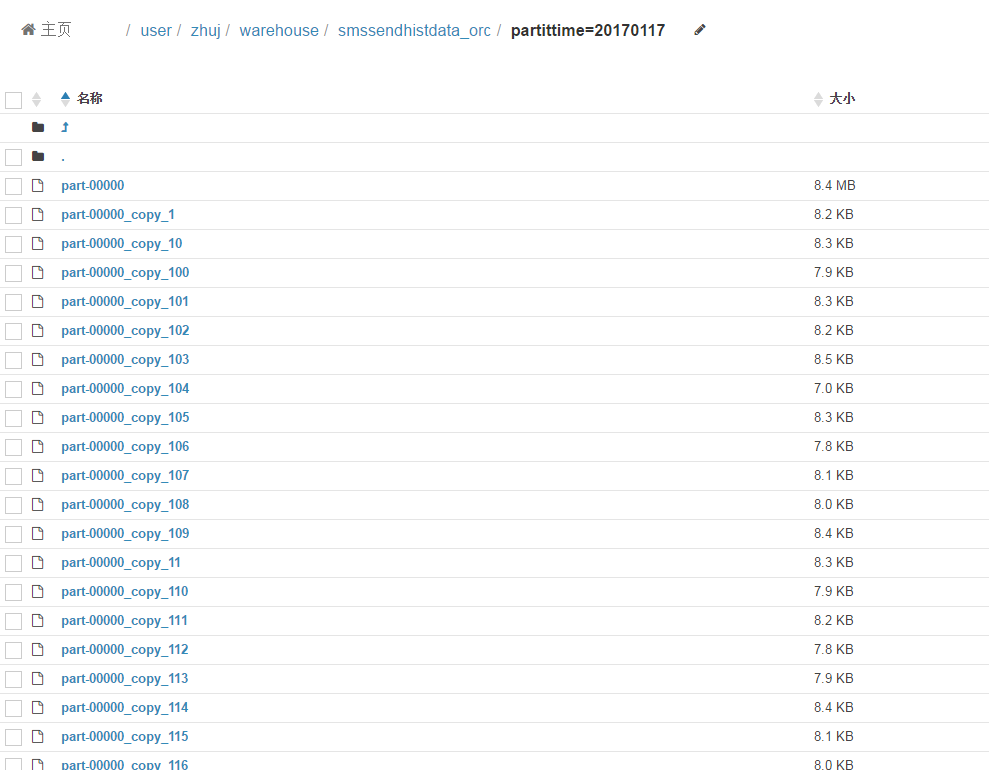
Created 01-17-2017 07:45 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content


