
Our Community is getting an upgrade! To get everything ready for the relaunch, we’ll be placing the site in read-only mode starting September 21st.
We really appreciate your understanding while we get things set up behind the scenes. Catch up on all the exciting details about the move here.
Need help or have questions? Drop us a line at [email protected]

Archives of Support Questions (Read Only)
- Cloudera Community
- Board Archive
- Archives of Support Questions (Read Only)
- Re: Spark saveAsTextFile with SnappyCodec on YARN ...
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
- Subscribe to RSS Feed
- Mark Question as New
- Mark Question as Read
- Float this Question for Current User
- Bookmark
- Subscribe
- Mute
- Printer Friendly Page
Spark saveAsTextFile with SnappyCodec on YARN getting : "native snappy library not available: this version of libhadoop was built without snappy support."
- Labels:
-
Apache Spark
-
Apache YARN

Created on 06-08-2016 08:59 AM - edited 08-19-2019 03:00 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
Hello,
I have a spark job that is run by spark-submit and at the end it saves some output using SparkContext saveAsTextFile with SnappyCodec. To test I am using sandbox 2.3.4
This is running fine using master = local[x], after following the suggestion in this thread. However Once I changed master = yarn-client I am getting the same "native snappy library not available: this version of libhadoop was built without snappy support." on YARN.
However I thought I have done all the necessary setup - any suggestions welcome!
When I check the Spark History server I can see the following in the environment:
Spark properties:


system properties:

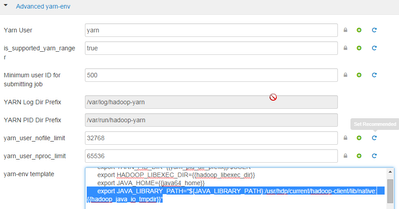
Furthermore in Ambari -> Yarn -> config -> Advanced yarn-env -> yarn-env template -> LD_LIBRARY_PATH:
Anything else I could do to make snappy available as a compression codec on YARN?
Thank you.


Created 06-08-2016 09:08 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
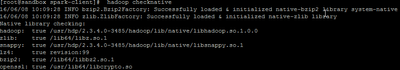
can you check whether snappy lib is installed on the cluster nodes using command 'hadoop checknative'?
Created 06-08-2016 09:08 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
can you check whether snappy lib is installed on the cluster nodes using command 'hadoop checknative'?
Created on 06-08-2016 09:10 AM - edited 08-19-2019 03:00 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
yes it is - as I said I was able to save in local mode.
Created 06-08-2016 09:21 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
can you add the following parameters in spark conf and see if it works
  spark.executor.extraClassPath /usr/hdp/current/hadoop-client/lib/snappy-java-*.jar
  spark.executor.extraLibraryPath /usr/hdp/current/hadoop-client/native
  spark.executor.extraJavaOptions -Djava.library.path=/usr/hdp/current/hadoop-client/lib/native/lib
Created on 06-08-2016 01:09 PM - edited 08-19-2019 03:00 AM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
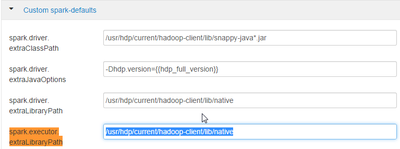
Thanks @Rajkumar Singh I have tried the mapred.child.java.opts and a few of the mapreduce settings suggested by @Jitendra Yadav but at the end just adding this spark.executor.extraLibraryPath would do the job.


Created 12-07-2018 12:24 PM
- Mark as New
- Bookmark
- Subscribe
- Mute
- Subscribe to RSS Feed
- Permalink
- Report Inappropriate Content
spark.executor.extraLibraryPath did the job. Thanks! @David Tam and @Jitendra Yadav


