

Setting Up a Data Science Platform on HDP using Anaconda
Setting Up a Data Science Platform on HDP using Anaconda
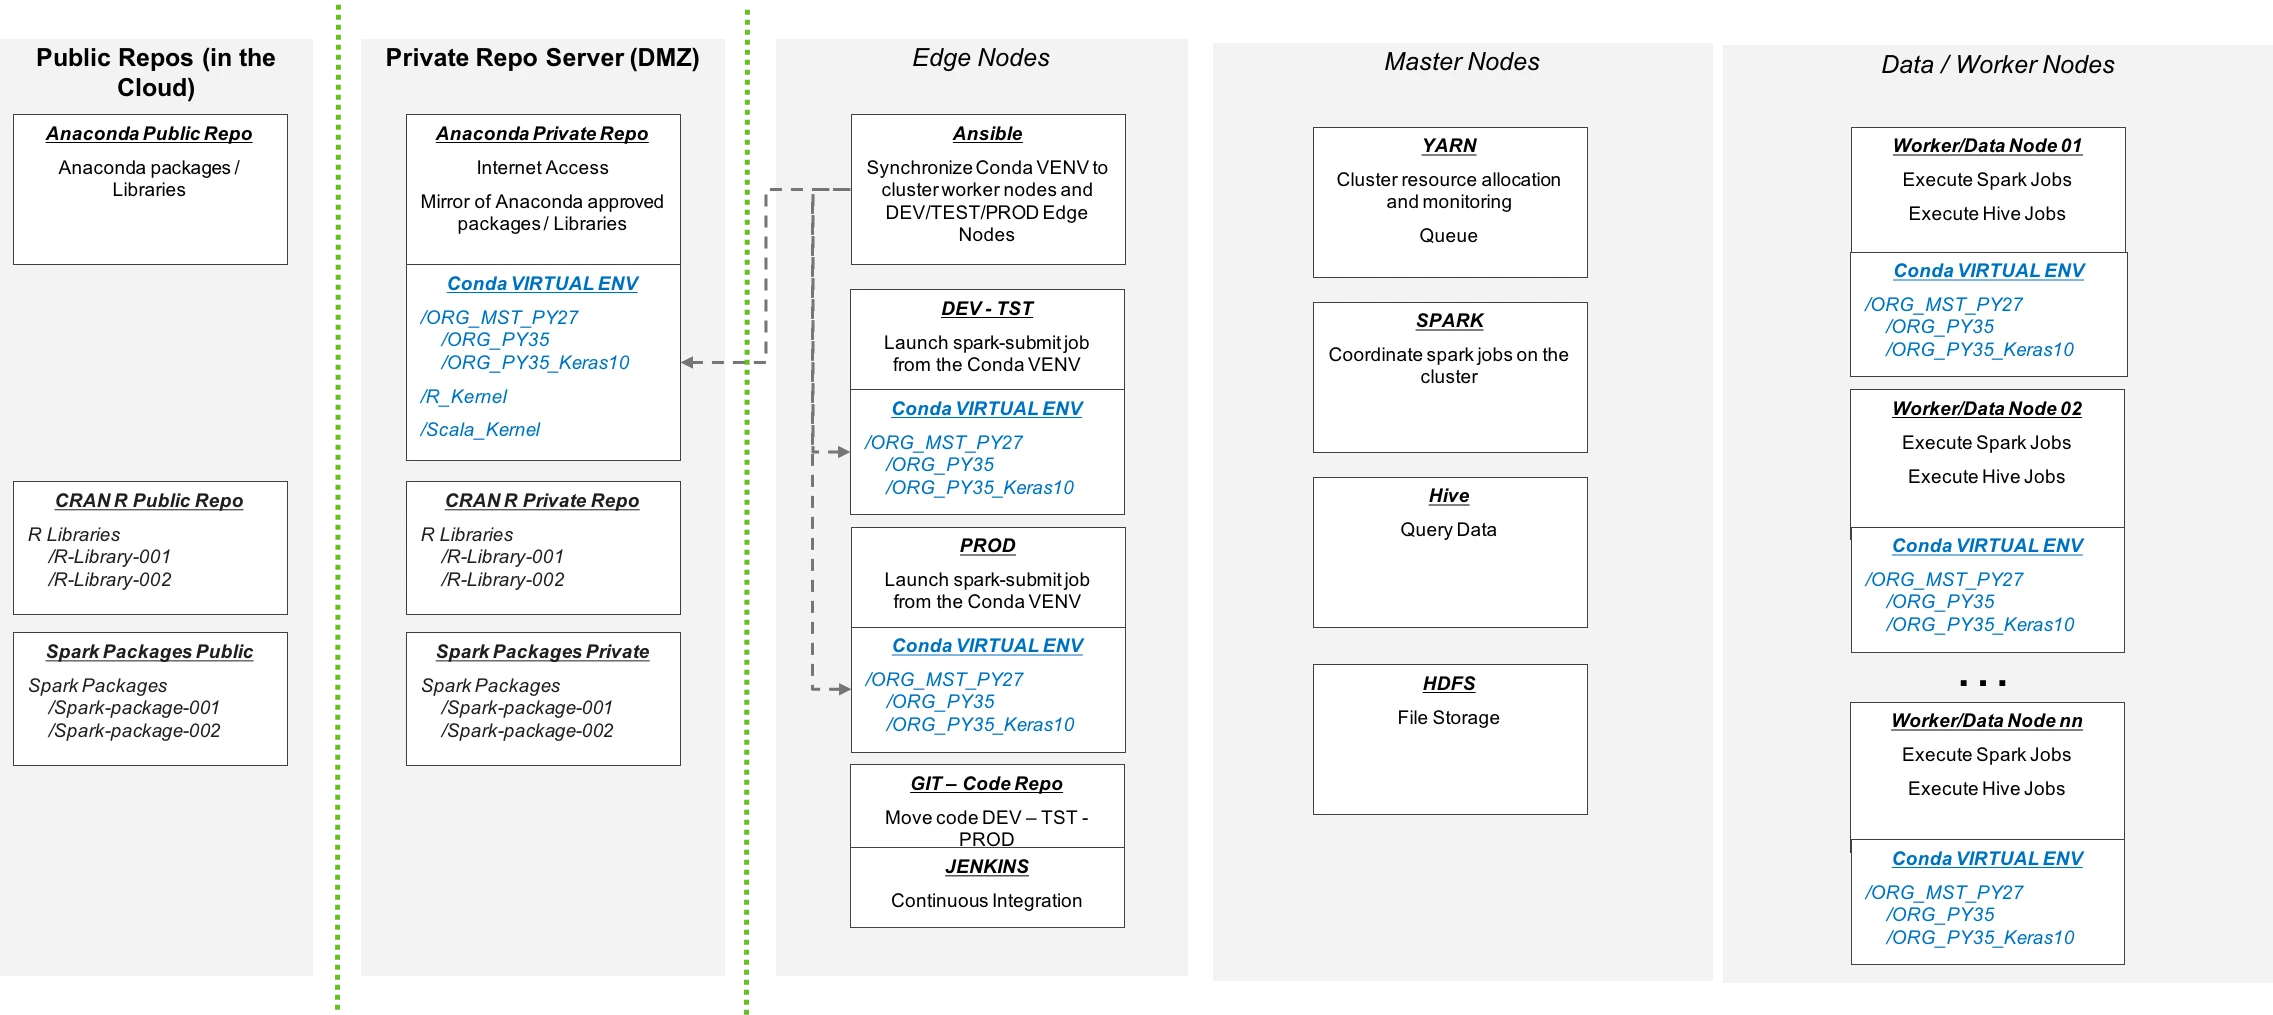
Building a Data Science Platform using Anaconda needs to be able to
- Launch PySpark jobs on the cluster
- Synchronize python libraries from vetted public repositories
- Isolate environments with specific dependencies to run production jobs using an older version of a package whilst simultaneously running new version of the package
- Launching notebooks and PySpark jobs using different kernels such as Python_2.7, Python_3.x, R, Scala
Framework of the Data Science Platform
- Private Repo Server
- Edge Nodes
- Dev
- Test
- Prod
- Ansible
- Git
- Jenkins
Building blocks of the Data Science Platform
- Anaconda
- Ansible
- Git
- Jenkins

