Our Community is getting an upgrade! To get everything ready for the relaunch, we’ll be placing the site in read-only mode starting September 21st.
We really appreciate your understanding while we get things set up behind the scenes. Catch up on all the exciting details about the move here.
Need help or have questions? Drop us a line at [email protected]
Created on 10-22-2015 03:02 PM - edited 08-17-2019 02:04 PM
Sometimes when running Hive on Tez queries, such as "select * from table" large output files are created that may swamp your local disk.
Error: Error while processing statement: FAILED: Execution Error, return code 2 from org.apache.hadoop.hive.ql.exec.tez.TezTask. Vertex failed, vertexName=Map 1, vertexId=vertex_1444941691373_0130_1_00, diagnostics=[Task failed, taskId=task_1444941691373_0130_1_00_000007, diagnostics=[TaskAttempt 1 failed, info=[Error: Failure while running task:org.apache.hadoop.util.DiskChecker$DiskErrorException: Could not find any valid local directory for output/attempt_1444941691373_0130_1_00_000007_1_10003_0/file.outat org.apache.hadoop.fs.LocalDirAllocator$AllocatorPerContext.getLocalPathForWrite(LocalDirAllocator.java:402)......], .... Vertex did not succeed due to OTHER_VERTEX_FAILURE, failedTasks:0 killedTasks:106, Vertex vertex_1444941691373_0130_1_01 [Map 3] killed/failed due to:null]DAG did not succeed due to VERTEX_FAILURE. failedVertices:1 killedVertices:2SQLState: 08S01ErrorCode: 2
This may indicate that your disk is filling up.
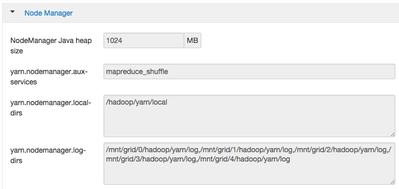
Check out where your yarn.nodemanager.local-dirs parameter is pointing to and increase disk space.
General tuning tips
General tuning done when debugging errors when too few, or too many, mappers are being ran:
Adjust input split size to vary the amount of data being feed to the mappers
Read How Tez Initial Parallelism Works and adjust tez.grouping.min-size, tez.grouping.max-size and tez.grouping.split-count accordingly
The number of map tasks for a Hadoop job is typically controlled by the input data size and the split size. There is some overhead to starting and stopping each map task. Performance suffers if a Hadoop job creates a large number of map tasks, and most or all of those map tasks run only for a few seconds.
To reduce the number of map tasks for a Hadoop job, complete one or more of the following steps:
Created on 05-07-2017 04:04 PM
I faced the same problem when trying to run hive query on both hive.execution.engine=mr or hive.execution.engine=tez.
The error looks like:
Vertex failed, vertexName=Map 1, vertexId=vertex_1494168504267_0002_2_00, diagnostics=[Task failed, taskId=task_1494168504267_0002_2_00_000000, diagnostics=[TaskAttempt 0 failed, info=[Error: Error while running task ( failure ) : attempt_1494168504267_0002_2_00_000000_0:org.apache.hadoop.util.DiskChecker$DiskErrorException: Could not find any valid local directory for output/attempt_1494168504267_0002_2_00_000000_0_10002_0/file.out at org.apache.hadoop.fs.LocalDirAllocator$AllocatorPerContext.getLocalPathForWrite(LocalDirAllocator.java:402) at org.apache.hadoop.fs.LocalDirAllocator.getLocalPathForWrite(LocalDirAllocator.java:150) at org.apache.hadoop.fs.LocalDirAllocator.getLocalPathForWrite(LocalDirAllocator.java:131) at org.apache.tez.runtime.library.common.task.local.output.TezTaskOutputFiles.getSpillFileForWrite(TezTaskOutputFiles.java:207) at org.apache.tez.runtime.library.common.sort.impl.PipelinedSorter.spill(PipelinedSorter.java:544)
The problem was solved by setting the following parameters:
In file hadoop/conf/core-site.xml parameter hadoop.tmp.dir
In file hadoop/conf/tez-site.xml parameter tez.runtime.framework.local.dirs
In file hadoop/conf/yarn-site.xml parameter yarn.nodemanager.local-dirs
In file hadoop/conf/mapred-site.xml parameter mapreduce.cluster.local.dir
Set a valid directory with sufficient free space available and the query will execute.