

Using Solr's Extracting Request Handler with Apache NiFi
The PutSolrContentStream processor in Apache NiFi makes use of Solr's ContentStreamUpdateRequest which means it can stream arbitrary data to Solr. Typically this processor is used to insert JSON documents, but it can be used to stream any kind of data. The following tutorial shows how to use NiFi to stream data to Solr's Extracting Request Handler.
Setup Solr
- Download the latest version of Solr (6.0.0 for writing this) and extract the distribution
- Start Solr with the cloud example: ./bin/solr start -e cloud -noprompt
- Verify Solr is running by going to http://localhost:8983/solr in your browser
Setup NiFi
- Download the latest version of NiFi (0.6.1) and extract the distribution
- Start NiFi: ./bin/nifi.sh start
- Verify NiFi is running by going to http://localhost:8080/nifi in your browser
- Create a directory under the NiFi home for listening for new files:
cd nifi-0.6.1
mkdir data
mkdir data/input
Create the NiFi Flow
Create a simple flow of GetFile -> PutSolrContentStream -> LogAttribute:
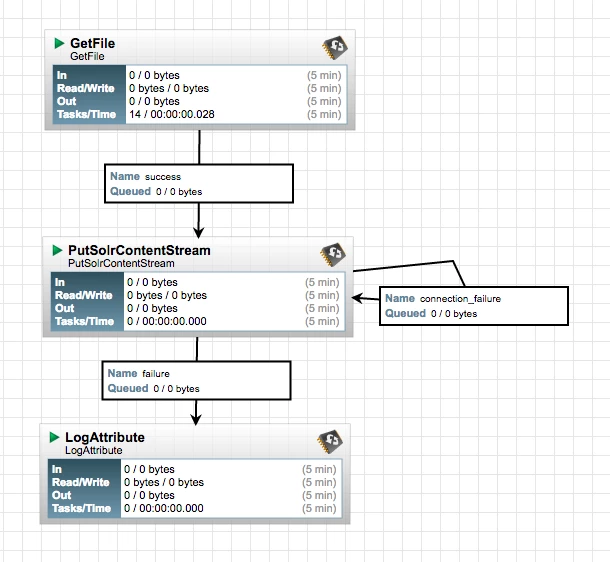
The GetFile Input Directory should be ./data/input corresponding the directory created earlier.
The configuration for PutSolrContentStream should be the following:
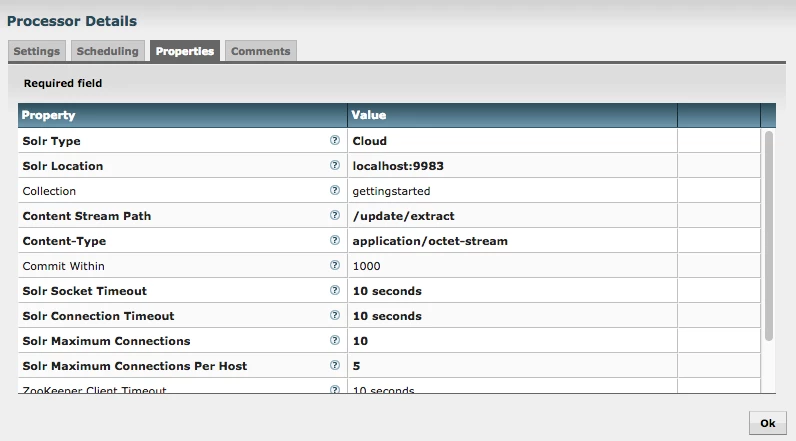
- The Solr Type is set to Cloud since we started the cloud example
- The Solr Location is the ZooKeeper connection string for the embedded ZK started by Solr
- The Collection is the example gettingstarted collection created by Solr
- The Content Stream Path is the path of the update handler in Solr used for extracting text, this corresponds to a path in solrconfix.ml
- The Content-Type is application/octet-stream so we can stream over any arbitrary data
The extracting request handler is described in detail here: https://wiki.apache.org/solr/ExtractingRequestHandler
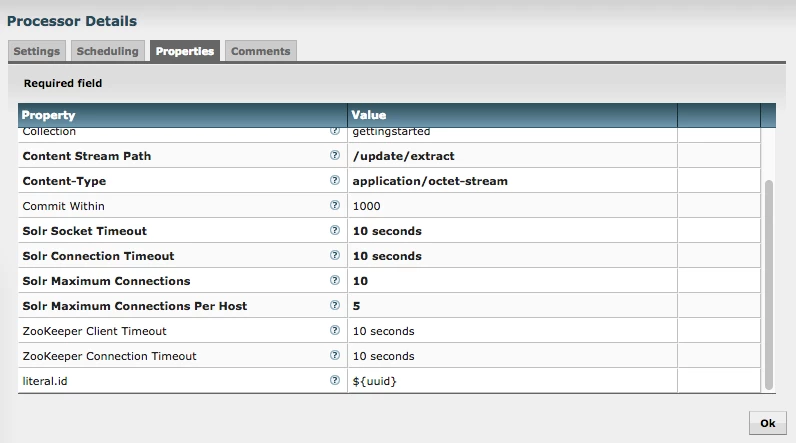
We can see that a parameter called "literal.id" is normally passed on the URL. Any user defined properties on PutSolrContentStream will be passed as URL parameters to Solr, so by clicking the + icon in the top-right we can add this property and set it to the UUID of the flow file:
Ingest & Query
At this point we can copy any document into <nifi_home>/data/input and see if Solr can identify it. For this example I copied quickstart.html file from the Solr docs directory. After going to the Solr Admin UI and querying the "gettingstarted" collection for all documents, you should see the following results:
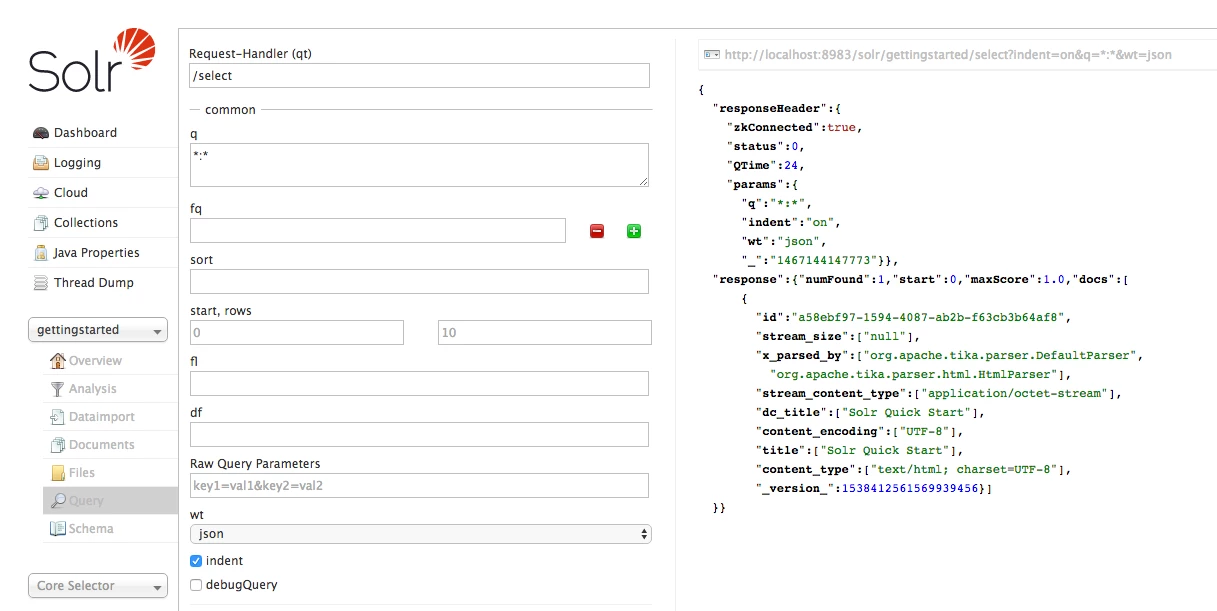
We can see that Solr identified the document as "text/html", extracted the title as "Solr Quick Start", and has the id as the UUID of the FlowFile from NiFi. We can also see the extraction was done using Tika behind the scenes.
From here you can send in any type of documents, PDF, Word, Excel, etc., and have Solr extract the text using Tika.

