

How to know why hbase regionserver fails?
I have a question about regionservers that go to bad health when I am writing data from Spark.
My question is: how do I know (in what logs to look exactly) what the cause is of the bad health?
BACKGROUND:
My spark job processes a month of some data and writes to hbase. This runs 1/month. For most months there are no problems.
For some months (probably with slightly higher traffic), I notice the regionservers go into bad health. The master notices this and when the server goes down, it moves all regions to another regionserver, and then it becomes healthy again. But as my writing is going on, the same happens to other regionservers and eventually my spark job fails.
I am confident my error in write is not due to corrupt data (like impossible UTC time or so), since sometimes this happens and then I clearly see in my spark logs "caused by value out of bounds". Now I see
21/03/17 15:54:22 INFO client.AsyncRequestFutureImpl: id=5, table=sometable, attempt=10/11, failureCount=2048ops, last exception=org.apache.hadoop.hbase.ipc.ServerNotRunningYetException: org.apache.hadoop.hbase.ipc.ServerNotRunningYetException: Server myregionserver4,16020,1615996455401 is not running yet
LOGS:
In the logs of the master I mainly see that it starts to identify all regions on the regionserver that is dying, and moves them.
In the logs of the regionserver around the time of failure I noticed a "org.apache.hadoop.hbase.io.hfile.LruBlockCache: totalSize=3.39 GB, freeSize=2.07 GB, max=5.46 GB, blockCount=27792, accesses=0, hits=0, hitRatio=0, cachingAccesses=0, cachingHits=0, cachingHitsRatio=0,evictions=1049, evicted=0, evictedPerRun=0.0
2021-03-17 15:52:31,442 INFO " but this might be not relevant.
This is the behavior of the #of regions for the regionserver that dies: it dies here 2x and the number of regions collapses as they are moved.
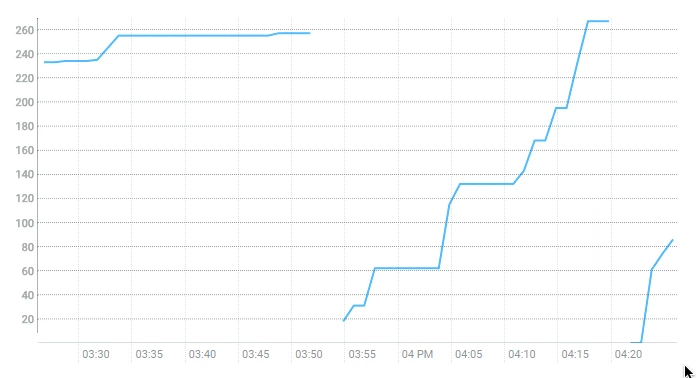 2 failures of regionserver at 3.54 and 4.15, followed by copying of regions
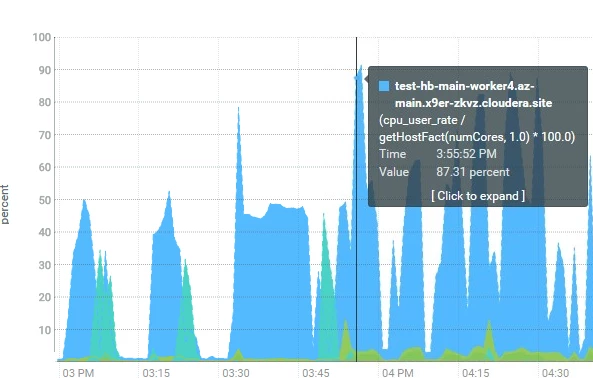
The cpu looks as follows (looks ok to me):
The memory looks like it comes close to the max available:
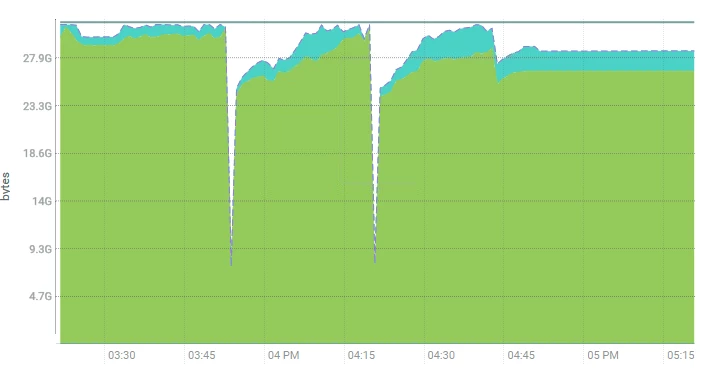
--> Maybe it fails because of memory? Like that all writes are first written to memory and the available memory has been used up? But I had expected to see this kind of error message somewhere (logs or cloudera manager).
These are the hbase settings (on CDP 7.2, hbase 2.2)
32 GB regionservers
Java Heap Size HBASE regionserver =20GB
hfile.block.cache.size =0.55
hbase.regionserver. memstore. global.size =0.25
hbase.bucketsize.cache=16GB
I am wondering how I can understand better what the reason is that the regionserver fails. Then I can change the hbase config accordingly.

