Creating HTML from PDF, Excel and Word Documents using Apache NiFi and Apache Tika
Extracting Text or HTML from PDF, Excel and Word Documents via Apache NiFi
This version has been tested with HDF 3.1 and Apache NiFi 1.5. This processor is using Apache Tika 1.17 and is a non-supported Open Source Community processor that I have written.
A user posted asking about HTML output, I took a look and it was easy so I added an option for that.
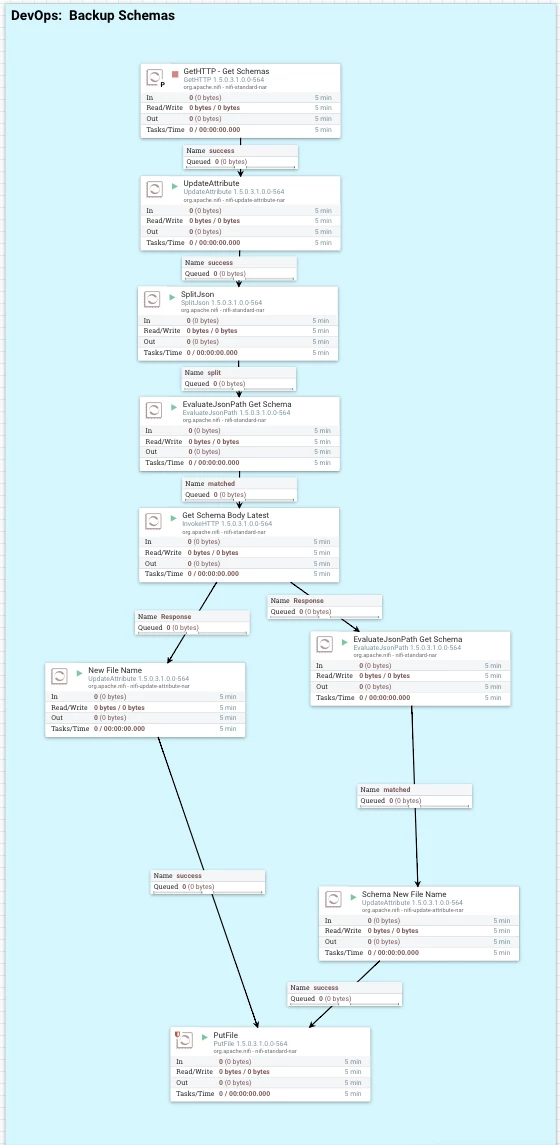
Apache NiFi Flow
You must download or build the nifi-extracttextprocessor nar and put in your lib, then you can add the processor.
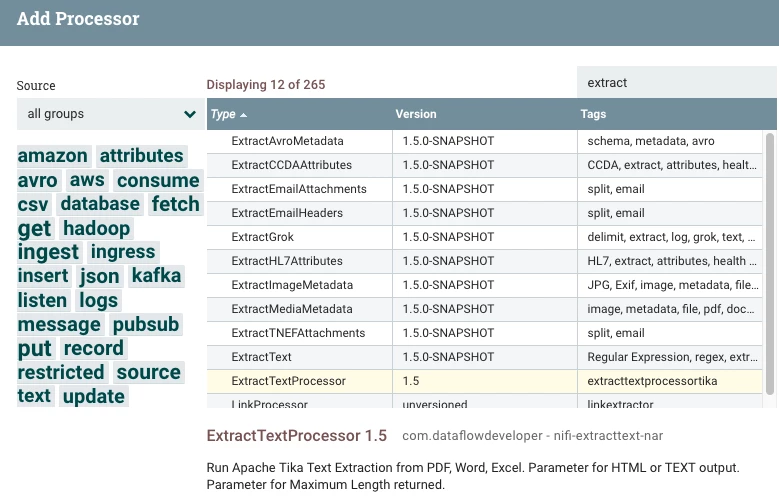
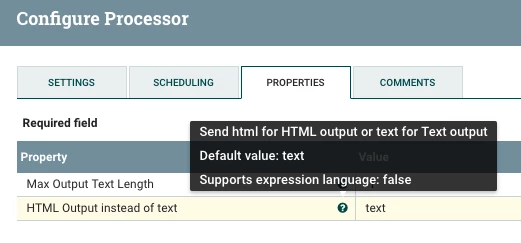
Select html or text
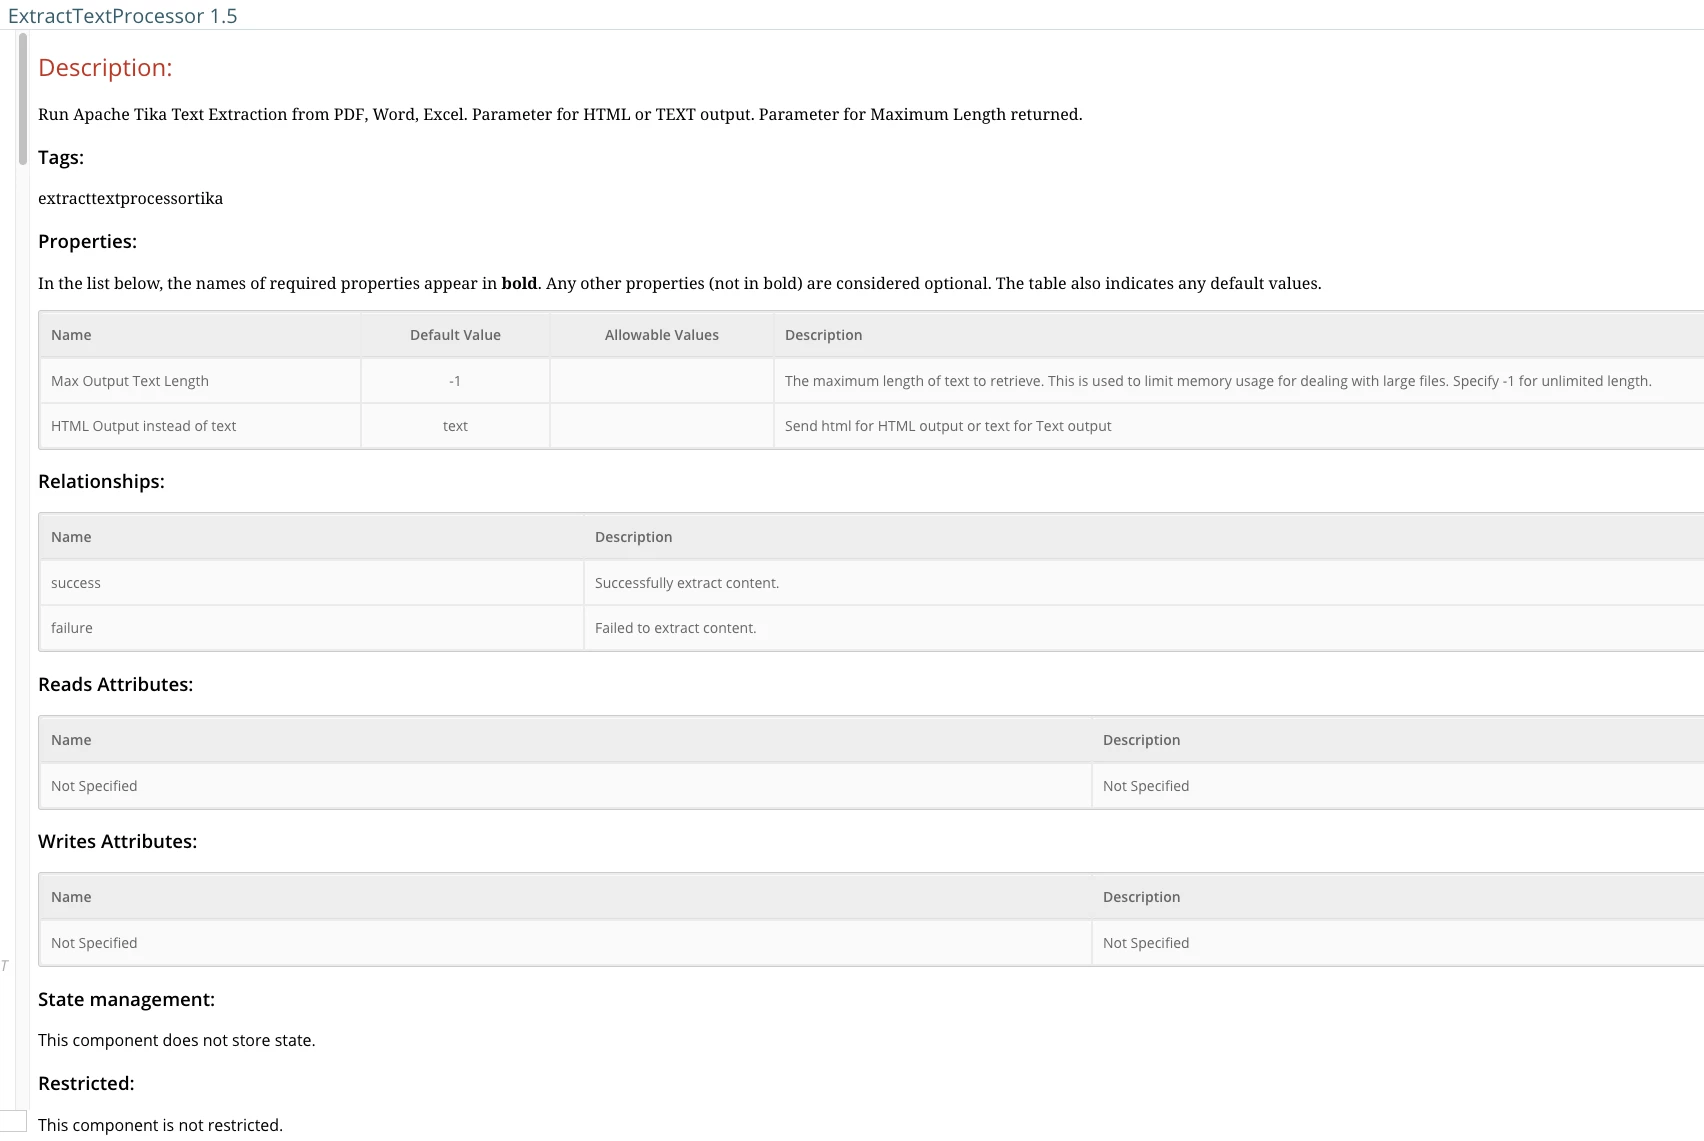
Here's is the autogenerate documentation:
You can see we set the output mime.type to text/html.
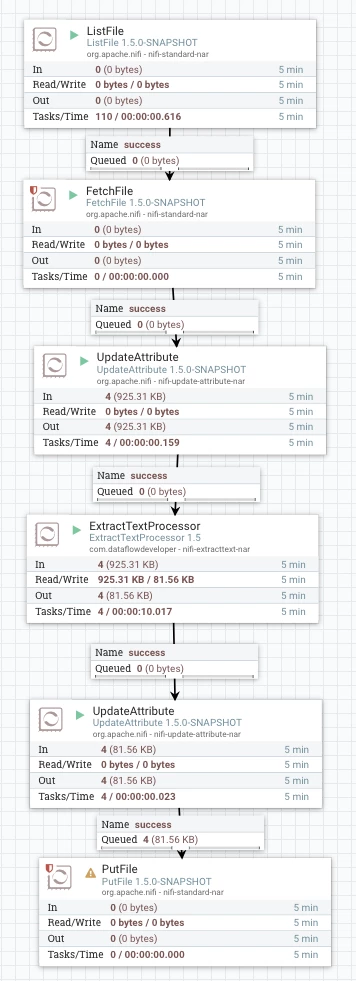
Apache NiFi Example Flow to Read a File and Convert to HTML
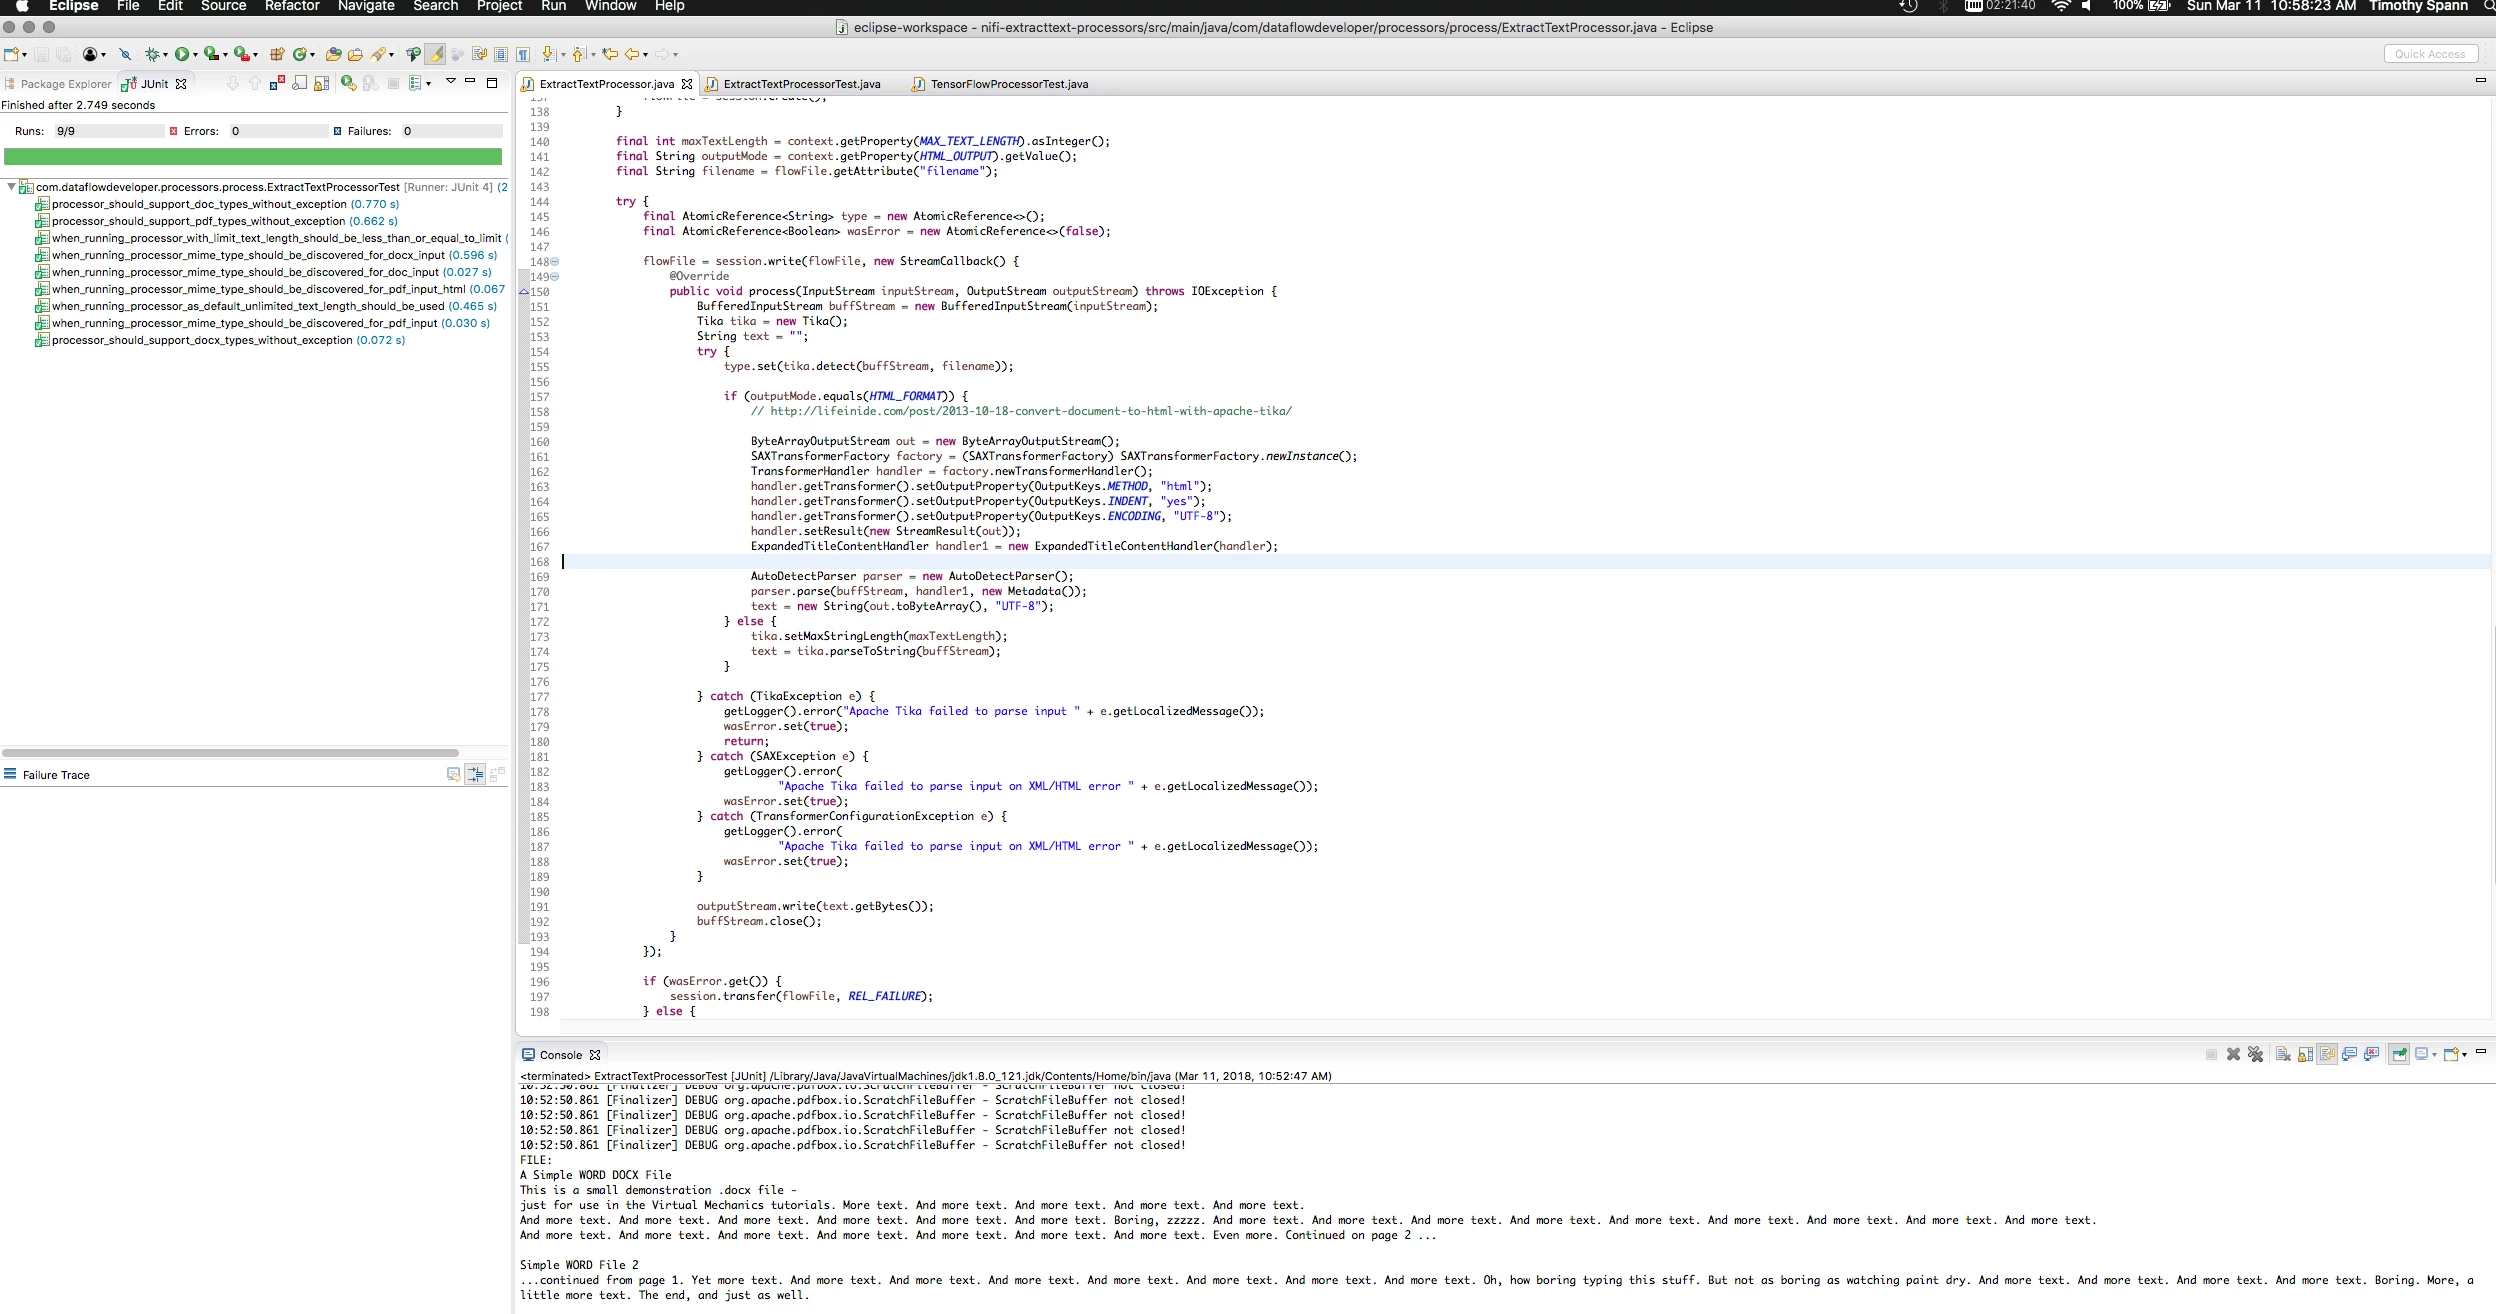
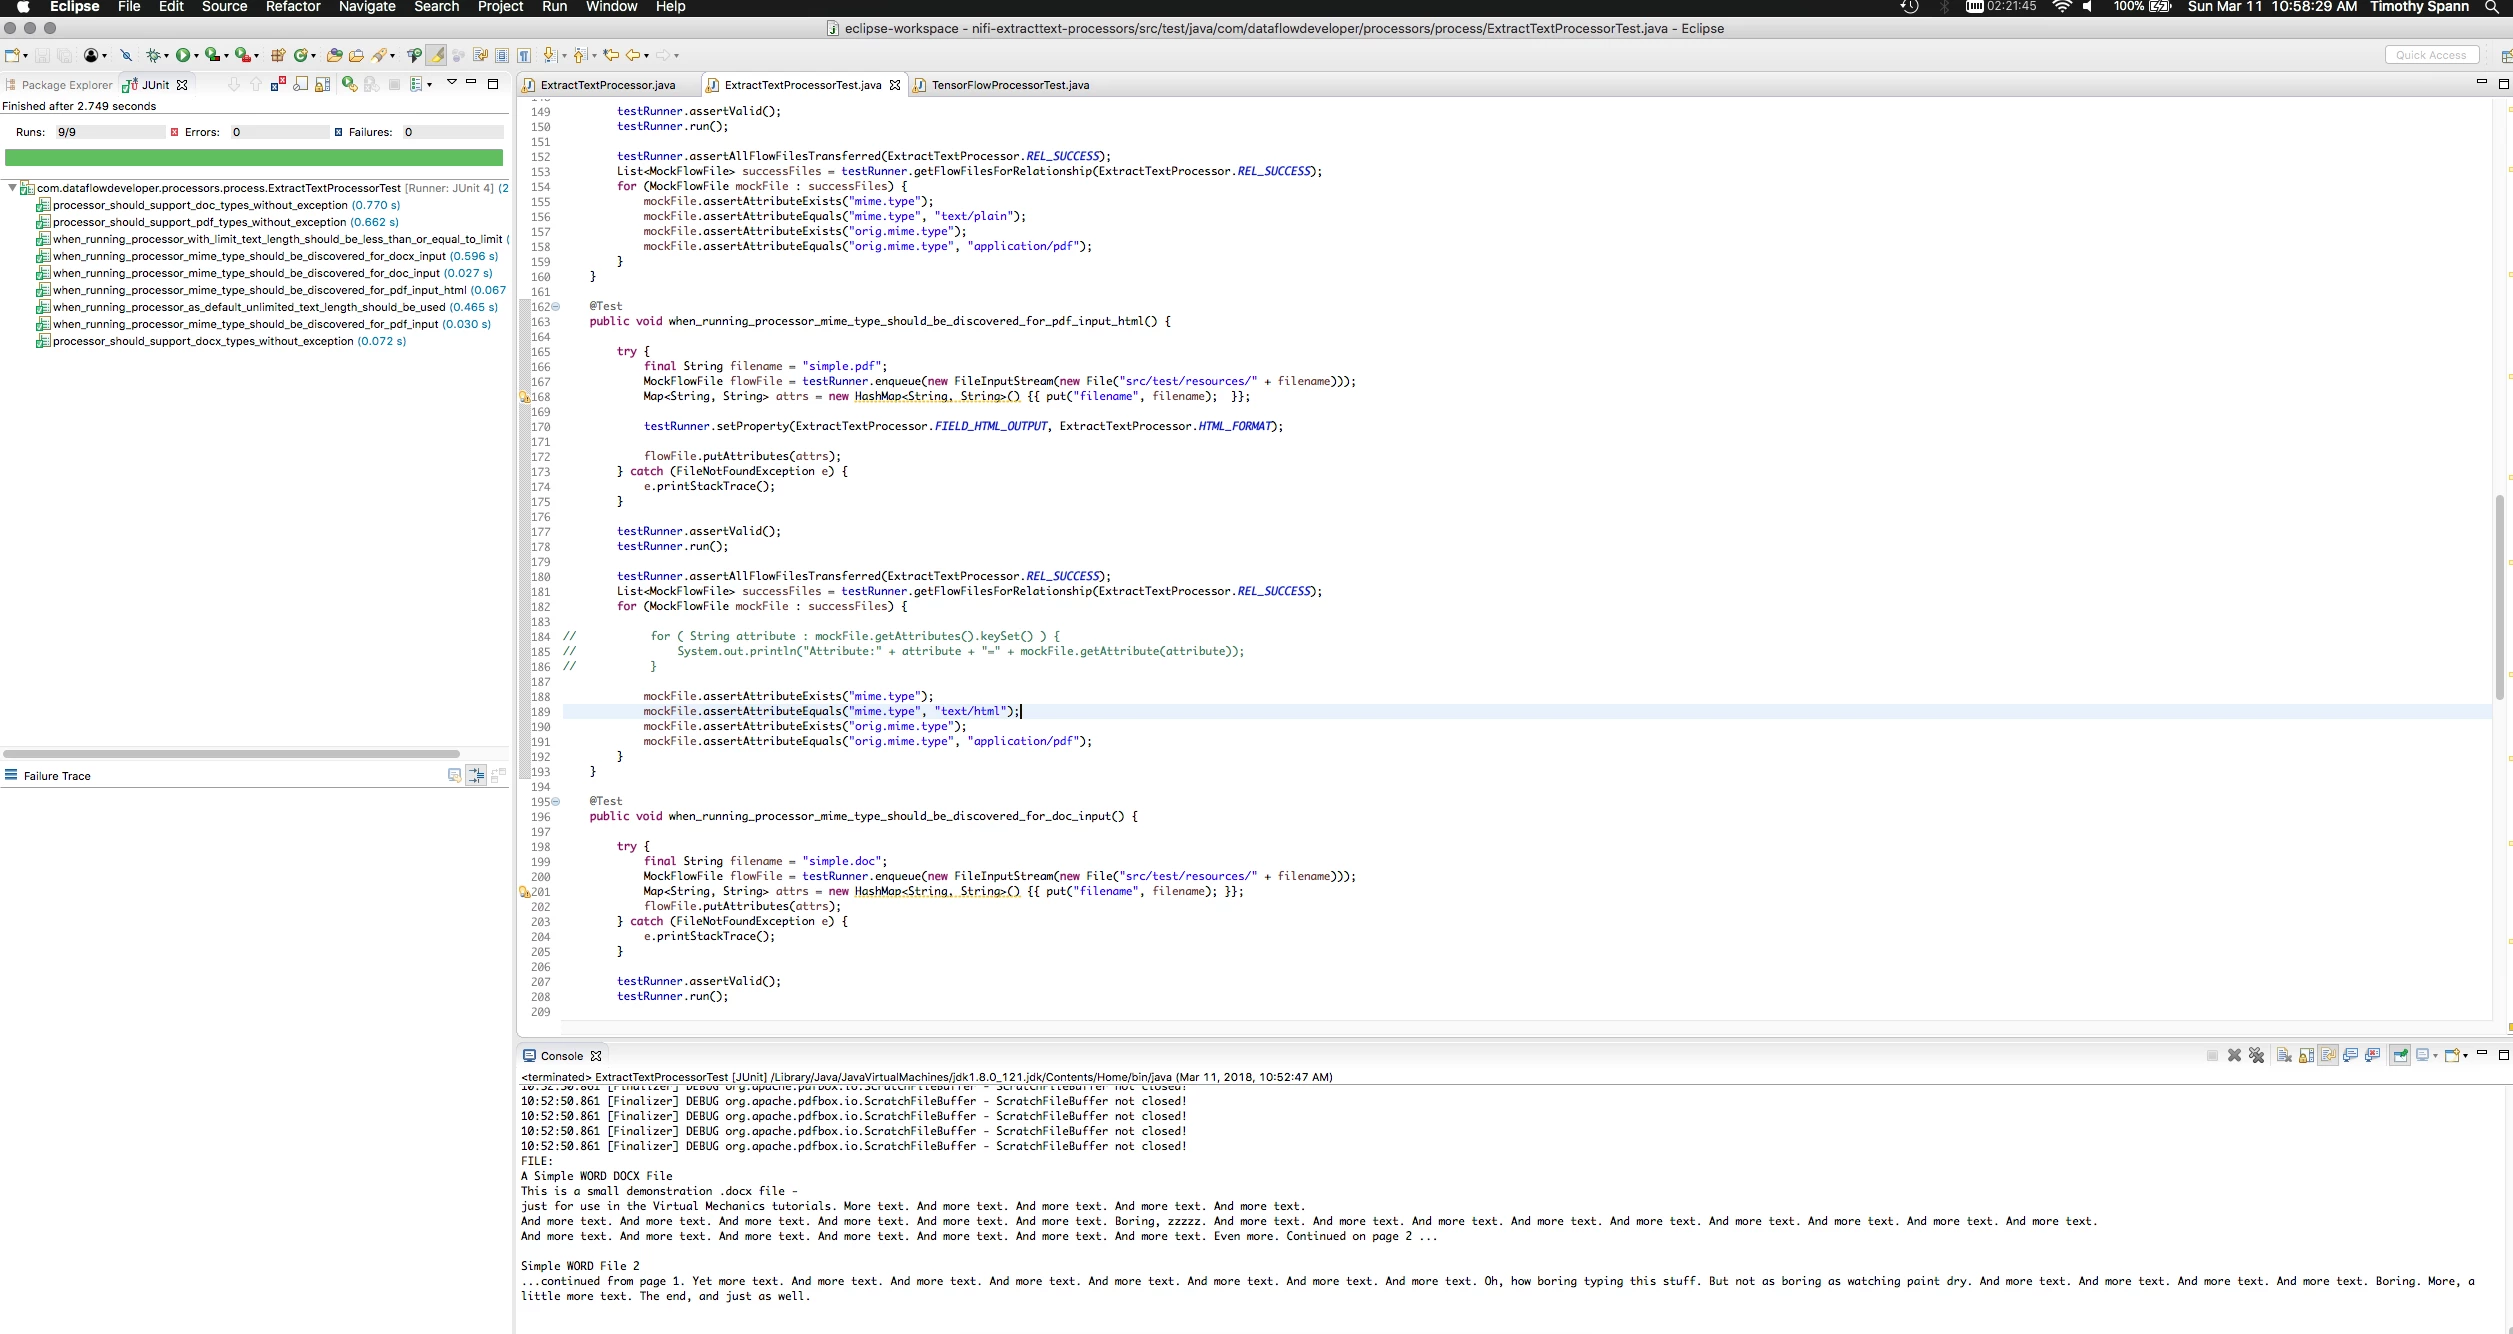
Source and Junit in Eclipse
Example Output HTML
<html xmlns="http://www.w3.org/1999/xhtml">
<head><meta name="pdf:PDFVersion" content="1.3"/>
<meta name="X-Parsed-By" content="org.apache.tika.parser.DefaultParser"/>
<meta name="X-Parsed-By" content="org.apache.tika.parser.pdf.PDFParser"/>
<meta name="xmp:CreatorTool" content="Rave (http://www.nevrona.com/rave)"/>
<meta name="access_permission:modify_annotations" content="true"/>
<meta name="access_permission:can_print_degraded" content="true"/>
<meta name="meta:creation-date" content="2006-03-01T07:28:26Z"/>
<meta name="created" content="Wed Mar 01 02:28:26 EST 2006"/>
<meta name="access_permission:extract_for_accessibility" content="true"/><meta name="access_permission:assemble_document" content="true"/><meta name="xmpTPg:NPages" content="2"/><meta name="Creation-Date" content="2006-03-01T07:28:26Z"/><meta name="dcterms:created" content="2006-03-01T07:28:26Z"/><meta name="dc:format" content="application/pdf; version=1.3"/><meta name="access_permission:extract_content" content="true"/><meta name="access_permission:can_print" content="true"/><meta name="pdf:docinfo:creator_tool" content="Rave (http://www.nevrona.com/rave)"/><meta name="access_permission:fill_in_form" content="true"/><meta name="pdf:encrypted" content="false"/><meta name="producer" content="Nevrona Designs"/><meta name="access_permission:can_modify" content="true"/><meta name="pdf:docinfo:producer" content="Nevrona Designs"/><meta name="pdf:docinfo:created" content="2006-03-01T07:28:26Z"/>
<meta name="Content-Type" content="application/pdf"/>
<title></title></head>
<body>
<div class="page"><p/><p>
A Simple PDF File

This is a small demonstration .pdf file -</p><p> just for use in the Virtual Mechanics tutorials. More text. And moretext. And more text. And more text. And more text.
</p><p> And more text. And more text. And more text. And more text. And moretext. And more text. Boring, zzzzz. And more text. And more text. Andmore text. And more text. And more text. And more text. And more text.And more text. And more text.</p><p> And more text. And more text. And more text. And more text. And moretext. And more text. And more text. Even more. Continued on page 2 ...</p><p/></div>

<div class="page"><p/><p>

Simple PDF File 2...continued from page 1. Yet more text. And more text. And more text.And more text. And more text. And more text. And more text. And moretext. Oh, how boring typing this stuff. But not as boring as watching paint dry. And more text. And more text. And more text. And more text.Boring. More, a little more text. The end, and just as well.

</p><p/></div></body></html>
Source Code:
https://github.com/tspannhw/nifi-extracttext-processor
NAR Release
https://github.com/tspannhw/nifi-extracttext-processor/releases/tag/html
Resources:
See Part 1: https://community.hortonworks.com/articles/81694/extracttext-nifi-custom-processor-powered-by-apach.html