Our Community is getting an upgrade! To get everything ready for the relaunch, we’ll be placing the site in read-only mode starting September 21st.
We really appreciate your understanding while we get things set up behind the scenes. Catch up on all the exciting details about the move here.
Need help or have questions? Drop us a line at [email protected]
Created on
02-02-2022
08:42 AM
- edited on
04-21-2026
01:01 AM
by
GrazittiAPI
In this article related to CDP Public Cloud, we will walk through steps required to be followed to read/ write to COD (Cloudera Operational Database) from Spark on CDE (Cloudera Data Engineering) using spark-hbase connector.
If you are looking to leverage Phoenix instead, please refer to this community article.
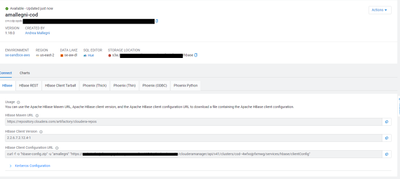
Spark in CDE to be able to talk to COD, would require the hbase-site.xml config of the COD cluster. Do the following steps to retrieve the same:
The configuration can be downloaded using the following curl command.
curl -f -o "hbase-config.zip" -u "<YOUR WORKLOAD USERNAME>" "https://cod--4wfxojpfxmwg-gateway.XXXXXXXXX.cloudera.site/clouderamanager/api/v41/clusters/cod--4wfxojpfxmwg/services/hbase/clientConfig"
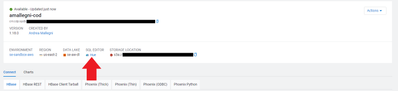
In this example, we are going to use COD database HUE to quickly create a new HBase table inside our COD database. Let's walk through this step by step:
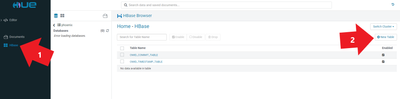
Once in Hue, click on the HBase menu item on the left sidebar, and then click on the New Table button in the top right corner:
Choose your table name and column families, and then click on the Submit button.
For the sake of this example, let's call the table 'testtable' and let's create a single column family called 'testcf'.
For Spark code complete examples, refer to HbaseRead.scala and this HBaseWrite.scala examples.
To configure the job via CDE CLI, perform these steps:
{
"mounts": [
{
"resourceName": "cod-spark-resource"
}
],
"name": "my-cod-spark-job",
"spark": {
"className": "<YOUR MAIN CLASS>",
"conf": {
"spark.executor.extraClassPath": "/app/mount/conf",
"spark.driver.extraClassPath": "/app/mount/conf"
},
"args": [ "<YOUR ARGS IF ANY>"],
"driverCores": 1,
"driverMemory": "1g",
"executorCores": 1,
"executorMemory": "1g",
"file": "spark-hbase-project.jar",
"pyFiles": [],
"files": ["conf/hbase-site.xml"],
"numExecutors": 4
}
}
Finally, assuming the above JSON was saved into my-job-definition.json, import the job using the following command:
cde job import --file my-job-definition.json
Please note the spark.driver.extraClassPath and spark.executor.extraClassPath inside the job definition, pointing to the same path we used to upload the hbase-site.xml into our CDE resource.
This is important since this way the hbase-site.xml will be automatically loaded from the classpath and you won't need to refer to it explicitly in your Spark code, hence, you will only need to do like this:
val conf = HBaseConfiguration.create()
val hbaseContext = new HBaseContext(spark.sparkContext, conf)
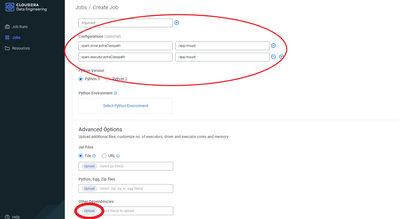
If you prefer using the UI instead, you'll have to take the following into account (please find the screenshot below):
Created on 07-19-2022 01:25 AM - edited 07-19-2022 01:25 AM
Please note the last screenshot has typos in it, while the article hasn't.
The correct configuration properties' names are the following (please note camel case):
spark.driver.extraClassPath
spark.executor.extraClassPath